

Your friendly neighborhood PhD in Robotics @CMU. Dexterous Manipulation | Generative Control | Reinforcement Learning
Pittsburgh, PA
Joined November 2014
- Tweets906
- Following645
- Followers660
- Likes24K






Pinned Tweet
Interaction with the real world is the major bottleneck in robot learning. So what would robot RL look like if we didn’t need to limit compute per interaction? Our latest work, Off-Policy Generative Policy Optimization (OGPO, accepted to ICML26) embarks on answering this question (spoiler alert: when done correctly, it helps massively!).
🧵(1/N)


Sarvesh Patil retweeted

Today, we introduce Priming Models, a new paradigm for training one-step generative models from scratch.
No diffusion teacher. No flow map. No CFG. No JVP.
We believe this work will challenge how we think about building one-step models.
Joint work with @sitanch, @du_yilun, @parkwbin03, Bohyung Han.
🔥 1.19 FID one-step on ImageNet 256×256 while using substantially less compute, e.g., 12X less than Drifting-B, 6X less than Drifting-L
🎨 Scales to text-to-image generation (GenEval 0.82)
🤖 World modeling on RT-1 / Bridge-V2
Priming Model is built on one core message: [Reconstruction pretraining --> Distributional post-training].
Video model encodings with recurrent architectures (e.g. GDNs) for latent memory compression (like workspace models) seem to be scaling with the use of world models at scale in multi-task settings!
The most impressive tasks for me are the seemingly innocuous ones, like wiping a table. Purely inferring actions from states that look more or less the same can render traditional MDP formulations unsuccessful. Using latent memory states to steer policy actions seems neat to convert the POMDP to an MDP!

Very cool work on distilling deliberative supervision from powerful but slow reasoning models into a "latent agentic harness" during training time!
These embedding spaces can then be used at inference time for policy steering with minimal latency, e.g. as latent memory modules for learned robot policies to recall and/or react to environment!

There’s lots of buzz around agentic harnesses for robots, particularly for long horizon tasks that require complex reasoning and memory. But what will it really take to turn a reasoning agent into a reactive, reliable and low-latency robot policy?
In our new paper, workspace models, we design a new memory architecture that acts as a latent harness for stronger reasoning models. Here’s why we think this might be the way forward:
(1/9)

Sarvesh Patil retweeted

Surprisingly a robot can sometimes do highly-dynamic manipulation by just copying the demonstration 🤠. Without any learning, cracking a whip or lassoing a cleat can be done directly from human motion capture. And amazingly this process can be nearly automatically implemented by GPT-6 Astra
Check out the full blog post with fun visuals: krishnasuresh.org/blog/2026/…
Turn on sound for full effect 🔈
Quick side note: the whips shown in this post are called signal/stock whips. These whips are built to generate the loud cracking noise when the tip breaks the sound barrier and is a popular art form: youtube.com/watch?v=ietBtr7s….
Sarvesh Patil retweeted

1/ We introduce TrackEverything: a 3D point tracker that tracks all points across all frames of long videos (1000+ frames).
Our key idea is to tie computation to unique 3D scene content rather than redundant 2D pixels in a video.
trackeverything.github.io
Sarvesh Patil retweeted

I am teaching a class this Fall on Embodied AI with Web-Scale Video Data
embodied-ai-with-videos.gith…
Excited to dive into my favorite (and some not-so-favorite but popular) keywords in AI!
Class lecture slides and materials will be all public for anyone to follow-along!
🤖 Made with AI

Sarvesh Patil retweeted

Robot WAMs typically predict future RGB latents trained for pixel reconstruction...but why stop there?
We propose Flex-π, a WAM that jointly denoises multiple visual streams jointly, enabling the WAM to inherit strong 3D, object-centric, AND spatio-temporal priors for action generation.
It's more demo-efficient than WAM and VLA baselines and can infer faster than π0.5.
(1/3)

Are VLAs dead?
No, and you don't have to choose between VLAs and WAMs.
Introducing Flex-π: a multi-stream world-action model (WAM) that jointly predicts future RGB, 3D pointmaps and DINO semantics with actions in training, then deploys as a VLA, a full WAM, or anything in between — all from a single checkpoint.
Website: flex-pi.github.io/
"""once someone launches an attack with an open-weights model whose guardrails they've removed, there will be many more defenders enabled by open-weights models to guard against it."""

Anthropic treats attacker access to open models as decisive while ignoring defender access to the same models. That is not a complete offense-defense analysis. Open weights also scale detection, hardening, attribution, and coordinated response.
A coalition is the stable game-theoretic equilibrium which defends against such attacks, and is *enabled* by open models.
Instead, they seem fixated on the single-step use case of an attacker removing guardrails from an open-weights model, but they seem to forget what naturally happens afterwards: once someone launches an attack with an open-weights model whose guardrails they've removed, there will be many more defenders enabled by open-weights models to guard against it.
Sarvesh Patil retweeted

Anthropic treats attacker access to open models as decisive while ignoring defender access to the same models. That is not a complete offense-defense analysis. Open weights also scale detection, hardening, attribution, and coordinated response.
A coalition is the stable game-theoretic equilibrium which defends against such attacks, and is *enabled* by open models.
Instead, they seem fixated on the single-step use case of an attacker removing guardrails from an open-weights model, but they seem to forget what naturally happens afterwards: once someone launches an attack with an open-weights model whose guardrails they've removed, there will be many more defenders enabled by open-weights models to guard against it.

There’s been a lot of speculation about where we stand on open-weights models. We’ve outlined our views in full here: anthropic.com/news/position-…


Sarvesh Patil retweeted
Introducing MotionForesight:
A very simple approach re-purposing video models for forecasting future 3D scene flow given a short observed video context
Trained with just 40k RGB human videos, it generalizes well to completely new home/office scenes!
1/n
Sarvesh Patil retweeted
I'm attending #RSS2026 for a couple papers/talks and as an RSS Pioneer! Please reach out to chat and/or come to the following:
- Monday 9:40 AM: Spotlight pres on detecting side effects at the Rethinking Safety Workshop by @ryanlindeborg (sites.google.com/andrew.cmu.…)
- Tues 4-5PM: Come visit my RSS Pioneers Poster! @RSSPioneers
- Wed 3:15PM: Robometer Reward Fxn talk + poster after by @yigitkkorkmaz and @aliangdw (robometer.github.io/)
- Thurs 3:15PM: TMRL pre-training for post-training talk + poster after by @matthewh6_ (weirdlabuw.github.io/tmrl/)
- Friday 9:30AM: Giving an invited talk at SemRob Workshop (semrob.github.io/)
- Friday 5:30PM: Invited talk at the Diffusion Workshop (rss2026-diffusion-robot-lear…) on TMRL

Sarvesh Patil retweeted

Presenting PTLD: an approach to learning tactile dexterous policies without ever simulating the tactile sensor.
Tactile is essential for performing highly dexterous manipulation. However, collecting tactile observations reliably has been a fundamental bottleneck: (1) teleoperating a multi fingered hand for dynamic tasks is challenging, making sim-to-real imperative, (2) one can’t realistically simulate tactile today
Henlo Frens,
I'll be presenting OGPO at #ICML2026 tomorrow (9 July)
Time ⏰: 2:30 to 4:15 PM KST
Location 📍: Hall A, Poster #202
Feel free to stop by for a chat on RL-finetuning, diffusion/flow policies, dexterous manipulation, or existential philosophy! ⛵️
simchowitzlabpublic.github.i…
Sarvesh Patil retweeted

Do we still need Uncertainty Quantification for robotics? What does uncertainty mean in the modern robotics paradigm?
💡 We are organizing a workshop “Rethinking Uncertainty for Modern Robotics Paradigms” @ IROS 2026
Submit your work by Aug 23! 👇 (rethinking-uncertainty.githu…)

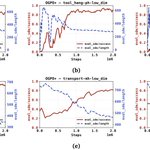
When done naively, aggressive PPO policy extraction tends to over-optimize Q-functions which can result in an offline-to-online policy “dip” that reduces sample efficiency. We overcome this with two key innovations:(1) An online Success Buffer for supervised finetuning (SFT) on successful actions, (2) a new technique we call “conservative advantages” which selects the “least extreme” advantages for PPO optimization. Both improve OGPO’s overall stability during online RL.
(6/N)

To summarize, we highlight 6 key takeaways from the success and design of OGPO:
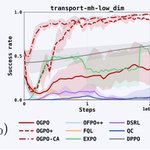
Takeaway #1: Even within the standard Actor-Critic template, simply increasing training time computation can improve sample efficiency by an order of magnitude.
Takeaway #2: Better policy extraction alone can yield substantial improvements in training stability and sample efficiency.
Takeaway #3: Surprisingly, full policy finetuning can increase action diversity and enhance policy exploration, despite the fact that one is only trying to maximize sparse reward (with no explicit entropy penalties!). Understanding this phenomenon is an exciting direction for future work
Takeaway #4: Zero-order policy policy optimization can be incredibly effective given sufficient computation as it avoids unstable gradients through denoising steps or critics, improving performance on high-precision tasks. It also enables advantage-curation techniques, such as the conservative advantages
Takeaway #5: Targeted interventions, like imitating successful trajectories and the modified “conservative advantages” are both reliable, preserve training efficiency, and ameliorate the need for task-specific hyperparameter tuning.
Takeaway #6: While there are many options for fine-tuning a multi-step GCP (AWR, FPO, etc), simple PPO is the most effective, most stable, and requires the least amount of hyperparameter finetuning.
(9/N)


This was an amazing collaboration with @mitsuhiko_nm, with tremendous help from Manan Agarwal, Shashwat Saxena, and @Jesse_Y_Zhang! I would like to thank all the collaborators for their insightful discussions that helped us think widely about the scope of the project. Special thanks to @abhishekunique7, Hongkai Dai, Paarth Shah for all their guidance and insights throughout the project. And finally I would like to express gratitude to my advisor @max_simchowitz for his incredible leadership, mentorship, and encouragement to pursue our intellectual curiosity on understanding the myriad reasons behind OGPO’s performance. I would especially like to thank @max_simchowitz for all his advice and intuition-development-exercises that I hope helps make reinforcement learning with generative models more accessible! :D
Paper: arxiv.org/abs/2605.03065
Code: github.com/simchowitzlabpubl…
Website: simchowitzlabpublic.github.i…
(10/10)
