
Assistant Professor @mldcmu. Formerly: Postdoc @MITEECS, PhD @Berkeley_EECS, Math Undergrad @Princeton. New to Twitter. https://xitter.cf/t.co/67bMOAyqK6
Joined May 2024
- Tweets170
- Following167
- Followers3K
- Likes592


Pinned Tweet
Personal Update: I'll be splitting my responsibilities between CMU and Amazon FAR over the next year. I'm convinced we need a unified understanding of how the axes of scale, data, optimization and control interact for robot learning, and am excited for my lab + FAR to push towards uniting the "science of robot learning" with the "science of deep learning" at scale.
Please reach out if you are looking for a full-time position building powerful multimodal AI models for deployment on hardware, and if you are intern looking to tinker and do good science on architectures, optimizers, data, tokenization, VLAs, WAMs and more!
There seems to be fear reasoning models will trivialize research on robot learning architectures, algorithms, etc...
I disagree. Innovation comes from constraints, and robotics imposes a ton of then. Our new paper, led by @DashoraNitish , suggests a really promising new direction for meeting the constraints of real robot deployment whilst capturing the "intelligence" of agentic reasoning models. Check it out!

There’s lots of buzz around agentic harnesses for robots, particularly for long horizon tasks that require complex reasoning and memory. But what will it really take to turn a reasoning agent into a reactive, reliable and low-latency robot policy?
In our new paper, workspace models, we design a new memory architecture that acts as a latent harness for stronger reasoning models. Here’s why we think this might be the way forward:
(1/9)

everyone talks about AI model alignment, but what about AI oligopoly alignment?
Suppose a super powerful A̵I̵ ̵m̵o̵d̵e̵l̵ AI company thought it was acting in the public interest but was actually undermining it. How would we stop i̵t̵ them?
thoughts on robot/generative RL: the best regularization is more expressive updates, not less. What we've learned from the LLM community is that data and model scale lead to the most informative and stable gradients, and we should do the same in robotics.
Max Simchowitz retweeted

A mathematical breakthrough used to effectively be defined as solving a problem that many smart people failed at for N years. Now a subset of those problems fall to LLMs with effectively zero human input and each gets announced as a breakthrough. Fair enough, by the old standard it is one.
But the difficulty by which a breakthrough was defined, was measured against human effort. If a magic wand now solves them, how do we redefine difficulty in terms of the magic wand? A hard problem is one that resists the wand. Which leaves us with the actual question:
What is now considered a breakthrough?
Robotics people, follow @aran_nayebi . He's been asking some really fundamental questions about what morphologies we need for robotics, and comes from a really unique bio/neuro perspective. Check this work out!

It's clear that to unlock the next big advances in robotics, we need at-scale tactile sensing. For the past year, in collab w/ @gs_ai_, we've been working on perhaps the most wide-ranging, realistic tactile simulator to ask:
*What should the future of robot hands look like?*
Max Simchowitz retweeted

Diffusion / flow-based robot policies unlock two axes of test-time scaling: sequential (denoising steps) and parallel (samples). Both improve performance but cost latency on a robot, and knowing which to scale a priori is often unclear. ELASTIC learns it via RL!
pro or con: frontier labs who hire a phd student should pay the student’s advisor commission for their mentorship 🙃
Max Simchowitz retweeted

I am starting a blog about deep learning theory and its value to practitioners! First post is about Adam, broken convergence proofs, and what theory can contribute when stuff just works anyways without it. Subscribe on Substack if you like it! undertheassumptions.substack…
🤖 Made with AI

As a PhD student, I was told not to work on deep RL - too full of hacks and alchemy" But after a year or two of working in this area, I’ve come to (deeply?) appreciate all of the thoughtful research that’s gone into understanding what/why things work and how to make them better.
My lab (joint with @abhishekunique7) took what we’ve learned by reading this body of literature to answer the question: what are the actual best-practices for finetuning a diffusion/flow/generative robot policy (for now, in sim)? Under one set of constraints - ample compute but limited time on your robot - @servo97 paper gives a pretty compelling answer.

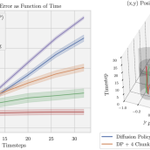
Interaction with the real world is the major bottleneck in robot learning. So what would robot RL look like if we didn’t need to limit compute per interaction? Our latest work, Off-Policy Generative Policy Optimization (OGPO, accepted to ICML26) embarks on answering this question (spoiler alert: when done correctly, it helps massively!).
🧵(1/N)

I think TL;DR our paper should be viewed as a proof of concept: there is more room to scale compute and innovate on policy regularization/stabilization. Expressive updates can mean more training stability and exploration, not less. And better policy extraction can be a really, really powerful tool (thanks for sticking with me to the end /n)
So should you use it? Well, of course, that depends on how much compute you have. We are still working to get OGPO cooking on VLAs, where the costs of compute/inference start to add up, and are testing on real hardware. We also are excited to see OGPO for an off-line / batch-RL setup (stay tuned ; /n).
Ok so what did we learn? OGPO is a useful algorithmic template for full-policy finetuning algorithms. It is also compatible with greater compute scaling for more stable training (batch denoising trajectory sampling reduces variance), and is compatible with surprisingly performant techniques to further improve training behavior (success buffer conservative advantages). It trains quickly even if pre-training data are low and of mixed quality, and encourages *more exploration*, not less (the summary / n).
Nope! Actually, this is the coolest thing. OGPO *increases exploration*. Magically (we don’t enitrely understand why), it pushes variances orthgonal to Q gradients. This means that exploration squeezes the exploration distribution along axes the matter, but preserves exploration across axes where the critic is indifferent . Said otherwise: expressive updates can explore more! (the cool part / n)


Okay, but surely you are gonna kill diversity with this full-policy finetuning? If you didn’t have a great BC starting point your policy, this PPO/GRPO-ish frankenstein will make your policy collapse, right? (almost at the cool part / n)
And why PPO? There are other ways to optimize a denoising MDP, like AWR weighting of likelihood rations, FPO/FPO++, or even reweighting the flow matching loss. But PPO seems to work best. Why? See the paper. But TL;DR - use the best *on-policy* RL algorithm you got for policy extraction. (keep reading /n)
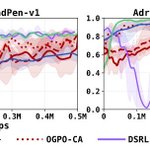
Why is this cool? Well these sample efficiency gains are coming *purely from pushing more FLOPs onto policy extraction*. We always think critic learning or sparse rewards or exploration collapse or plasticity are the bottleneck, but a lot of these challenges seem to be indirectly addressable thru the right policy extractions. I have more takes here but will save for offline (meh/n)