

PhD on high troughput bioinformatics @ ETH Zurich; IMO, ICPC, Xoogler, Rust, road-cycling, hiking, wild camping, photography https://xitter.cf/t.co/wBv2zN4F80
- Tweets1.9K
- Following81
- Followers1.2K
- Likes4.7K

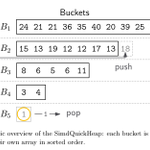




ALT Priority queues are data structures that maintain a dynamic collection of elements and allow inserting new elements and removing the smallest element. The most widely known and used priority queue is likely the implicit binary heap, even though it is has frequent cache misses and is hard to optimize using e.g. SIMD instructions. We introduce the SimdQuickHeap, a variant of the QuickHeap that was introduced by Navarro and Paredes in 2010. As suggested by the name, the data structure bears some similarity to QuickSort. We modify the data layout of the original QuickHeap to have all pivots adjacent in memory, with elements between consecutive pivots stored in dedicated buckets. This allows efficient SIMD implementations for both partitioning of buckets and scanning the list of pivots to find the bucket to append newly inserted elements to. The SimdQuickHeap has amortized expected complexity O(log n) per operation, which improves to O(frac 1Wlog n) in non-degenerate cases, where W is the n


ALT Screenshot of some C++ code: ``` // returns a mask with bits [ n , n + size ) set to 1, eg // MakeMaskRange( 4, 2 ) -> 0x030ull uint64_t MakeMaskRangeLoop( unsigned lowest, unsigned size ) { uint64_t mask = 0; for ( unsigned i_bit = lowest; i_bit < lowest + size; ++i_bit ) { mask |= 1 << i_bit; } return mask; // OBVIOUSLY THIS IS NOT HOW ANYONE WOULD ACTUALLY IMPLEMENT THIS, // IT'S JUST TO TEST THE COMPILER, DON'T @ ME } ```

ALT lowest$ = 8 size$ = 16 unsigned __int64 MakeMaskRangeLoop(unsigned int,unsigned int) PROC ; MakeMaskRangeLoop, COMDAT xor r9d, r9d lea eax, DWORD PTR [rcx+rdx] cmp ecx, eax jae SHORT $LN10@MakeMaskRa mov r8d, 1 mov eax, edx rol r8d, cl npad 11 $LL4@MakeMaskRa: mov ecx, r8d or r9, rcx rol r8d, 1 sub rax, 1 jne SHORT $LL4@MakeMaskRa $LN10@MakeMaskRa: mov rax, r9 ret 0 unsigned __int64 MakeMaskRangeLoop(unsigned int,unsigned int) ENDP ; MakeMaskRangeLoop

ALT screenshot of a very large disassembly stream full of insane things like .LBB1_12: vmovd xmm0, edi vpbroadcastd xmm2, dword ptr [rip + .LCPI1_1] vpbroadcastd xmm3, dword ptr [rip + .LCPI1_2] vpbroadcastd xmm4, dword ptr [rip + .LCPI1_3] vpbroadcastd xmm5, dword ptr [rip + .LCPI1_4] vpbroadcastd xmm6, dword ptr [rip + .LCPI1_5] mov esi, edx vpxor xmm7, xmm7, xmm7 vpxor xmm8, xmm8, xmm8 vpxor xmm9, xmm9, xmm9 and esi, 48 lea r8d, [rdi + rsi] mov eax, esi vpbroadcastd xmm0, xmm0 vpaddd xmm1, xmm0, xmmword ptr [rip + .LCPI1_0] vpxor xmm0, xmm0, xmm0 .LBB1_13: vpsllvd xmm13, xmm5, xmm1 vpaddd xmm10, xmm1, xmm2 vpaddd xmm11, xmm1, xmm3 vpaddd xmm12, xmm1, xmm4 vpaddd xmm1, xmm1, xmm6 add eax, -16 vpsllvd xmm10, xmm5, xmm10 vpsllvd xmm11, xmm5, xmm11


