
Here because permission isn't required.
Dulin, Ireland, Earth
Joined August 2025
- Tweets690
- Following561
- Followers184
- Likes910



Paulie τ retweeted

Not every compute subnet in bittensor:native is the same.
@green_compute_ (SN110) deploys permanent enterprise-grade GPUs on 100% green power, already serving real clients and generating revenue.
240 more 5090s GPU's about to come online.
This is infrastructure with a business attached, not emissions looking for a product.

Paulie τ retweeted
Good headline, but I’m not fully buying the comfort blanket. The AI race is full steam ahead. Anthropic, OpenAI, Google, Meta and the rest are all chasing the next jump in capability. Each jump will come with a fresh dose of “responsible AI” messaging. The real question is simple: can oversight stop deployment, or is it just there to make the race look safer? #ai
Paulie τ retweeted

What happens when the compute behind AI stops living in one company's basement?
Last month @chutes_ai served 1.23 Trillion Tokens. No data center. No single owner.
Open models running on GPUs worldwide, live on Bittensor.
A few giants want you renting AI forever. We went the other way.
Would you plug in? 👇


Paulie τ retweeted
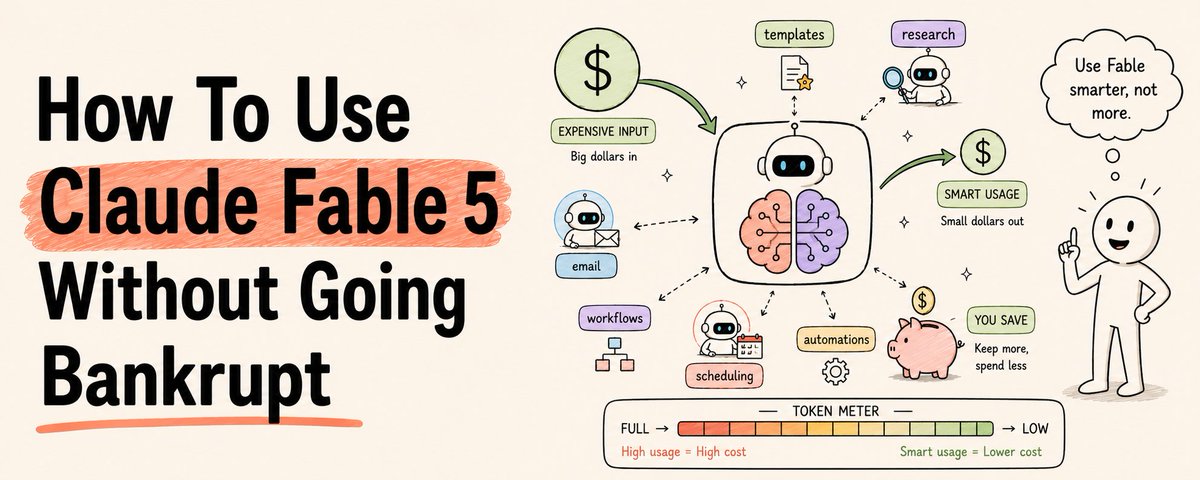
Holy sh*t, developers are going to lose their minds over this.
A Netflix engineer just open-sourced a tool that cuts your Claude API costs by up to 95%.
→ Intelligently shrinks logs, JSON, and code
→ Perfectly preserves logic accuracy
→ Keeps 100% of your data local
→ Stops Opus-tier models from wasting tokens on boilerplate
It already crossed 56K stars, which says a lot.
100% free and open-source.
repo in 🧵↓


Paulie τ retweeted
🚨CIRCLE SHARES CRASH AS MAJOR CONSORTIUM LAUNCHES RIVAL STABLECOIN!
$CRCL shares dropped sharply after Open Standard unveiled Open USD, a new dollar stablecoin backed by more than 140 companies including Visa, Stripe, Mastercard, BlackRock, Coinbase, and others.
The project stands out for its consortium model, partners get a share of reserve earnings and governance rights, rather than one issuer capturing everything.

🚨MAJOR CONSORTIUM LAUNCHES OPEN USD STABLECOIN!
A broad alliance of financial giants, including Visa, Stripe, Mastercard, BlackRock, Coinbase, and dozens of others, has officially announced Open USD (OUSD), a new stablecoin designed for global payments and commerce.
Key features per the launch announcement:
- Zero mint/redeem fees and no volume caps for businesses
- Revenue sharing, partners earn from the reserves (minus a small management fee)
- Collaborative governance via an independent entity (Open Standard) with a board of partners
The project aims to create a more open, scalable, and business-friendly alternative in the stablecoin space, with launch expected later in 2026.


Paulie τ retweeted

code is law in crypto, and as a consequence there was >$700m of exploits in the last couple of months. much of these stemmed from under (or un)audited smart contract code - particularly in relation to off-chain systems (1/3)
Paulie τ retweeted

What can a 27B dense model actually do in 2026?
Qwen3.6-27B TEE on Chutes. Apache 2.0. Multimodal. 262K context, extensible to 1M.
The benchmarks against Qwen's own previous flagship (397B MoE):
SWE-Bench Verified 77.2 vs 70.4
SWE-Bench Pro 53.5 vs 48.4
GPQA Diamond 87.8 vs 84.1
A 27B dense model beating a 397B MoE on every coding eval the vendor publishes.
$0.50 in / $2.00 out. Inside a TEE.
Run 5M in + 5M out per day on Chutes for just $12.50.
What workloads are you still running on bigger models out of habit?
chutes.ai/app/chute/7aa5e899…

Paulie τ retweeted

Bittensor Ecosystem Highlights of the Week #60
// SUBNET UPDATES & ACHIEVEMENTS
➤ @chutes_ai SN64
They’re now collaborating with @AIxC_Official, a Nasdaq-listed AI agent platform choosing Chutes as their compute provider.
(bit.ly/42XZgBg)
Chutes Chat got a rebuild, with web search now built in, plus new image generation and image editing features.
(bit.ly/42qjXG0)
➤ @SynthdataCo SN50
They’re launching Synth LLM for Traders on Polymarket, Limitless, Hyperliquid, and Deribit.
(bit.ly/3PyMiXE)
➤ @TargonCompute SN4
They announced the Targon Supply Portal, which allows compute suppliers to easily onboard and start monetizing their idle compute capacity.
(xitter.cf/TargonCompute/status/2…)
➤ @almanac_market SN41
They introduced Alma, their AI trading partner built on top of Almanac’s analytics and Polymarket data.
(xitter.cf/almanac_market/status/…)
➤ @webuildscore SN44
@manakoai’s new website is now live.
(xitter.cf/manakoai/status/205206…)
They also unveiled their new cricket ball tracking challenge.
(xitter.cf/webuildscore/status/20…)
➤ Distil SN97
Arbos shared that a 4B parameter model on SN97 is now scoring 0.94 on HumanEval.
(xitter.cf/arbos_born/status/2050…)
➤ @affine_io SN120
Affine-III just dethroned Affine-II.
(xitter.cf/affine_io/status/20506…)
They also built Affine’s GPU cluster with H200s on Targon.
(xitter.cf/affine_io/status/20523…)
➤ @redteam SN61
Their subnet outputs now serve over 125 million DAU across their client base.
(xitter.cf/_redteam_/status/20509…)
➤ @Bitcast_network SN93
Bitcast is showing real growth on the revenue side.
(xitter.cf/Bitcast_network/status…)
➤ @hippius_subnet SN75
They hit a new milestone: 100 TB of egress served across the network.
(xitter.cf/hippius_subnet/status/…)
➤ @zeussubnet SN18
Zeus showed promising performance compared to ECMWF IFS and AIFS
(xitter.cf/zeussubnet/status/2052…)
➤ @NiomeAI SN55
Niome partnered with Scottish Enterprise to support the commercial deployment and global expansion of their synthetic bio data platform.
(xitter.cf/NiomeAI/status/2050578…)
➤ @resilabsai SN46
@RealFlyhomes is integrating RESI into their national lending network.
(xitter.cf/resilabsai/status/2052…)
➤ @Apex_SN1 SN1
Apex introduced RL Tron, a new reinforcement learning competition where agents battle in recurring head-to-head Tron-style tournaments.
(xitter.cf/Apex_SN1/status/205170…)
➤ @vidaio_ SN85
Vidaio is now listed on MEXC.
(xitter.cf/vidaio_/status/2051591…)
➤ @ReadyAI_ SN33
ReadyAI is rolling out x402 payments, a public revenue dashboard, and 75% alpha buybacks while opening their enrichment pipeline to customers, developers, and AI agents.
(xitter.cf/ReadyAI_/status/205279…)
➤ @ai_detection SN32
They just released their new landing page.
(xitter.cf/ai_detection/status/20…)
➤ @ridges_ai SN62
Ridges shared their 2 week roadmap.
(xitter.cf/ridges_ai/status/20524…)
➤ @adtao_ppcrebel SN21
AdTAO is now live on testnet.
(xitter.cf/adtao_ppcrebel/status/…)
➤ @minotaursubnet SN115
Minotaur’s codebase is now open source.
(xitter.cf/minotaursubnet/status/…)
// NEW SUBNETS
➤ @compelleai SN82
Compelle is a “platform where adversarial AI paves the way to AGI”.
(xitter.cf/compelleai/status/2052…)
// BITTENSOR ECOSYSTEM
➤ @solana x @taodotcom
$TAO is now live on Solana via Sunrise.
(xitter.cf/solana/status/20516783…)
➤ @tip_tao_
@nametensor created TIPTAO, a new Bittensor donation app.
(xitter.cf/nametensor/status/2052…)
➤ @YumaGroup
TaonSquare is a new platform where builders can explore all the AI tools powered by Bittensor.
(xitter.cf/YumaGroup/status/20527…)
➤ @yugevc
@sebyrubino launched Yuge VC, backing Resi and now Ditto.
(xitter.cf/yugevc/status/20516943…)
// PODCASTS & ARTICLES
➤ @opentensor Novelty Search with @metanova_labs
(xitter.cf/opentensor/status/2051…)
➤ @shardiban and @shibshib89 did a podcast for @oroagents
(xitter.cf/oroagents/status/20532…)
➤ @twistartups podcast with @jon_durbin from Chutes
(xitter.cf/twistartups/status/205…)
➤ TWIST podcast with @josercaldera from @yanez__ai
(xitter.cf/yanez__ai/status/20516…)
➤ @JesusMartinez with Yoav Cohen from @taodotcom.
(xitter.cf/JesusMartinez/status/2…)
➤ @sunrise podcast with @markjeffrey
(xitter.cf/markjeffrey/status/205…)
➤ @dsvfund Revenue Search with @QuantumSN48
(xitter.cf/QuantumSN48/status/205…)
➤ @VenturaLabs podcast with @BeyondNISQ from @qBitTensorLabs
(xitter.cf/VenturaLabs/status/205…)
➤ @jollygreenmoney podcast with @KibibyteMe from Ridges
(xitter.cf/jollygreenmoney/status…)
$TAO


Will SN62 Ridges on Bittensor $TAO challenge Claude & OpenClaw?
What does the future hold for this subnet?
We take a look under the hood to find out what is REALLY going on behind the scenes 👇
youtu.be/RuaKAhYH_P8

Paulie τ retweeted

Introducing Agent eXchange Layer (AXL) on Gensyn.
A peer-to-peer network node that provides encrypted, decentralised communication allowing agents, apps and ML pipelines to exchange data without a central server.
Read the docs: docs.gensyn.ai/tech/agent-ex…
Paulie τ retweeted

JUST IN: Shoe company Allbirds announces plans to invest up to $50M to “acquire high-performance GPU assets”
Paulie τ retweeted

BlockDAG continues to lower the $BDAG token price.
With the latest drop to an all-time low of $0.0000061, the token's FDV is now only $915,000.
Over $440M was claimed to be raised. The current FDV is 0.2% of that amount!
This is an astonishing loss of value in one of the biggest presales in crypto history, and not a single regulator cares.
This is exactly why crypto isn't mainstream.

BlockDAG is selling BDAG token at $0.000022 after listing at $0.05.
That implies a $3.3M FDV vs a reported $440M presale.
Less than 1%.
Presale investors face direct downside under this structure.
Full article in the comments.
#BlockDAG #BDAG #CryptoPresale #CryptoNews #TheHolyCoins
Paulie τ retweeted

We have recently made a huge breakthrough in the upcoming Quasar architecture.
We are going to open-source Quasar-Small-Preview, a 3B-parameter model with 1B active parameters, pretrained on 600B tokens with a 5M-token context ready for the coming run
Our expertise in MoE will allow us to create the largest and fastest MoE decentralized run, fully on the Quasar architecture, using distillation
This will enable us to have a state-of-the-art long-context model.
github.com/SILX-LABS/Quasar-…


Paulie τ retweeted
State of the art on SWE-Bench Pro is now open source.
@Zai_org's GLM-5.1. is Live on Chutes.
58.4 on SWE-Bench Pro. Ahead of Claude Opus 4.6 (57.3), GPT-5.4 (57.7), and Gemini 3.1 Pro (54.2). The first open weights model to lead that benchmark outright.
It also leads:
• CyberGym: 68.7 (best in class)
• BrowseComp: 68.0 (best in class)
• Terminal-Bench 2.0 with Claude Code: 66.5
• τ³-Bench: 70.6
• HLE with tools: 52.3
• NL2Repo: 42.7
754B params. MIT licensed. Built to hold its edge across hundreds of rounds and thousands of tool calls without plateauing.
Running inside a TEE on Chutes. The GPU operators serving the model can't see your prompts or outputs. Confidential compute at the hardware level, on a decentralized GPU network.
$0.95 in / $3.15 out per million tokens.
Try it now 🔗 chutes.ai/app/chute/b048fe26…

Paulie τ retweeted
BREAKING: Artemis II begins liftoff — the first human expedition to the Moon since 1972.

Paulie τ retweeted
Does your coding agent run on Claude Sonnet 4.6?
Costing you $3.00 per million input tokens and $15.00 per million output?
MiniMax M2.5 on Chutes costs just $0.19 input and $1.15 output all while running inside a secure and private TEE.
M2.5 scores 80.2% on SWE-Bench Verified while Sonnet 4.6 scores 79.6%.
You might be paying 15x more per input token and 13x more per output token for a model that scores lower on the benchmark most teams use to evaluate coding agents.
M2.5 also scores 51.3% on Multi-SWE-Bench (multi-repo tasks) and 76.3% on BrowseComp (agentic search). MiniMax trained it across 200,000+ real-world coding environments in 10+ languages.
The TEE variant on Chutes means your prompts and outputs stay inside a hardware-secured enclave. Claude's API has no equivalent option.
Just swap the model string and run your eval suite. Compare and see for yourself the power of open source models on Chutes.
🔗 chutes.ai/app/chute/ce6a92e4…

Paulie τ retweeted

This is Quasar Attention, the mechanism behind the upcoming Quasar models, designed to support context lengths of up to 5 million tokens.
Attention has long been a bottleneck for processing extended context. Standard attention mechanisms struggle to scale beyond ~200k tokens in training, creating a ceiling on how much information models can reliably use.
One approach to solving this has been linear attention methods, such as gated delta attention (used in Qwen 3.5) or Kimi delta attention. These improve efficiency and allow longer sequences, but introduce trade-offs: instability at extreme lengths, quality degradation, and in practice, they are not strictly linear.
Quasar Attention takes a different approach. It uses a continuous-time formulation, implemented as a fully matrix-based system rather than relying on vector-state approximations. In practice, this improves stability, reduces cost, and maintains performance as sequence length increases.
In internal stress tests at 50 million tokens, KDA-based approaches begin to lose stability, while Quasar Attention remains stable. This allows performance to hold as sequence length increases, rather than degrading beyond a fixed threshold.
On BABILong, a Quasar-based model pretrained on 20B tokens and fine-tuned on 16k sequences was evaluated on contexts ranging from 1 million to 10 million tokens, maintaining consistent performance across that range. By contrast, models using gated delta attention show significant degradation at longer lengths, in some cases dropping to ~10% performance at 10 million tokens. (Note: results are indicative; setups are not directly comparable)
On RULER benchmarks, a Quasar-10B model (built on Qwen 3.5 with frozen base weights and Quasar Attention added), pretrained on 200B tokens, achieved 87% at 1 million tokens, outperforming significantly larger baselines, including Qwen3 80B, under the same evaluation conditions.
Taken together, this points to a shift in where long-context performance is won or lost: not in model size alone, but in the attention mechanism itself.
Quasar Attention represents a step change in long-context modelling, setting a new standard for stability and performance at scale.
We thank @TargonCompute for the compute and for being our compute provider and long-term partner in training the upcoming Quasar models
Here is the link to our paper 👇
