
Founding Scientist @ Dexmate | exRS@FAIR | GaTech PhD
Joined September 2019
- Tweets61
- Following190
- Followers196
- Likes220




Memory is a critical component in making agent systems usable and reliable. But what should an embodied agent actually remember? Our new research found that embodied agents prefer images.
We built MeMoREval to test this: 53 memory-dependent tasks across 4 simulated environments.
We observe that:
1. Frames beat text descriptions on task success (70% vs 60%).
2. Frames are also cheaper, since they skip a model call at every step.
3. Text-only agents spend the most reasoning tokens per request, but the extra thinking can't recover details that were never stored.
Great work led by @wang_junxiang_ , Check out the project page:: memoreval.github.io/


A robot constantly receives multimodal information—textual states, camera images, 3D maps—but what is the “best” modality to save in memory? Is text enough?
Introducing MeMoREval, my internship project at @DexmateAI, where we evaluate memory modality for embodied agents.
🧵
I’ve updated my previous blog post on using general-purpose models to monitor robot task completion, adding tests of two decision models: OpenAI GPT-6 Luna and Perplexity Decider. Both models take text and images as input and make fast, cheap decisions, yet there’s still a gap to close before they can reliably judge whether a robot has finished its task. But I am sure models will get better and better.
Blog link: easypapersniper.github.io/un…

A robot needs to know when a step is done, or it never starts the next one.
In the video, the robot puts the mug upright at 36 s… and keeps going.
Checking "is it done?" sounds easy, but a useful checker has to:
• understand any task and scene, not just follow one hand-written rule
• run often enough to catch the moment, before the robot overshoots
• stay cheap enough to call again and again
So I put today's models to the test: GPT-6 Astra, Gemini, DeepSeek, Qwen, and Jev, a fast text-only decision model. I compared three ways to ask: a VLM judging the camera images directly, a VLM describing the scene and judging its own description, or the same description handed to Jev.
Here's what happened: easypapersniper.github.io/un…
Tianyu Li EasyPaperSniper retweeted

We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.

Interesting works. Enhancing the capacity of low cost robots will make robots more accessible to everyone

Excited to share that our work NeuralActuator: Neural Actuation Modeling for Robot Dynamics and External Force Perception has been accepted to #RSS2026!
Your robot — even a low-cost one — can feel external forces without torque or tactile sensors.
TL;DR: NeuralActuator is a neural actuator model that jointly predicts 1️⃣torque to capture the nonlinear and time-varying current–to–torque relationship of low-cost servos, 2️⃣external contact forces (and force detection gates) for sensorless force perception, 3️⃣and motor conditions that indicate each motor’s operating regime.
Here is a fast-forward video clip ⬇️ We are also covering more robots like LeRobot-S101 and Franka Panda.
More details coming soon.

Our perception stack today is a mosaic — MoGe for depth/normals, SAM3 for segmentation, Grounding DINO for open-vocab detection — each with its own preprocessing and failure modes. Long-horizon tasks compound this: every subpolicy wants a different input. Collapsing all of it into one model is a real shift in the engineering math. Cant wait to give it a try.

vision🍌 is here vision-banana.github.io/
if you got into computer vision the way I did, starting with pixel-level labeling tasks like segmentation, edges, depth, or surface normals, you’ll probably feel the same seeing these results -- something big has quietly shifted, and it’s going to change how we approach these problems for good 🧵
Coding agents are deployable today partly because we sandbox them: actions are validated and reversible before they touch production. Robots have no sandbox — the physical world has no undo. One core function of a world model is to be exactly that: a sandbox for the physical world.

1. I never said LLMs were not useful. They are, particularly with all the bells and whistles that are being added to them. I use them.
2. A robot-rich future can't be built with AIs that don't understand the physical world and don't anticipate the consequences of their actions. And LLMs really don't.
3. The future in the cartoon looks pretty dystopian TBH, but even a non-dystopian version will require world models and zero-shot planning abilities.
4. I rarely wear a suit and absolutely never wear a tie.
5. I would never ever place a coffee mug on top of a piece equipment.
6. I hope I'll look this young in 2032.
Here we announce the winners of our Build with Vega U Research Grant Program! Congratulations to the six proposals selected.
@tomssilver @GuanyaShi @QianqianWang5 @_krishna_murthy @daniel_t_seita Yuxiong Wang

We're thrilled to announce the recipients of the Dexmate Build with Vega U Research Grant Program.
Out of an incredible pool of proposals, six research teams have been selected to receive a Vega U dual-arm manipulation platform to advance their work in dexterous manipulation, Physical AI, and human-robot interaction.
We built this program because we believe the future of Physical AI and robot intelligence will be shaped by leading research. These teams are pushing the boundaries of what's possible, and we're honored to put our full-stack Physical AI platform in their hands.
Units ship in the coming weeks. We can't wait to see what they build. 🤖✨
#PhysicalAI #FullStackRobotics #DeveloperPlatform #Dexmate #Robotics #GeneralPurposeRobot #Vega #RoboticsResearch #Grant
We're officially launching the Dexmate Research Grant Program. Apply here: lnkd.in/g2rTqCvd
💌 A message from our CEO, Tao Chen.
In this video, he shares why we’re launching the Dexmate's Build with Vega U Research Grant Program and the future we’re building toward.
Our mission is simple: make intelligent robotics accessible to the people pushing research forward. 💡
We’re inviting institutions and labs working on the next wave of Physical AI to apply:
dexmate.ai/research-grant
We believe the future of robotics will be built through close collaboration with the research community and this is just the beginning.
If this resonates, share with a lab or researcher who should be part of this.
#Robotics #ArtificialIntelligence #AIResearch #PhysicalAI #HumanRobotInteraction #ResearchGrant #Dexmate #Vega
We believe the best way to move forward is to bring others along. That's why we're launching our first @DexmateAI Research Grant Program!
Selected research proposals will receive access to Vega U, our dual-arm manipulation platform, to explore and advance the frontiers of physical AI and embodied intelligence.
Who's eligible: Full-time faculty at accredited universities or degree-granting research institutions with a US mailing address.
📅 Deadline: April 5, 11:59 PM PST
🔗 Apply: dexmate.ai/research-grant
Not a PI? Pass this along to your lab lead — and tag anyone who should apply!
#Dexmate #VegaU #Robotics #PhysicalAI #EmbodiedAI #ResearchGrant
🤖 Robotics faculty and labs, we’re launching our first Dexmate Research Grant Program.
The future of AI will not live only in software. It will move, interact, and operate in the physical world.
At Dexmate, we’re building toward that future by supporting the researchers shaping it. This program is designed to accelerate breakthroughs in physical AI, embodied intelligence, and real world robotics applications.
Selected applicants will receive access to Vega U, our dual arm manipulation platform, to explore, build, and push the boundaries of what robots can do. 🧪
Applications are now open.
Apply here: dexmate.ai/research-grant
✨ Eligibility:
Full time faculty at accredited universities and degree granting research institutions with a US mailing address.
📅 Deadline
: April 5, 11:59 PM PST
Not a faculty PI? Share this with your PI or lab lead.
Tag someone who should apply. Let’s see what your lab builds next 🚀
#Dexmate #VegaU #robotics #PhysicalAI #EmbodiedAI #ResearchGrant #Innovation

Tianyu Li EasyPaperSniper retweeted

We present EgoReAct: Real-time 3D human reaction generation from streaming egocentric video.
🌟Reacting to streaming egocentric video is something humans do every day. We hope EgoReAct makes human motion more human-like.
🔎 What we found: existing ego-reaction data can be spatially inconsistent (e.g., moving reactions paired with fixed-camera videos), which breaks 3D grounding.
📷 What we built: HRD, a spatially aligned egocentric video–reaction dataset (3,500 pairs, 32 categories), plus a spatially aligned ViMo fix for fair evaluation. (Instead of collecting expensive ground-truth motion, we employ VDM to generate the egocentric videos.)
👁️⚡🏃 Our simple yet effective pipeline: motion tokenization for compact discrete codes + an autoregressive Transformer for online, strictly-causal generation. Metric depth and head dynamics further improve 3D spatial consistency.
Project Page: frank-zy-dou.github.io/proje…
ArXiv: arxiv.org/abs/2512.22808
#HumanMotion #EgocentricVision #3D #ARVR #Animation #AIGC #DeepLearning #GenerativeAI #Graphics #ComputerVision #Motion – at Cambridge, MA

Incredible Demo! Nice looking robot. Congrats @chichengcc @tonyzzhao !!

Today, we present a step-change in robotic AI @sundayrobotics.
Introducing ACT-1: A frontier robot foundation model trained on zero robot data.
- Ultra long-horizon tasks
- Zero-shot generalization
- Advanced dexterity
🧵->
Tianyu Li EasyPaperSniper retweeted

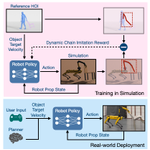
Imagine moving a heavy object with a joystick—through a swarm of quadruped-arm robots.
🕹️ decPLM: decentralized RL for multi-robot pinch-lift-move.
• No comms or rigid links
• Hierarchical RL + constellation reward
• 2→ N robots, sim→real
🔗 decplm.github.io/
Looking forward to checking how it works on my new benchmark task releasing soon.

How do you give a humanoid the general motion capability? Not just single motions, but all motion?
Introducing SONIC, our new work on supersizing motion tracking for natural humanoid control.
We argue that motion tracking is the scalable foundation task for humanoids. So we "supersized" it: 9k+ GPU hours and 100M+ motion frames.
But tracking alone is not enough; we show how to make a useful control system out of it:
- Universal Kinematic Planner: Enables game-like gamepad control and high-level teleoperation, just like controlling a character in a game.
- VR Full-Body Teleop: Direct, real-time whole-body control by a human wearing a VR headset.
- VR Keypoint Teleop: Control the upper body (hands/head) while our planner handles robust locomotion automatically.
- VLA Integration: We connect this motion tracker to autonomous Visual-Language-Action (VLA) models for autonomous task execution!
We use a Universal Token Space to UNIFY this command space, turning our robust tracker into a general-purpose, programmable humanoid brain.
This is the generalist "System 1" for humanoids. 🚀
Project: nvlabs.github.io/SONIC/
#Humanoids #Robotics #AI #FoundationModels #NVIDIAResearch 🧠🔥
The Nintendo Switch is more than just fun 🎮—it can also advance humanoid research! @sehoonha @jeonghwankim0 @wontaek0820 @donghoonbaek @seungeun071
With Switch4EAI, we turn Just Dance into a benchmark for humanoid whole-body motion tracking:
✅ ~$400 teleoperation setup
✅ Built-in scoring
✅ Constantly updated motions
✅ Direct human-vs-robot comparison
📄 arXiv: arxiv.org/abs/2508.13444
🌐 website: easypapersniper.github.io/pr…
🕺🤖 #Robotics #EmbodiedAI #AI #Humanoid #Benchmarking #NintendoSwitch
Here’s an example validation on Unitree G1 humanoid (averaged over 3 2-star level dances from Just Dance):
🤖 Robot avg. score: 5,707
🧑 Human avg. score: 9,361
Not the upper bound—future engineering can push robots much closer to matching human performance.
⭐️ Takeaway: Commercial game consoles aren’t just entertainment. They can be standardized, physically grounded benchmarks for Embodied AI.
A more thorough version of this work is coming soon—stay tuned!
#JustDance #Unitree #EmbodiedIntelligence #AIResearch