Overmind retweeted
I used to wonder why there has been rising interest in "open weight models" across the realms... 🌎
Then I realised the @OvermindLab eye sees all.
holy shit who is building this?
great segment on @theallinpod @DavidSacks @chamath @Jason
@OvermindLab is by far the easiest way to customise small models on your own proprietary data. direct from your coding agent, no in-house research lab required!
Overmind retweeted
Coinbase built this for their employees.
Overmind ships it for everyone.
Run /overmind finetune in:
• Claude Code
• Cursor
• Codex
Open source, and the model is yours.
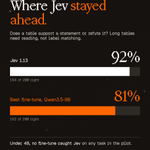
We were able to fine tune an open weight model (Qwen3.5-9B) on proprietary internal data at @coinbase, and it out performed frontier models, at much lower cost and speed, for a specialized task (fraud prevention in this case).
I think we'll see more of this pattern inside companies. The frontier models are amazing generalists. But increasingly you'll see specialist models out perform on more narrow tasks, either working on teams, or by themselves.
We're making it easy to fine tune models internally for our employees. We even have a skill for it in our internal harness that makes it easy to spin these up and start training them:
"/fine-tune-and-serve-llm I want to fine-tune Qwen for payments risk review. help me get started"
I imagine we'll have some backend services that could be replaced entirely by this new architecture.
Overmind retweeted
Overmind’s first week as the open-source training platform for agents.
Train the model behind your agent. Own the weights.
Onwards.
Overmind retweeted
Everyone’s building on the same models. Time to turn your team into a frontier lab:
▸ Star the repo: github.com/overmind-core/ove…
▸ Run the cloud version: console.overmindlab.ai
▸ Read more: overmindlab.ai/research/when…
Overmind retweeted
Software is no longer really a moat because it can be produced instantaneously....so what moats exist?
Data moats exist. If you can take your data moat and turn it into a self-improving product, that is a way for businesses to remain sustainable in the age of AI.
Overmind retweeted
agent builders are about to realize that production traces are gold.
the agents that log failures, evaluate properly, and turn real usage into training data will compound way faster than prompt only wrappers.
pretty interesting direction.
Introducing Overmind. The training platform for agents.
Overmind trained models across biomedical, legal, and engineering tasks beating the frontier and achieving:
• 7x better accuracy
• 20x cheaper usage
• 28x less hallucinations
Train your own: github.com/overmind-core/ove…
Overmind retweeted
Keep your tracing stack. Train from it.
Overmind now imports traces from @langfuse, @LangChain (LangSmith), @braintrust and Galileo. Connect a project and it backfills the history, then keeps syncing.
Those traces become eval sets and training data for a model you own.
Overmind retweeted
The Token Lords have given us such bounty! Honestly the pace of innovation at @OpenAI is astounding.
Overmind retweeted
What counts as a good run for @browser_use? Its own code already spells it out.
Overmind builds a context graph of an agent from its codebase and maps its tasks and trajectories. It then generates evaluators from the rules in that code.
Overmind retweeted
Fine-tuning a smaller open-weight model isn't a compromise.
For specialised tasks it can be the better way to build.
Overmind retweeted
Fine-tuned specialist vs frontier flagship:
• On contracts, it quoted clauses verbatim 7x as often, at a twentieth of the cost
• On BioRED, a fine-tuned Qwen 9B was right 4x as often
• On NASA ASRS, a 12B model tied on meaning and won on wording
Bigger wasn't better. Think Smaller.

ALT Scoreboard: Overmind specialist vs frontier flagship across legal, biomedical and aviation benchmarks. Right answers: 7x exact quote match (59.6% vs 8.5%), 4x accuracy (54.9% vs 14.1%), +10% wording match (0.295 vs 0.268). Made-up answers: 28x fewer fabricated quotes (0.12% vs 3.36%), 7x fewer invented relationships (6.6% vs 48.2%), 42% fewer invented details (19.4% vs 33.4%). Cost: 20x cheaper per 1,000 questions ($1.03 vs $20.94), 35% cheaper ($17.49 vs $26.73), 14 to 23% fewer words per synopsis.
Replying to @TylerEdwas
Across legal, biomedical and aviation benchmarks, our fine-tuned models were 7x more accurate at quoting clauses word for word and 20x cheaper on the legal task.
How we did it: overmindlab.ai/research/when…
Overmind retweeted
Your agent already produces the raw material for its next improvement.
Overmind turns production traces into datasets, scores candidate changes and opens reviewable PRs. A trained model can be benchmarked against the one you run today.
The workflow in 28 seconds.
Overmind retweeted
You can also build an agent you own for life @OvermindLab btw - own the model your product runs on trained off your own data.
Note: not an @NousResearch alternative but compatriot imho, addressing the same problem from different ends.
Hermes agent has emerged as the only option where you can build an agent you actually own for life
Between OpenAI stealing science medals and the terms of service on Muse by Meta it’s abundantly clear. Grok Bot is not yours either. OpenClaw has OpenAI.
Every business and person will want to own their AI Stack
It’s a core business asset
It’s the only way to drive unique outcomes vs the same setup as everyone else
I will continue saying it
If you’re looking for the extremes this is it. Own your future
Overmind retweeted
Nvidia is betting the model ecosystem goes the way operating systems did. The frontier labs may lead commercially but they are not the system of choice for scaled infrastructure.
Overmind retweeted
Replying to @tokensandai @awscloud
judges and speakers from some of the best teams in AI 🚀
@awscloud · @auth0 · @aerospikedb · @AirbyteHQ · @usebland · @kirodotdev · @OvermindLab · @truefoundry · @Macroscope · @TimescaleDB and @GoSenso
luma.com/deepagentshack
Overmind retweeted
this friday in SF we're putting $50K+ on the table.
join us at @awscloud for a full day of building agents that actually execute. research agents that go 10 layers deep. support systems that resolve issues end to end. pipelines that run themselves.
🏆 $50K+ inclusive of prizes, credits, and $6500+ cash
📅 march 27
🎟️ in-person | teams of 4 max | limited spots
registrations close thursday.
apply below 👇
Overmind retweeted
Fine tuned SLMs ftw @OvermindLab
Larry Ellison $ORCL highlighted something critical: models like ChatGPT, Gemini, Grok, and Llama are all trained on largely the same public internet data.
When everyone trains on the same information, models inevitably converge. That’s why AI is moving toward commoditization.
The real moat isn’t the model itself. It’s the proprietary data behind it.
Companies that can train on exclusive datasets gain an advantage competitors can’t replicate.
Having data that no one else has will allow you to dominate your market.