

We develop perception, control, & planning algorithms for robot autonomy | @CMU_Robotics | https://xitter.cf/t.co/gWjGiUaBeP | https://xitter.cf/t.co/9wO6amxfFc
Pittsburgh, PA
Joined June 2014
- Tweets535
- Following138
- Followers3.4K
- Likes457




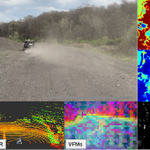
We don’t test with crash dummies. We test with Micah, at 10m/s, fully autonomous, off-road.
His body made it through every corner. His soul made it through most of them.
Check out our work on learned perception-conditioned dynamics models for high-speed off-road driving 👇

How your robot moves depends on what it’s driving over, especially when moving at >10m/s over loose gravel or ice 🚙💨
What if dynamics models could be conditioned on exactly the terrain they expect to drive over? Introducing SpatialBEV!
Accepted at #CoRL2026 🤠
0/7
AirLab retweeted

How your robot moves depends on what it’s driving over, especially when moving at >10m/s over loose gravel or ice 🚙💨
What if dynamics models could be conditioned on exactly the terrain they expect to drive over? Introducing SpatialBEV!
Accepted at #CoRL2026 🤠
0/7
AirLab retweeted

Failures are inevitable for robots that are deployed in the *big* world. We introduce ReSYNC, a system that leverages large-scale RL sim2real to recover from local failures and concept discovery to explain/avoid new failures. Check it out here: jaraxxus-me.github.io/ReSYNC…
AirLab retweeted

MAC-I² learns how much to trust vision and IMU.
Metrics-aware covariance for both modalities enables robust VI fusion. We apply it to initialization and calibration in challenging scenes and motions.
mac-i2.github.io/
1/9
AirLab retweeted

Where do foundational models actually meet the real world?
That's the question behind the 3rd AI Meets Autonomy workshop at IROS 2026!
📍 Pittsburgh | 🗓️ Thu, Oct 1 | 8:00–12:30 AM #IROS2026 🧵👇


AirLab retweeted

Excited to present our work "SuperMap: A Spatio-Temporal SLAM System for Visual-Language Navigation" at RSS 2026!
SuperMap is a living spatial memory for embodied AI — it perceives the world, remembers its evolution, and supports reasoning and action.
Perceive → Remember → Reason → Act
🌍 Project Page: superodometry.com/supermap
#RSS2026 #Robotics #SLAM #EmbodiedAI #SpatialAI #CMURobotics
AirLab retweeted

Working on robotics and attending ICML 2026? (and also overwhelmed by the number of sessions like me?)
I made a website to help me navigate my first ICML with an emphasis on robotics papers!
Link: parvkpr.github.io/robotics-a…
Sharing it here so people can use it. Check it out and let me know if you want me to add your paper/have any feedback!
Oh and also come checkout our poster on safety guardrails for navigation VLAs!
Link: constrained-robot-fms.github…
We’ll be presenting how constrained decoding can enforce safety requirments for robot navigation models at runtime, without retraining.
📍 Hall A #400
🗓️ Tue, July 7
⏰ 10:30–11:30 AM KST
#icml #robotics #physicalai – at Seoul, Republic of Korea

AirLab retweeted

What can different navigation domains (e.g. offroad, AV, humanoid, aerial, quadruped, digital) learn from each other?
🎉 Excited to announce the Workshop on “Bridging Perspectives in Navigation” @ IROS 2026 (Pittsburgh, 9/27/2026).
Submit your paper by August 21! 👇

Proud to see Co-Me accepted to CVPR 2026 🎉
Now supporting MapAnything 1.1, Depth Anything 3, and Pi3 - and 2× faster than the original, up to 21.5× speedup on long VGGT sequences. Congrats to the team!

AirLab retweeted
I’m excited to share that I successfully defended my Ph.D. thesis on Specification-Driven Planning for Safe Autonomy!
I’m deeply grateful to my committee Sebastian Scherer, Changliu Liu, Karen Leung and Eunsuk Kang for their time and guidance throughout this journey. More in 🧵

AirLab retweeted

Meet KinDER — a stress test for robot physical reasoning. All 13 methods failed 😈
🌎 25 environments
♾️ Infinite tasks
🏋️ Gymnasium API
⚒️ Over 20 parameterized skills
🪧 Human demonstrations
📊 13 baselines (planning and learning)
From @Princeton @CMU_Robotics @ICatGT @CambridgeMLG @nvidia @MIT_CSAIL
🧵 1/n
AirLab retweeted

I'm excited to share that RAVEN was accepted to ICRA 2026!
Paper: arxiv.org/abs/2509.23563
Website: raven-semantic.github.io
Collaboration with @OmarAlama, Dmytro Kurdydyk, John Keller, @Nik__V__ , Wenshan Wang, @ybisk , @smash0190
See you in Vienna!


AirLab retweeted

#IROS2026 will convene in Pittsburgh from Sept 27 – Oct 1!
As one of the largest & most dynamic robotics conferences, IROS brings together world-leading researchers, educators, govt. leaders, startups, industry innovators, practitioners, & investors👇
2026.ieee-iros.org/

AirLab retweeted

Fast & light 2D and 3D zero-shot open-vocabulary semantic segmentation is here 🚀🪶!!
Meet RADSeg:
- 6-30% mIoU improvement while being 3.95x faster and using 2.5x fewer parameters.
- Outperforms combinations of huge vision models (850-1350M) with just 105M !
💡The key is building on the agglomerative model, RADIO, and improving spatial consistency.

AirLab retweeted
We are honored to share that Super Odometry is now published in @ScienceRobotics and featured as a highlight article! 🚀 This work rethinks the SLAM paradigm: true resilience should not rely solely on external perception—it should begin from within.
science.org/stoken/author-to… #SLAM
AirLab retweeted

Human peripheral vision reduces detail in out-of-focus areas. This “annoying” feature saves massive computation while preserving spatial cues. And for the most human-like artifact we build—ROBOT—that efficiency matters.
Checkout our recent work:👉🔗 co-me-tokens.github.io
AirLab retweeted

🧵[3/n]
Co-Me distills a tiny confidence predictor that identifies low-confidence regions before most layers even run, letting us merge those tokens and cut redundant compute.
✨That’s it — simple and effective.
AirLab retweeted
🧵[2/n]
We noticed the model burns most of its compute on uncertain regions that are later discarded by downstream tasks. Can we avoid wasting this computation?
AirLab retweeted
More and more visual-geometric transformers are coming out, like VGGT and MapAnything—but pushing them to real robot is still challenging.
What if we could make them 10× faster?
👉🔗co-me-tokens.github.io
⚡Co-Me speeds up VGGT and MapAnything by up to 11.3x and 7.2x.
How? 👇🧵