


Pinned Tweet
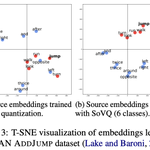
We show Transformers generalize on complex data by using shared attention patterns for similar structures
BUT how to avoid overfitting on low-complexity data?
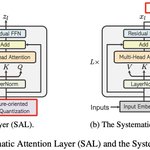
🚨SQ-Transformer explicitly quantizes embeddings structurally & learns systematic attention
arxiv.org/abs/2402.06492
🧵

Yichen Jiang retweeted

🚀 New Paper: RSQ: Learning from Important Tokens Leads to Better Quantized LLMs
We show that not all tokens should be treated equally during quantization. By prioritizing important tokens through a three-step process—Rotate, Scale, and Quantize—we achieve better-quantized models on LLaMA3, Mistral, and Qwen2.5.
🧵👇

Check out these other awesome works from my labmates & I will present my poster virtually on Aug22 --> "Inducing Systematicity in Transformers by Attending to Structurally Quantized Embeddings (arxiv.org/abs/2402.06492)"
Detailed thread: xitter.cf/YichenJiang9/status/17…
#ACL2024nlp


🚨 Check out an exciting batch of papers this week at #ACL2024!
Say hi to some of our awesome students & collaborators who are attending in person, and feel free to ask about our postdoc openings too 🙂
Topics:
-- multi-agent reasoning collaboration
-- structured systematicity/quantization in transformers
-- easy-to-hard generalization
-- very long-term conversational memory in LLMs
-- soft self-consistency
-- self-refining multimodal summarization
-- multimodal reasoning over image sequences
-- fine-grained hallucination evaluation and correction
-- summary-source alignments
#ACL2024nlp
👇👇

Yichen Jiang retweeted

🚨 New: my last PhD paper 🚨
Introducing System-1.x, a controllable planning framework with LLMs. It draws inspiration from Dual-Process Theory, which argues for the co-existence of fast/intuitive System-1 and slow/deliberate System-2 planning.
System 1.x generates hybrid plans & balances between the two planning modes (efficient + inaccurate System-1 & inefficient + more accurate System-2) based on the difficulty of the decomposed (sub-)problem at hand.
Some exciting results+features of System-1.x:
-- performance: beats System-1, System-2 & a symbolic planner (A*) both ID and OOD (up to 39%), given an exploration budget.
-- training-time control/balance: user can train a System-1.25/1.5/1.75 to balance accuracy + efficiency.
-- test-time control/balance: user can bias the planner to solve more/less sub-goals using System-2.
-- flexibility to integrate symbolic solvers: allows building neuro-symbolic System-1.x with a symbolic System-2 (A*).
-- generalizability: can learn from different search algos (DFS/BFS/A*).
🧵👇

Yichen Jiang retweeted

Having a great time at #LxMLS in Lisbon + meeting awesome people & exploring the beautiful city 🙂 (highly recommended ML school*) ➡️➡️➡️
Next stop: #ICML2024 in Vienna for MoE tutorial/panel + papers on MAGDi, ReGAL, etc. 👇 (ping me if you want to meet up / chat about faculty+postdoc+phd positions, etc.)!
(*thanks to @andre_t_martins @mariotelfig @RamonAstudill12 @bgmartins + whole team for the thoughtful organization!)


Yichen Jiang retweeted
We are going to present MAGDi at #ICML2024. If you are attending, say hi to @EliasEskin and @mohitban47 to know more about this work and PhD/postdoc positions @uncnlp!
🧵👇
Having a great time at #LxMLS in Lisbon + meeting awesome people & exploring the beautiful city 🙂 (highly recommended ML school*) ➡️➡️➡️
Next stop: #ICML2024 in Vienna for MoE tutorial/panel + papers on MAGDi, ReGAL, etc. 👇 (ping me if you want to meet up / chat about faculty+postdoc+phd positions, etc.)!
(*thanks to @andre_t_martins @mariotelfig @RamonAstudill12 @bgmartins + whole team for the thoughtful organization!)
Yichen Jiang retweeted

Check out 2 useful updates on CREMA! 🚨
(1a) A new modality-sequential modular training for generalizable and efficient reasoning on video+language+any other modalities by eliminating modality interference.
(1b) A novel modality-adaptive early exit strategy allows the model to bypass the training of specific sensory inputs if this modality information is converged.
(2) More unique/rare multimodal reasoning tasks (video-touch/thermal QA) to further demonstrate the generalizability of CREMA.
See more details in Arxiv v2 👉 arxiv.org/abs/2402.05889v2
(original thread below👇)


How to efficiently & flexibly inject diverse new modalities (RGB+audio/3D/depth/flow/...) to improve Video Reasoning?
Introducing ☕️ CREMA, a substantially efficient (~3% trainable params) & modular fusion framework (w/o complex architecture changes)
arxiv.org/abs/2402.05889
🧵

Welcome to UNC NLP! I’m sure you will have a lot of fun doing interesting projects and living in a warmer place full of great college sports matches 😀 Best of luck!

🥳Some of the first papers I read at the start of my ML journey were @mohitban47's papers on multimodal language understanding, and after a great couple of years at Northeastern working on vision-language, I'm excited to joining his lab at @uncnlp as a PhD student to work on program synthesis + multimodal agents! 😁 (1/3) 🧵

Check out this work by my labmates on how to make LLMs not overly confident on bad answers. Spoiler 🚨: they made the model less confident on wrong data and more confident on correct ones.


Yichen Jiang retweeted

🚨New paper👉RACCooN: remove/add/change video content effortlessly/interactively via our MLLM+Video Diffusion (V2P2V) framework with auto-generated descriptions!
▶️ 1. Video-to-Paragraph (V2P): RACCooN first generates well-structured/detailed descriptions of videos with MLLM leveraging a multi-granular pooling strategy
▶️ 2. Paragraph-to-Video (P2V): Users can then enjoy diverse video editing skills by refining auto-narratives for the video diffusion model
🧵

Yichen Jiang retweeted
🚨 Introducing VideoTree! Captioning + LLMs can perform well on long-video QA, but dense frame captioning leads to inefficiency (redundancy) and sub-optimality (irrelevance).
VideoTree addresses these issues & improves LLM-based long-video QA by:
▶️ Structured Video Representation: iteratively organizing the video’s frames into a hierarchical tree representation via visual frame clustering & cluster scoring.
▶️ Adaptive Keyframe Selection and Coarse-to-Fine Sampling: dynamically selecting query-related frame clusters for captioning. Its tree structure encodes varying granularity levels, allowing VideoTree to allocate more frames (zoom-in) in relevant clusters and fewer in irrelevant ones.
Those lead to major gains on popular benchmarks, including SOTA on NExT-QA & IntentQA, and 7.0% gains on EgoSchema, while cutting ~40% inference time.
arxiv.org/abs/2405.19209
🧵

🎉Excited to announce that SQ-Transformer is accepted to #ACL2024nlp!
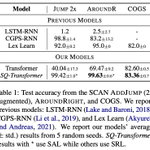
We induce systematicity & achieve stronger generalization in Transformers (w/o pretraining on complex data) by structurally quantizing word embedding & regularizing attention outputs.
@XiangZhou14 @mohitban47

We show Transformers generalize on complex data by using shared attention patterns for similar structures
BUT how to avoid overfitting on low-complexity data?
🚨SQ-Transformer explicitly quantizes embeddings structurally & learns systematic attention
arxiv.org/abs/2402.06492
🧵
Yichen Jiang retweeted
Agentic workflows with LLMs are now getting popular for solving complex tasks!
In one of the early works on this topic -- ReConcile, at #ACL2024nlp 🎉 -- we study collaborative model-model interactions w/ confidence-estimation & corrective convincingness btwn diverse LLMs.
🧵👇

🚨ReConcile: Round-Table Conference Improves Reasoning via Consensus among Diverse LLMs
ChatGPT+Bard+Claude2 discuss & correctively convince each other for reasoning, even outperforming GPT4 (& GPT4 as agent improves by 10%)!
arxiv.org/abs/2309.13007
@cyjustinchen @mohitban47
🧵

Also, after 10 unforgettable years at Chapel Hill, 2 of those generously sponsored by @Apple Scholars in AIML PhD Fellowship, "I'm going to take my talents to Seattle and join Apple AIML". I will continue to do research in efficient and safe AI that generalizes compositionally.
Last weekend, I graduated from @unccs, 10 years after I wrote my first line of code in COMP 116. I'm super grateful to my advisor @mohitban47, labmates, intern mentors, and many others. Y'all can see how excited I was as I threw my cap out of the frame to the 2nd floor.
Last weekend, I graduated from @unccs, 10 years after I wrote my first line of code in COMP 116. I'm super grateful to my advisor @mohitban47, labmates, intern mentors, and many others. Y'all can see how excited I was as I threw my cap out of the frame to the 2nd floor.
🎉🎓 Congratulations to these awesome new+old MURGeLab graduates on their hooding ceremony --> PhDs @peterbhase @yichenjiang9 @adyasha10 @swarnanlp (+ last year's @byryuer and @xiangzhou14, who joined us for this year's commencement) & MS @abhayzala7 🥳
Was a fun celebration with families+friends & many photo sessions in perfect weather + blue carolina skies 😀


Yichen Jiang retweeted
🚨 Check out an exciting set of #ICLR2024 papers/spotlights✨ this week at @iclr_conf (+workshop on reliable+responsible AI)!
Say hi to our awesome students/postdocs (some were/will be on job market) & collaborators, and feel free to ask abt our postdoc openings too** 🙂
🧵👇

Yichen Jiang retweeted

🎉 Excited that ReGAL has been accepted to @icmlconf #ICML2024! We use LLM-guided refactoring to discover reusable abstractions, which help coding agents avoid repetition+improve reuse!
Find me in Vienna (this week & in July)😀
Thanks to my co-authors @ArchikiPrasad @mohitban47
🚨Is writing repetitive code leading your LLM to make mistakes?
👑ReGAL: Refactoring for Generalizable Abstraction Learning, a new method for learning reusable functions!
Paper: arxiv.org/abs/2401.16467
Code: github.com/esteng/regal_prog…
w/ @ArchikiPrasad @mohitban47 @uncnlp
🧵👇

Yichen Jiang retweeted

Can we design an efficient & versatile framework to reuse+adapt existing pretrained ControlNets to accurately guide any video/image diffusion model and support diverse controls?
🚨 Introducing Ctrl-Adapter:
➡️ Flexible Compatibility: Adapts any pretrained ControlNet (scribble/sketch, depth, canny edge, human pose, etc.) to any image or video diffusion model (Stable Video Diffusion, I2VGen-XL, Hotshot-XL, SDXL, etc.)
➡️ Diverse Capabilities: Supports image control, video control, sparse video control, multi-condition control, zeroshot adaptation to unseen control conditions, and video editing
➡️ Efficient Training: Outperforms both image/video baselines in < 10 GPU hours
arxiv.org/abs/2404.09967
@jmin__cho @AbhayZala7 @mohitban47 @uncnlp @unccs
🧵
Yichen Jiang retweeted

Can we adaptively generate training environments with LLMs to help small embodied RL game agents learn useful skills that they are weak at? 🤔
👉 Check out EnvGen, an effective+efficient framework in which an LLM progressively generates and adapts training environments based on feedback from the RL agent's intermediate successes/failures.
➡️ A lightweight (4M params) RL agent trained w/ EnvGen outperforms a GPT-4 agent in Crafter environment
➡️ Uses only 4 LLM calls for the entire training/inference (vs. thousands of calls per episode in LLM agents)
➡️ Significant performance gain & speed up in the learning of long-horizon tasks
arxiv.org/abs/2403.12014
🧵

Yichen Jiang retweeted

Can we teach multiple skills to a text-to-image (T2I) model (w/o expensive annotations), while minimizing knowledge conflicts between skills? 🤔
👉SELMA improves T2I models by fine-tuning on automatically generated multi-skill image-text datasets, with skill-specific LoRA expert learning & merging.
-- On SD models, SELMA boosts 5 metrics (TIFA/DSG/PickScore/ImageReward/HPS) + human eval.
-- Finetuning on auto-generated data matches the performance of finetuning on GT data.
-- Weak-to-strong generalization (SDv2 images can help SDXL finetuning).
arxiv.org/abs/2403.06952
🧵

Yichen Jiang retweeted

Can LLMs keep track of very long conversations?
We evaluate 'conversational memory' of LLMs via 3 tasks on our dataset of multi-session multimodal dialogs --> LLMs struggle to remember, reason over history, draw long-range temporal/causal connections
arxiv.org/abs/2402.17753
🧵
