

Student Researcher @GoogleDeepMind PhD-ing @WisconsinCS | MS at @uwcse/@RAIVNLab | Ex @AIatMeta @nvidiaai and @samsungresearch. He/Him
Madison, WI
Joined June 2009
- Tweets1.2K
- Following469
- Followers1.1K
- Likes8.3K





Q for all RL post training experts from a noob - what are some good detailed resources about building data mixtures to improve "small"-ish models (<70B) on specific goals/skills e.g. multi-hop retrieval?
Tulu 3 (@natolambert et al) has been the best I've found so far!
Folks at #acl2026 interested in long-horizon agentic reasoning, this is happening now in Grand Hall!!

Aniket Rege retweeted

Excited to be at #ACL2026. Delighted to present keynote talk tomorrow on learning personalized preferences at
📍 Workshop on Customizable NLP @customnlp4u
🗓️ Friday, July 3rd | ⏰ 9:10–9:50 am PT
📌Old Town

Aniket Rege retweeted

🚨New Paper🚨
Learning to Plan and Orchestrate for Open-Ended Image Editing
Image editors handle concrete tasks, but struggle with abstract ones (e.g., adapt this ad for winter), which require coordinated edits.
We tackle this via planning and experiential tool learning.
🧵👇


🚨 Very happy to have advised this #icml2026 work led by @MaheshRam23629 exploring RL for cooperative reasoning in LLMs
tl;dr post training LLMs to play the card game Hanabi 🎆 improves performance on unseen tasks like instruction following and temporal reasoning!


Hanging around @Stanford / Palo Alto for the rest of the day, any mutuals who are free for a coffee or chat pls DM! 🤓
Hi #ml twitter!
I’m in San Francisco from 5/6-5/12, I’d love to catch up over a coffee and chat about research and things y’all are working on!!
(post @NeurIPSConf submission hangover 🤓)
Aniket Rege retweeted

We all knew LLM agents struggle to explore, but we had to eyeball it 👀. We couldn't measure exploration errors. Until now. 🗺️🤖
We built a policy-agnostic metric to quantify exploration and exploitation errors in LLM agents.
Spoiler: Exploration error is what kills📉 agent performance in our setting 👇🧵(1/8)

Aniket Rege retweeted

Excited to see Qwen-3.5-Omni evaluated on AV-SpeakerBench 🚀
From ~54 → ~71.5: open models are catching up in audiovisual reasoning.
Gemini still leads, but the gap is shrinking.
Special thanks to my mentor, @yu_zhuoran32720 , and my advisor, @yong_jae_lee , from the Wisconsin AI Vision Lab, for making AV-SpeakerBench possible.
Two questions:
- "Is Qwen-3.5-Omni really open-source?"
- "Why no strong AV models yet from @OpenAI @AnthropicAI ?"
AV reasoning is the next frontier.
🔗 Benchmark Project Page: plnguyen2908.github.io/AV-Sp…
🔗 Qwen blog: qwen.ai/blog?id=qwen3.5-omni…


🚀 Qwen3.5-Omni is here! Scaling up to a native omni-modal AGI.
Meet the next generation of Qwen, designed for native text, image, audio, and video understanding, with major advances in both intelligence and real-time interaction.
A standout feature: 'Audio-Visual Vibe Coding'. Describe your vision to the camera, and Qwen3.5-Omni-Plus instantly builds a functional website or game for you.
Offline Highlights:
🎬 Script-Level Captioning: Generate detailed video scripts with timestamps, scene cuts & speaker mapping.
🏆 SOTA Performance: Outperform Gemini-3.1 Pro in audio and matches its audio-visual understanding.
🧠 Massive Capacity: Natively handle up to 10h of audio or 400s of 720p video, trained on 100M+ hours of data.
🌍 Global Reach: Recognize 113 languages (speech) & speaks 36.
Real-time Features:
🎙️ Fine-Grained Voice Control: Adjust emotion, pace, and volume in real-time.
🔍 Built-in Web Search & complex function calling.
👤 Voice Cloning: Customize your AI's voice from a short sample, with engineering rollout coming soon.
💬 Human-like Conversation: Smart turn-taking that understands real intent and ignores noise.
The Qwen3.5-Omni family includes Plus, Flash, and Light variants.
Try it out:
Blog: qwen.ai/blog?id=qwen3.5-omni
Realtime Interaction: click the VoiceChat/VideoChat button (bottom-right): chat.qwen.ai
HF-Demo: huggingface.co/spaces/Qwen/Q…
HF-VoiceOnline-Demo: huggingface.co/spaces/Qwen/Q…
API-Offline: alibabacloud.com/help/en/mod…
API-Realtime: alibabacloud.com/help/en/mod…

🚨 I'm super stoked to share that I'll be spending this summer as a student researcher at the GenAI team of @GoogleDeepMind with @_gaganm , working on long horizon tool use!!
A HUGE shoutout to my network for your overwhelming response to my internship search post :')
I had SO many wonderful conversations and I'm so thankful for all your generosity and kindness!
xitter.cf/wregss/status/20336367…

Hi ML Twitter!
My Summer 2026 internship unfortunately fell through last minute 😵💫
If your team is looking for interns, I’d love to connect - RTs appreciated 🙏
My website: aniketrege.github.io/
Aniket Rege retweeted

📢 Reminder: The submission deadline for the Machine Translation for Vision (MTV) Challenge at MAPS @CVPR2026 has been extended to April 17th!

🚨New work with @Meta @RealityLabs
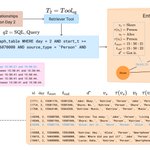
We introduce EGAgent, an agentic reasoning framework for very long video understanding powered by entity scene graphs
Why? With long multimodal data streams, agents must search and reason across multiple modalities!
🧵 (1/n)
Aniket Rege retweeted

If you’re working on benchmarks for cultural authenticity or methodology for AI pluralism, we want to see your work at the MAPS Workshop @CVPR 2026.
We are also hosting the Machine Translation for Vision (MTV) challenge, don't miss out! 🏆
Check out the full CFP below. 👇

📢 Submissions are now OPEN for our @CVPR Workshop: Multimodal Alignment for a Pluralistic Society (MAPS)!
Help us build AI that reflects global diversity, culture, and human values. 🌍🌏🌎
📅 Mar 3 – Apr 10, 2026
📝 Short papers (4 pgs)
🔗 openreview.net/group?id=thec…
#CVPR2026

Hi computer vision fam!
Interested in generative models that suit a diverse plurality of human values and cultures?
Please submit to the @maps_cvpr workshop at #CVPR2026 led by the amazing @PShravannayak which I'm helping co-organize!
Looking forward to your exciting works!!
📢 Submissions are now OPEN for our @CVPR Workshop: Multimodal Alignment for a Pluralistic Society (MAPS)!
Help us build AI that reflects global diversity, culture, and human values. 🌍🌏🌎
📅 Mar 3 – Apr 10, 2026
📝 Short papers (4 pgs)
🔗 openreview.net/group?id=thec…
#CVPR2026
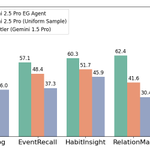
Huge gains in Long-Horizon Relational Reasoning!
On tasks that require modeling relationships between entities across long time horizons, EGAgent excels compared to previous SoTA (EgoButler) and Gemini 2.5 Pro
🔺 + 20.8 % on RelationMap
🔺 + 22.2 % on TaskMaster
🧵(6/n)

📹 Not just EgoCentric Videos!
On Video-MME (Long), we match strong 7B baseline AdaVideoRAG (Xue et al., NeurIPS ‘25) using Qwen-2.5 VL while processing over 10x fewer frames.
Our framework is straightforward to adapt to any long horizon multimodal dataset!
🧵(7/n)
Joint work with amazing collaborators @AIatMeta @RealityLabs @UWMadison
@ArkaSadhu29 @oi02lyl @kejie_li @ramyavinayak @yuning_chai @yong_jae_lee @kim_hyojin_
Project Page: facebookresearch.github.io/e…
Code: github.com/facebookresearch/…
ArXiv: arxiv.org/abs/2601.18157
🧵(8/n)