
Researcher
California
Joined March 2020
- Tweets102
- Following290
- Followers1.1K
- Likes140




Pinned Tweet
🚀 New paper: Mamba–Transformer hybrid VLMs can go fast without forgetting.
We introduce stateful token reduction for long-video VLMs.
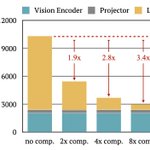
✅ Only 25% of visual tokens
🚀 3.8–4.2× faster prefilling (TTFT)
🎯 Near-baseline accuracy (can exceed baseline with light finetuning)

Wonmin Byeon retweeted

🚀 Are you a PhD student pushing the boundaries of AI, robotics, graphics, or accelerated computing?
NVIDIA's Graduate Fellowship offers up to $60K in funding, mentorship from NVIDIA researchers, and a summer research internship!
⏳ Apply by October 30!
blogs.nvidia.com/blog/applic…

Wonmin Byeon retweeted

SpatialClaw accepted to #NeurIPS2026 🎉
Even GPT-6 Astra gets better with the right action interface.
Same training-free harness, no model-specific tuning, 20 spatial benchmarks:
GPT-6 Astra: 71.3 → 77.4 (+6.1)
Opus 5: 58.5 → 73.5 (+15.0)
GPT-6 Sol: 61.2 → 72.9 (+11.7)
Qwen3.8-27B: 59.8 → 67.3 (+7.5)
Astra already looks “spatial.” A persistent Python kernel on top of it still wins.
Code is the action interface: the VLM writes one cell per step, inspects SAM / depth / geometry outputs, revises, then answers.
📄 Paper: arxiv.org/abs/2606.13673
💻 Code: github.com/NVlabs/SpatialCla…
🌐 Website: spatialclaw.github.io/
@NVIDIAAI

I'm at #ICML2026! Reach out if you’d like to discuss hybrid models, efficient LLMs/VLMs, memory models, or related topics.
Wonmin Byeon retweeted

📄 New NVIDIA paper Alert! 🎉
Agent Explorative Policy Optimization for Multimodal Agentic Reasoning
Amazing team:
Minki Kang (Intern)
Shizhe Diao
Ryo Hachiuma
Sung Ju Hwang
Pavlo Molchanov
Yu-Chiang Frank Wang
Paper: huggingface.co/papers/2605.2…
Project: byungkwanlee.github.io/AXPO-…

Wonmin Byeon retweeted

We are releasing Star Elastic - turn ONE reasoning LLM into MANY sizes with a single post-training run.
360× cheaper than pretraining a family of models.
7× better than SOTA compression.
Split reasoning capability.
Plus elastic budget control that beats the accuracy-latency frontier.
Paper: arxiv.org/abs/2605.07182
HF models: huggingface.co/collections/n…
Thread 👇
Wonmin Byeon retweeted

Introducing NVIDIA Nemotron 3 Super 🎉
Open 120B-parameter (12B active) hybrid Mamba-Transformer MoE model
Native 1M-token context
Built for compute-efficient, high-accuracy multi-agent applications
Plus, fully open weights, datasets and recipes for easy customization and deployment. 🧵
Wonmin Byeon retweeted

Announcing NVIDIA Nemotron 3 Super!
💚120B-12A Hybrid SSM Latent MoE, designed for Blackwell
💚36 on AAIndex v4
💚up to 2.2X faster than GPT-OSS-120B in FP4
💚Open data, open recipe, open weights
Models, Tech report, etc. here:
research.nvidia.com/labs/nem…
And yes, Ultra is coming!

Wonmin Byeon retweeted
One of the things that makes Nemotron 3 Super so fast is native multi-token prediction.
1. Model predicts several tokens rather than just one, which is essentially free because it's just a bit of extra work for the last layer of the model. The first token is accepted, the others are provisional.
2. On the next pass, the model verifies the extra tokens and either accepts them if they were correct or rejects them if they were wrong. If they were wrong, we still accept one token, so autoregression proceeds even with misprediction.
3. Verification is essentially free because the GPU has a lot of extra compute capability when running at a small batch size that would otherwise be wasted.
4. Speedup then is directly linked to acceptance rates. If the multi-token prediction is more accurate, we get a bigger speedup.

4) Key piece: language-aware token scoring across attention and SSM:
- attention layers (explicit attention)
- Mamba/SSM layers (implicit-attention proxy)
So selection stays prompt-aligned.
It’s been months since we introduced STORM, and it’s great to see so many video discussions! ⛈️🎥
To catch up on our token-efficient long video understanding work, check out these reviews (Some are AI-generated but very useful!).
Huge thanks to the creators! 🙌
The links ↓


AI Coffee Break with Letitia: youtu.be/uMk3VN4S8TQ?si=Q0n8…
Arxiv Papers: youtu.be/I_loecu6Gew?si=tB5h…
AI Papers Podcast: youtu.be/ifqHBtpw7CM?si=Unq0…
AI Paper Slop: youtu.be/pKObqY3msJk?si=L7jq…
Our project page and the full paper are here: research.nvidia.com/labs/lpr…
Wonmin Byeon retweeted

What if your model could learn from its own drafts during RL training? 🚀
🔥 New paper: iGRPO: Iterative Group Relative Policy Optimization
We add a self-feedback loop to GRPO: the model drafts multiple solutions, picks its best one, then learns to refine beyond it.
Core idea:
Stage 1 → explore and select your strongest attempt. Stage 2 → condition on that attempt and beat it.
Same scalar reward. No critics, no generated critiques, no verification text. The best draft is the only feedback the model needs.
📊 Results across 7B / 8B / 14B models:
• Nemotron-H-8B-Base-8K: 41.1% → 45.0% (+3.96 over GRPO)
• DeepSeek-R1-Distill-Qwen-7B: 68.3% → 69.9%
• OpenMath-Nemotron-14B: 76.7% → 78.0%
• OpenReasoning-Nemotron-7B on AceReason-Math: 85.62% AIME24 / 79.64% AIME25 🏆
The same two-stage wrapper also improves DAPO and GSPO. It's not tied to GRPO at all.
📄 Paper: arxiv.org/abs/2602.09000
This work was the result of a wonderful collaboration with @shrimai_ @igtmn @GXiming @SeungjuHan3 @_weiping @YejinChoinka @jankautz

Wonmin Byeon retweeted
🚀Announcing C-RADIOv4: The latest evolution in our agglomerative vision backbone family is here!
We’ve built a unified student model that distills the best capabilities of multiple state-of-the-art teachers into a single, efficient architecture.
DINOv3, SAM3 and SigLIP2 all in one forward pass with better features. Better efficiency, robustness and any resolution.
👐Permissive and open-source!
Read the tech report: arxiv.org/pdf/2601.17237
Models:
huggingface.co/nvidia/C-RADI…
huggingface.co/nvidia/C-RADI…
Github: github.com/NVlabs/RADIO
🧵1/N


