

Uncertainty in the face of optimism
Joined July 2011
- Tweets194
- Following91
- Followers334
- Likes41
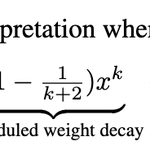


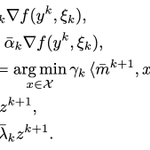


Thomas Pethick retweeted
Yes, I think there is something interesting to be said here: take a look at @leloykun's blogpost leloykun.github.io/ponder/mu… "So, in a sense, you can interpret Muon with the old coefficients as doing steepest descent under the Schatten-32 norm"

Thomas Pethick retweeted

Result #32: @mihai673 has achieved a 30-step improvement over the old 2026/05/09 record by adding a SODA (Pethick et al. 2026)-style anchor towards init.
It is unknown whether this technique can also improve the current record.
2/5


Thomas Pethick retweeted

SODA-AMUSE+Gram+PMuon is the recipe that wins consistently on 4/4 codex GPU instances.
PMuon is a new idea: github.com/zzp1012/modded-na…
AMUSE is Muon + ScheduleFree: arxiv.org/abs/2605.22432v1
SODA is a wrapper that's more popular: arxiv.org/abs/2605.11172
Gram is a lesser known Gram-Newton-Schultz optimization: github.com/Dao-AILab/gram-ne…
Thomas Pethick retweeted

Our @TmlrOrg paper addresses intra/inter-client distribution shifts in federated learning focusing on overall generalization & shows importance-weighted ERM achieves smaller generali. error than ERM.
openreview.net/pdf?id=N7lCDa…
w/@Fanghui_SgrA @tmpethick @Grigoris_c @CevherLIONS

Thomas Pethick retweeted

Thrilled to present my work “Finding actual descent directions for Adversarial Training” at the International Conference on Learning Representations #ICLR2023 in Rwanda 🇷🇼 #AI openreview.net/forum?id=I3HC… Joint work with Igor Krawczuk, Leello Dadi, @tmpethick and @CevherLIONS (1/3) 🧵