

MTS @MicrosoftAI working on frontier VLM training and multimodal reinforcement learning. ML Theory PhD @GeorgiaTech, Math BS @USC.
Atlanta, GA
Joined December 2019
- Tweets932
- Following724
- Followers950
- Likes3.3K






Exciting 3T native multimodal pretraining happening at @MicrosoftAI! Post-training 🔜

We now have state-of-the-art pre-trained base models in the 3T-parameter weight class, built entirely in-house at MAI.
Post-training results coming soon -- stay tuned!
Lots of details in our technical blog post.
microsoft.ai/news/frontier-p…

This work has been accepted to NeurIPS 2026 - see you in Atlanta!

New paper — the last and best from my PhD!
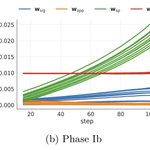
We show the first end-to-end feature learning analysis of how neural networks overfit to spurious correlations. Our theory implies phase transitions in SGD learning dynamics that match empirical results.
Paper: arxiv.org/abs/2606.30444

I somehow missed this when you posted, but very nice and thoughtful writeup echoing my own decision to "leave" theory. It's also interesting to think about the role of the new-age theoretician as more interpretive/expositional as AI proofs need to be communicated and organized.
I've transitioned to Member of Technical Staff @MicrosoftAI focused on frontier VLM training and multimodal reinforcement learning. Looking forward to an exciting new chapter!

I still wonder whether they'll make a comeback. I think they'd make much better skill docs than the typical SKILL.md which just has text. Combining instructions, code with verified outputs, and charts/plots... seems pretty powerful and I haven't seen anyone thinking about it
Thanks! (And that's a nice paper!) Yes, I think there is promise in SDE and mean field-type approaches for spurious feature learning. Of note, our Phase II spurious evolution is closely related to the classical ODE dot(x) = x * e^-(x^2).
Good question: this is the online setting (fresh data at every step), so no such thing as full-batch GD. This is to avoid data reuse, mostly for mathematical convenience.
With that said, the code wouldn't be too hard to extend to full-batch GD: github.com/tmlabonte/xor

Our theory requires the % of minority group data (i.e. data with the spurious feature) to go to zero, to guarantee total dependence on the spurious feature.
OTOH, if the % is constant, our experiments show the true signal (blue) can eventually surpass the spurious signal (green)

Overall we believe this is a step towards a rigorous foundation for popular robustness algorithms like Just Train Twice and Deep Feature Reweighting, and could even inform new robust interventions.
This paper was the result of a wonderful collaboration with @v__muthukumar!
Even more interesting, if the spurious correlation is sufficiently weak, we show empirically that the XOR signal can eventually be learned. (Though the spurious feature is not forgotten!)

Compared to learning the XOR in isolation, the spurious correlation introduces shockingly nonlinear interdependencies which complicate learning dynamics.
As a consequence, the spurious feature isn’t just learned earlier, but exponentially slows signal feature learning.
Deep learning theory is hard, and most papers have to simplify the model or algorithm — think NTK or layer-wise SGD. Instead, we simplify the data!
Our setting, a quadratic XOR signal with linear shortcut, is one of the simplest where spurious feature learning can be observed.
New paper — the last and best from my PhD!
We show the first end-to-end feature learning analysis of how neural networks overfit to spurious correlations. Our theory implies phase transitions in SGD learning dynamics that match empirical results.
Paper: arxiv.org/abs/2606.30444
Very cool work from new colleagues at @ms_aifrontiers: most LLM benchmarks are redundant!
