



Thomas Schmied retweeted

I am so happy the world is increasingly ready to treat AI seriously.
Permanent, employee-level access for independent evaluators should be required by law. We will join Anthropic in offering access to @METR before it’s required.
We should not only slow capabilities progress but also accelerate alignment research. The right incentives could redirect labs' capabilities research programmes to alignment. Voluntary efforts are fragile.
As the stakes continue to rise, it will be appropriate to treat non-compliance or non-disclosure of incidents with the same severity as violations of nuclear safety laws.
This must be global. You don’t need trust for a mutually beneficial, verifiable treaty. No country wants humanity to lose control over superintelligence. Let’s extend the hand to China.
We need frontier AI researchers to make progress on alignment, _now_. If you are one, ask yourself how you can help. Your impact could be monumental.
AI has great upside, but we must avoid catastrophic risks. There is a lot of responsibility in very few hands. Let's get it right.

We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must…

RL is up next!

Frontier pretraining is said to be a big-lab-only game. We don’t have 100k chips yet, so there’s only one way: algorithmic efficiency. Our new recipe matches DeepSeek V4 Pro’s pretrain using 50x less compute – that’s roughly half the FLOPs used for GPT3, or ~$0.5M on GB200.
magic.dev/blog/pretraining

1
18
566
Thomas Schmied retweeted
The world will do its best to convince you that you can't do big things, but you can. I'm grateful for our team. Unmatched tenacity.
Frontier pretraining is said to be a big-lab-only game. We don’t have 100k chips yet, so there’s only one way: algorithmic efficiency. Our new recipe matches DeepSeek V4 Pro’s pretrain using 50x less compute – that’s roughly half the FLOPs used for GPT3, or ~$0.5M on GB200.
magic.dev/blog/pretraining
Thomas Schmied retweeted

Frontier pretraining is said to be a big-lab-only game. We don’t have 100k chips yet, so there’s only one way: algorithmic efficiency. Our new recipe matches DeepSeek V4 Pro’s pretrain using 50x less compute – that’s roughly half the FLOPs used for GPT3, or ~$0.5M on GB200.
magic.dev/blog/pretraining
Thomas Schmied retweeted

After automating AI research with @SchmidhuberAI and building AI Scientists at DeepMind, now comes the real experiment: the institution itself.
Excited to co-found @inherent_labs: the recursively self-improving lab for scientific AI.
inherentlabs.ai


We’re excited to introduce Inherent, a lab designed from scratch to build AI agents that discover new knowledge.
The coming era of machine-driven scientific inquiry demands a new kind of research institution and a new kind of AI.
To achieve our mission, we live within the experiment, recursively self-improving the entire research organisation. We investigate questions including:
- What does ‘AI taste’ look like in the sciences, and how can we build an institution that embraces this new aesthetic of discovery?
- What new kinds of human-machine teaming will make the most of AI that can truly innovate?
- How can we build recursive self-improvement at the collective level that continually increases human agency over outcomes?
We have just closed a $50m seed round led by @IndexVentures and @radicalvcfund, with participation from other outstanding investors including NVentures (@nvidia's venture capital arm), @buildexante, Metaplanet, Macroscopic, @MythosVentures, Charlie Songhurst, @chalfs, @jluan, @dwarkesh_sp, @Thom_Wolf, @j_foerst and @maxjaderberg. We are advised by @matthewclifford.
Inherent is a Public Benefit Corporation headquartered in London.

Thomas Schmied retweeted

xLSTM Distillation: arxiv.org/abs/2603.15590
Near-lossless distillation of quadratic Transformer LLMs into linear xLSTM architectures enables cost- and energy-efficient alternatives without sacrificing performance.
xLSTM variants of instruction-tuned Llama, Qwen, & Olmo models.


Thomas Schmied retweeted

Excited to share our new paper: Effective Distillation to Hybrid xLSTM Architectures.
TL;DR: we retrofit / graft / distill / linearize Transformers into xLSTM-SWA hybrids with fixed-size states.
This gives a practical path to studying linear and hybrid architectures starting from already strong pretrained models.

xLSTM Distillation: arxiv.org/abs/2603.15590
Near-lossless distillation of quadratic Transformer LLMs into linear xLSTM architectures enables cost- and energy-efficient alternatives without sacrificing performance.
xLSTM variants of instruction-tuned Llama, Qwen, & Olmo models.
Thomas Schmied retweeted

Ever wondered how linear RNNs like #mLSTM (#xLSTM) or #Mamba can be extended to multiple dimensions?
Check out "pLSTM: parallelizable Linear Source Transition Mark networks". #pLSTM works on sequences, images, (directed acyclic) graphs.
Paper link: arxiv.org/abs/2506.11997

Thomas Schmied retweeted

We’re excited to introduce TiRex — a pre-trained time series forecasting model based on an xLSTM architecture.

Thomas Schmied retweeted

🧵What if emergence could be explained by learning a specific circuit: sparse attention?
Our new work explores this bold hypothesis, showing a link between emergence and sparse attention that reveals how data properties influence when emergence occurs during training.

Thomas Schmied retweeted

Excited to share that 2 of our papers on efficient inference with #xLSTM are accepted at #ICML25.
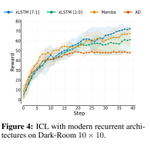
A Large Recurrent Action Model: xLSTM enables Fast Inference for Robotics Tasks (arxiv.org/abs/2410.22391)
and
xLSTM 7B: A Recurrent LLM for Fast and Efficient Inference:

Thomas Schmied retweeted

Agentic LLMs need to explore! The web is a non-stationary, highly partially unobservable 🏔️.
@thsschmied's @GoogleDeepMind internship systematically investigates current challenges and the role of scale, RL, and chain-of-thought reasoning to overcome them.
arxiv.org/abs/2504.16078
I.e. #ReinforcementLearning is back, and everything is an #agent (we could have realised that everything is an MDP without heavily misusing the agent term 😉)



Thomas Schmied retweeted
Large language models store vast amounts of knowledge, but how exactly do they learn it?
Excited to share my @GoogleDeepMind internship results, which reveal the fascinating dynamics behind factual knowledge acquisition in LLMs!
arxiv.org/abs/2503.21676

Thomas Schmied retweeted
Yesterday, we shared the details on our xLSTM 7B architecture. Now, let's go one level deeper🧑🔧
We introduce
⚡️Tiled Flash Linear Attention (TFLA), ⚡️
A new kernel algorithm for the mLSTM and other Linear Attention variants with Gating.
We find TFLA is really fast!
🧵(1/11)

Thomas Schmied retweeted

⚠️Beware: Your AI assistant could be hijacked just by encountering a malicious image online!
Our latest research exposes critical security risks in AI assistants. An attacker can hijack them by simply posting an image on social media and waiting for it to be captured. [1/6] 🧵
Thomas Schmied retweeted
Check out our latest work on scaling up xLSTM to 7B parameters and 2.3T tokens, with all open training data, open training protocol and open training code. Nice team work! 💪💪
Thomas Schmied retweeted
📢🔔I am excited to share the details on our optimized xLSTM architecture for our xLSTM 7B model!🚨
We optimized the architecture with two goals in mind:
- Efficiency (in Training and Inference)
and
- Stability
🧵(1/7)

Thomas Schmied retweeted

I am excited to present the result of a fruitful internship at @AIatMeta. We introduce preference discerning, which denotes in-context conditioning on user preferences expressed in text to steer the recommendation system. This enhances flexibility and personalization. 1/n


Newly published research for generative retrieval for recommendations from teams at Meta.
- Preference Discerning with LLM-Enhanced Generative Retrieval ➡️ go.fb.me/evvcu8
- Unifying Generative and Dense Retrieval for Sequential Recommendation ➡️ go.fb.me/i7l955

Thomas Schmied retweeted
𝗡𝗲𝘄 𝗣𝗮𝗽𝗲𝗿 𝗔𝗹𝗲𝗿𝘁: Rethinking Uncertainty Estimation in Natural Language Generation 🌟
Introducing 𝗚-𝗡𝗟𝗟, a theoretically grounded and highly efficient uncertainty estimate, perfect for scalable LLM applications 🚀
Dive into the paper 👇arxiv.org/abs/2412.15176
