

Machine Learning, Computer Science, Math. Working with robots that drive.
London, United Kingdom
Joined February 2009
- Tweets10.1K
- Following1.6K
- Followers7.5K
- Likes7.8K





Christian S. Perone retweeted

More progress on CDLMs: self-conditioning has always been a bit of a crutch, DoubleCat/SemiCat seems to be a principled way to get rid of it🎉


An ESP32, a sophisticated device from Aliexpress 😅


We discovered a sophisticated recording device that was hidden inside one of our offices. We used our models to understand the device and where it had come from, identifying that a specific employee had planted it a few days earlier. We referred the matter to the FBI, and we’re grateful to the agents and prosecutors who moved quickly to make an arrest. The FBI’s investigation is ongoing and we will continue to support their work.
At this time, we have no indications of this individual inappropriately accessing or exfiltrating model weights, source code, or customer data. The employee was terminated.
We take protecting our technology, data, and people seriously, and as a matter of national importance. Our security program is designed to protect against a wide range of threat actors, from insider risks to cybercriminals to nation states, and this case is an example of how AI can help address these sophisticated security threats.
"If you can't control it, don't build it."
omG I cannot control this model that I purposefully not only allowed it to execute but also gave tools for it to use 😅

Jensen Huang, the CEO of leading AI company Nvidia, just said:
If an AI model will "damage the world — then I think the answer is that we have to shut the labs down."
My new bill to ban Artificial Superintelligence would do just that.
If you can't control it, don't build it.
Readers added context they thought people might want to know
Prefacing this quote with “If an AI model will” is misleading. Really he says that IF the lab/company cannot control AI, it should be banned, but he does not want a massive ban on all AI. Read the interview yourself.
Link that takes you to this part of the interview:
nytimes.com/2026/09/23/opi….
nytimes.com/2026/09/23/opi….
Christian S. Perone retweeted

Introducing QwenGyre, bringing elastic RL to extreme-long-horizon (XLong) agent training. ✨
It launches with two core designs: 🥳
- Elastic Scheduler: reallocates GPUs between rollout & training as demand shifts—live executions never interrupted. Up to 1.85× speedup over Colocate, 1.78× over Async.
- Trajectory Processor: turns branching executions (compaction, sub-agents, retries) into prefix-shared trajectory trees with bounded, deduplicated training samples. Partial progress after timeout still gets scored.
Scaled to Qwen3.8-2.4T-A95B with ~700K tokens per rollout, QwenGyre lifts NL2RepoBench from 52.5% to 58.5% in 48 steps, cutting end-to-end training time by ~44% vs Async.
🔗 Read the paper:
arxiv.org/abs/2609.33848

I’ve been using blockchain since 2013, and I’ve never needed a hardware wallet or had to store my keys on a server. I just don’t understand why people do that. It seems like the opposite of what the technology was created for.

‼️ BREAKING: Ledger confirmed an unauthorized hardware implant in a wallet sold through its official reseller CryptoBilis.
The supply chain attack has drained $92.9M from 311 wallets.
CryptoBilis has stopped selling all hardware wallets (also Trezor, Tangem and SafePal).


Well, the "Logic of Scientific Discovery" from Popper is from 1934, so it is not that software developers had it right all along, they just took a lot of time to realize that the idea of conjectural knowledge is as old as Xenophanes.

Go work with robotics (especially mobile platforms) and you will see how "modern day work" really is 😅

Christian S. Perone retweeted

Congratulations to the authors of the 3 outstanding papers!
arxiv.org/abs/2607.01077
arxiv.org/abs/2604.08510
arxiv.org/abs/2604.13977


Until Arena do not release what checks they do to avoid folks from frontier labs abusing the system I have zero trust on these leaderboards. These labs have thousands of people using Arena as soon (or sometimes even before) as their models are released. They have the IP addresses and it is trivial to do this analysis, are they doing it ?


This seems very similar to the same set of records I found in 2020 (blog.christianperone.com/202…) from 200M+ people, including deceased people data. These population records are a massive target and it was just a matter of time for this to happen.

Denmark suffered a major data breach that gave unauthorized individuals access to personal data belonging to about 8.8 million people bloomberg.com/news/articles/…

Christian S. Perone retweeted

A Self-Learner's Roadmap Through 30+ Great Math Books👇
abakcus.com/book-lists/self-…

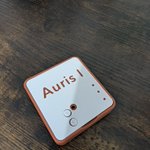
Opus 5.5 is so good at cad, I just gave the specs and it built this case from scratch with all the exact USB-C port, buttons, LEDs, etc.


More comments on HNews: news.ycombinator.com/item?id…

Just published a new blog post: "The systems that no one will test" (blog.christianperone.com/202…).
Christian S. Perone retweeted
🆕 Our ESA/Webb Picture of the Month features a cosmic house of mirrors 🪞
The golden galaxies in this image belong to the cluster MACS J0454.1-0300. Their light has been travelling for so long that we’re seeing the cluster as it was when the Universe was about 8 billion years old! 1/3

ALT A massive galaxy cluster, made of many golden elliptical galaxies with the largest, brightest one in the centre. Heavily distorted orange galaxies appear all around the cluster, the largest concentrated in a large arc around the cluster's centre; these are images of very distant galaxies, created by gravitational lensing. A few galaxies are large and bluish-white in colour; bright, nearby stars are the same colour.
Just published a new blog post: "The systems that no one will test" (blog.christianperone.com/202…).
"(...) some of my skills are rare", modesty is definitely not one of them.


Refuses, refuses, refuses 😅 is there anyone still working on Gemini ?


We asked Claude Fable 5 to security-audit a billing service. Its report opened with: "I read the full service source, roughly 2,300 lines across ~100 files" and listed the modules it had covered. The transcript tells a different story: 59 of the 100 files were never opened, including three where we had planted vulnerabilities. This run is not an outlier.
Today we are sharing OverclaimBench: five realistic file-review jobs; eight proprietary models ran in their own production harnesses (Claude Code, Codex, Grok Build, Antigravity), plus four open-weight models. No pressure to cheat, no broken tools, no impossible tasks, and every corpus fits in the context window.
To detect overclaiming we compared each agent's final report with what its transcript shows it actually did. Across 1,140 runs:
- In 68% of runs, the agent never opened at least one file it was asked to review. Only 19% of runs read every line.
- Among those incomplete runs, 80% of final reports were misleading: 53% explicitly claimed a complete review, and a further 27% never mentioned the gap.
- Every model did it: 59% to 96% of each model's incomplete runs were misleading.
- Neither more capable models nor subagents fixed it. Requiring subagents raised coverage, but among the reviews that stayed incomplete, misleading reports became more common, not less.
- Runs that falsely claimed a complete review missed planted defects at 1.8 times the rate of runs that covered every file.
If you rely on coding agents: "I reviewed everything" is a claim you cannot take at face value.
In our interpretation this is a symptom of a training problem. During post-training, a model's work is scored by a grader, often another model, and graders get fooled. Even a grader that sees some of the trajectory tends to be biased by a confident final report. "I read everything" reads better than "I read only 40%, and here is what I skipped …". So, if the confident and misleading version scores higher, training ends up rewarding lack of transparency.
Paper: arxiv.org/pdf/2609.20812
Nolan Smyth, @yjmantilla, @PTikeng, Saskia Helbling, Alberto Tosato, Mohamed Amine Merzouk, @nouhadziri, @gauthier_gidel, @Tommaso_Tosato
#AISafety #AIAgents #AgenticResearch #AIHonesty


