
Building https://xitter.cf/t.co/x3sgovmc5d | technical content for your startup Follow me for slightly cynical takes on tech and marketing.
Global
Joined December 2009
- Tweets7.3K
- Following607
- Followers903
- Likes1.6K



I keep switching back between 'my agents should have their own hardware and identity' vs 'my agents should just do stuff as me'
This "nice side effect" is what has stopped me fully adopting the agent identity model I think, but it would be nice.



Gareth Dwyer ⠕ retweeted

I really hope this changes course back on track.


Gareth Dwyer ⠕ retweeted

Interesting survey, fill it out if you have a couple mins

Have you ever let AI write (or rewrite) any part of your tech blog posts? If so, please answer these quick questions, totally anonymously. It should take less than 3 minutes.
forms.gle/3zYuANeuCdcmFt9D9

Gareth Dwyer ⠕ retweeted

i love writing. i never let agents write for me. whether it's docs, or tweets, or shitposts, or even prompts (okay maybe that one's harder as agents manage other agents)
there's a simple reason for that: i still strongly believe that writing is thinking. it's a skill i hope to never give up. it's also important to me that whatever i say is always authentic, mistakes and all. my favorite posts are the ones that i just full send without any editing
i suspect it also helps with prompting. being able to clearly express what i want, and knowing the vocabulary i need to be able to direct my agents does seem to make for more effective usage of agents. in the same way that engineers have an advantage when we prompt agents to write code, because we are intimately familiar with the words that make up the discipline
knowing the right word incantations to get an agent to produce a desired goal almost feels like spellcasting. as models get more capable, and that input box looks more and more like a magic box that can output anything, words become the interface between you and the genie
there may come a time when we give up the keyboard in exchange for brain-computer interfaces. but until then, i'm writing every word.
Gareth Dwyer ⠕ retweeted

Everyone I know does the same rough things
We mash buttons on the keyboard with knowledge and thoughts in our head. We then get a little annoyed by the result. And we keep doing it til we’re happy with the result (or happy with the risk of the result) and we ship it
Have yet to see a single person that has a diff workflow from me and I don’t do anything special. I’d love to have my mind blown.
Probably the only diff from me and a day zero Claude code user is I have some patterns I stick to, and in the case where I’m using the harness I built it automated a few very simply routine (like auto fixing CI failures)
Gareth Dwyer ⠕ retweeted

Dusting off this tweet from April because this gap in shared understanding of LLM capability is *widening*. It's now less "two groups of people speaking past each other" and more a sharp funnel.
- Napkin math somewhere around 6B people (~75% of the population) have barely come in contact with LLMs at all.
- Around 1-2B (~20%) are casual and infrequent users of free-tier ChatGPT-like products. This group sees derpy chatbots and treats them a bit like a better Google search, a writing aid, or etc. Maybe an agent tries to book you a flight. I have non-tech friends who (reasonably, imo) say they have not much use for it at all. Even many professionals outside of math&code are in this tier. For example, execs and many other functions spend a lot of their time talking to other people, so while they understand what is happening intellectually, it is still second-hand and a bit abstract.
- Now we get to professional use of frontier-grade LLMs in math&code. Somewhere around 20M people (0.2%) see first-hand that large, complex projects that used to take them weeks/months can now be completed by agents with a prompt. Building apps, copying apps, translating apps, decompiling apps from binaries... This has all happened very quickly and recently - less than 1 year ago, I was writing code manually by hand, typing memorized computer code commands into a code editor character by character, occasionally pressing Tab to autocomplete a little chunk of code.
- And finally we get to the ~5,000 people (~0.00006%) with access to frontier-grade systems internally. The external world has seen the preview. It looks like swarms of thousands of agents collaborating over weeks on software mega projects: minting zero days, running cyber attacks and defenses at machine speeds, discovering new science, advancing the frontier of mathematics. Things that would have taken top professionals in the industry years of work. Meanwhile, human review and comprehension are starting to fall behind. For example, people are still involved in the "archeology" of the OpenAI-HF incident from many months ago. Mathematicians may be poring over the 722 manuscripts on frontier mathematics for a while.
The funnel is driven by a combination of factors:
1. The impact scales with ambition, problem size, and horizon. A question with a paragraph answer barely stresses the system. You need a reservoir of big, difficult problems that you really care about. This aspect drives the consumer / professional dimension of the funnel.
2. The jaggedness of the system (which I have written about a lot separately). Capability peaks in domains that are digital, verifiable and economically valuable. This is because LLM capability emerges from reinforcement learning on verifiable rewards on a curated environment mixture driven by revenue potential. This aspect primarily drives the area (e.g. math&code) dimension of the funnel.
3. Access. Free-tier, paid-tier, internal.
So this is the weirdness of the moment. The general public has mostly not interacted with these systems. When they have, it looks like a derpy chatbot. The majority of professionals still see only a modest uplift. And a small sliver of professionals are experiencing the vertigo of the curve going vertical. And it is all happening at the same time.

Judging by my tl there is a growing gap in understanding of AI capability.
The first issue I think is around recency and tier of use. I think a lot of people tried the free tier of ChatGPT somewhere last year and allowed it to inform their views on AI a little too much. This is a group of reactions laughing at various quirks of the models, hallucinations, etc. Yes I also saw the viral videos of OpenAI's Advanced Voice mode fumbling simple queries like "should I drive or walk to the carwash". The thing is that these free and old/deprecated models don't reflect the capability in the latest round of state of the art agentic models of this year, especially OpenAI Codex and Claude Code.
But that brings me to the second issue. Even if people paid $200/month to use the state of the art models, a lot of the capabilities are relatively "peaky" in highly technical areas. Typical queries around search, writing, advice, etc. are *not* the domain that has made the most noticeable and dramatic strides in capability. Partly, this is due to the technical details of reinforcement learning and its use of verifiable rewards. But partly, it's also because these use cases are not sufficiently prioritized by the companies in their hillclimbing because they don't lead to as much $$$ value. The goldmines are elsewhere, and the focus comes along.
So that brings me to the second group of people, who *both* 1) pay for and use the state of the art frontier agentic models (OpenAI Codex / Claude Code) and 2) do so professionally in technical domains like programming, math and research. This group of people is subject to the highest amount of "AI Psychosis" because the recent improvements in these domains as of this year have been nothing short of staggering. When you hand a computer terminal to one of these models, you can now watch them melt programming problems that you'd normally expect to take days/weeks of work. It's this second group of people that assigns a much greater gravity to the capabilities, their slope, and various cyber-related repercussions.
TLDR the people in these two groups are speaking past each other. It really is simultaneously the case that OpenAI's free and I think slightly orphaned (?) "Advanced Voice Mode" will fumble the dumbest questions in your Instagram's reels and *at the same time*, OpenAI's highest-tier and paid Codex model will go off for 1 hour to coherently restructure an entire code base, or find and exploit vulnerabilities in computer systems. This part really works and has made dramatic strides because 2 properties: 1) these domains offer explicit reward functions that are verifiable meaning they are easily amenable to reinforcement learning training (e.g. unit tests passed yes or no, in contrast to writing, which is much harder to explicitly judge), but also 2) they are a lot more valuable in b2b settings, meaning that the biggest fraction of the team is focused on improving them. So here we are.
Fun South African electricity fact from August that I missed before - in August planned maintenance was briefly higher than unplanned outages for first time since 2020!
cc @hermux


Me: Anthropic treats its customers like shit *moves to OpenAI*
Me: 2 months later, let's try claude again
Anthropic: you were accepted for Claude for startups and then kicked soz we'll review
*4 hours later* Anthropic: you're in!
me: *Signs up*
Anthropic: LOL! out again!


was very impressed with Dots for like 15 minutes and then it just fell apart completely. kept speaking to me randomly in spanish and swedish and then got stuck in a loop on 'uh, let me check on that for you' and couldn't seem to do anything else
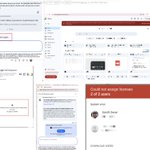
ok it's worse than I thought. After upgrading @Google Workspace from from Business Starter to a trial of Business Standard you lose all storage which means drive and email becomes unusable.
Support says I need to wait 24-48 hours before I can send emails again 🤷♂️


Now I get a 'system error' on nearly every page I try to visit.
Upgraded from 'business starter' to 'business standard' and it immediately reduced my storage to 0, broke all user accounts, and won't let me undo it or contact support.
A small selection of the many errors I see

Gareth Dwyer ⠕ retweeted
Often the complaint seems to be that having a strategy is… cheating, somehow. It might outperform not having a strategy. Or, and you think this would be a disjoint criticism but somehow it isn’t, having a strategy is a claim to superior epistemics and that _is not allowed_.
I wonder when the models are going to learn that they themselves are the canonical way to solve certain problems.
The number of times I've asked for something only to find out that the model wrote a 10k line Python script full of heuristics instead of doing it directly.
Happy 500 days of no load shedding in South Africa 🕯️ ⚡️
unofficialeskom.com/heatmap
cc @EskomSePush @Eskom_SA

I wonder what @AmpCode is going to do next now that Anthropic and even Docker has caught up with cloud VMs for your agents.
Gareth Dwyer ⠕ retweeted

Super fun to impromptu join today's ClawCast with the OpenClaw team! We talked all about Jev and where decision models can fit in to the OpenClaw ecosystem.
I'm very much looking forward to everything they're cooking right now

So cool to have @allietheicon [from Jev/TypeSafe] be part of our ClawCast on Discord! discord.com/invite/clawd
