
Assistant Professor of Political Science @UofT
Joined September 2016
- Tweets585
- Following916
- Followers7K
- Likes8.3K




Pinned Tweet
My parents sent me this mug with the abstract of my first solo publication. Such a cool gift! #phdlife #AcademicTwitter @ElectoralStdies

Semra Sevi retweeted

🚨 Super excited to share this new WP w/ @JoohyeJeong @AdamBerinsky, Soong & Parker.
We ask a simple but extremely practical Q for survey researchers: Does it matter where we place items/experiments in our survey?
Answer: Not really, no. 👍

Semra Sevi retweeted

This longer post goes out to everyone interested in estimating causal effects.
Suppose you’re evaluating whether a new after school tutoring program causes higher student test scores.
Before comparing test scores between those who were tutored and those who were not, you first want to know:
Were the students in the treatment and control groups similar before the program began? Did they have similar prior test scores, socioeconomic statuses, or levels of parental education?
Answering this question is informative of whether an estimate of the tutoring program's effects is, indeed, causal.
To assess this question, researchers use what they call "covariate balance tests."
Covariate balance tests compare treated and untreated individuals' characteristics to each other to see whether the two groups look comparable.
They usually do this with one characteristic at a time. They'll iteratively estimate regression models that predict baseline characteristics with treatment assignment.
Sometimes, they'll test all of the baseline characteristics at the same time. One way to do this is to regress treatment assignment on all baseline characteristics. You then report the joint significance of all baseline covariates. This is often referred to as an "omnibus test."
Testing for covariate balance like this is standard practice in causal inference across many fields.
It appears in the social sciences--being prevalent in economics, political science, sociology, and psychology studies that seek to estimate causal effects. It also regularly shows up in causal studies in the hard sciences.
But a recent paper by Bicalho, Bouyamourn, & Dunning in the journal Political Analysis argues that there’s an important blind spot in this approach.
Simply put: not all baseline covariates are equally informative.
Say in the tutoring example, we finding balance on students' eye color across the treatment and control groups. Bicalho, Bouyamourn, & Dunning argue that because eye color tells us almost nothing about future test scores, this test of covariate balance is not as valuable as, say, one on student test scores before the tutoring program began.
The difference between eye color and baseline test scores is "prognosis": some pre-treatment variables are much better than others at predicting what would have happened without the treatment.
Bicalho, Bouyamourn, & Dunning argue that researchers should first measure which covariates are actually predictive of the outcomes they are studying. Then, they should place more weight on those variables when evaluating covariate balance.
The authors argue that researchers should measure prognosis by fitting a model of the outcome using only the control group and reporting:
• an overall Prognosis R² (how much the covariates jointly explain the untreated outcome), and
• the individual prognosis of each covariate (its standardized regression coefficient), showing which variables are actually predictive.
Building on earlier work on prognostic scores, they argue that researchers should measure and report prognosis, collect more prognostic covariates when possible, and prioritize those covariates when interpreting or constructing balance tests.
The broader lesson is simple but important: before asking whether treatment and control groups are balanced, ask whether they’re balanced on the variables that actually predict the outcome you are interested in.
This is a thoughtful and important paper on how we evaluate causal inference studies!


Semra Sevi retweeted

Today is my first day in 5 years where I am *not* a DGS. It has been a pleasure, and I've learned a lot. Reflecting today, I won't give you one of those self-serving "7 traits of highly successful grad students" lists. Instead, here's 6:
github.com/ArthurSpirling/Be…

Semra Sevi retweeted

🚨🚨New paper in @Nature with @AshuAshok, @lukebeehewitt & @ghezae_isaias 🚨🚨
Can LLMs predict results of social science experiments?
Across 70 preregistered studies, we find strong correspondence (r=.85) between LLM-predicted and observed effects.
doi.org/10.1038/s41586-026-1… 🧵

Semra Sevi retweeted

🚨 The University of Toronto (St. George) is hiring in American Politics, with a focus on democracy in the United States. Please spread the word! I'm on the committee and am more than happy to answer questions.
Full ad & details here: jobs.utoronto.ca/job/Toronto…

Semra Sevi retweeted

Introducing ReproAI, an author-facing agentic AI plugin for replication packages: reproai.org/
Since we released the Scaling Reproducibility paper, many people have asked how they can make use of the pipeline.
Recall that, even after in-house reproducibility checks by journals, we still find many human errors in replication packages.
Gary @kinggary gave us a truly inspiring direction:
"With AI tools, the relationship among authors, journals, and replicators can become much more collaborative."
He suggested that we build a tool to help authors prepare replication packages before submission.
So we did, and it is fully open source.
Building on our experience replicating >500 papers, we summarized the most common problems we encountered.
Our goal is simple: help authors increase the chance that their replication packages can be run more easily by data editors, reviewers, and future researchers.
This task is actually much easier than third-party replication from scratch because authors know their papers best😺: they have the source files, understand the intended workflow, and can often fix bugs quickly once problems are identified.
Here is the first version. Let me show it using one of my old papers. 🧵

Semra Sevi retweeted

Why do arguments often change people’s beliefs without changing their attitudes? In a new APSR with @PatrickPLiu and Scott Clifford, we point to belief relevance: arguments are more persuasive when they grapple with the idiosyncratic reasons people hold their political views.

Semra Sevi retweeted

NEW in @ScienceAdvances, after 3 years of work with a great team:
We review and meta-analyze 100 immigrant conjoint experiments in 36 countries.
Immigration preferences are surprisingly similar across people and countries, but changing over time and structured by politics.
🧵

Semra Sevi retweeted
A monumental loss. Ran was not only a trailblazing and brilliant scholar; he was also a remarkably generous colleague and, what's more, a dear friend.
politics.utoronto.ca/news/me…

Semra Sevi retweeted

Field experiment presents causal evidence that Social media promotion improves job market outcomes | PNAS pnas.org/doi/10.1073/pnas.25…

Semra Sevi retweeted
So excited to finally share my job market paper!
The post-Floyd “Great Awokening” was driven by affluent white liberals and emphasized recognition over redistribution.
Consistent with elite capture of identity politics.
Feedback very welcome! Link below.

Semra Sevi retweeted
Excited to present my JMP at MPSA!
The post-Floyd “Great Awokening” was driven by affluent white liberals and emphasized recognition over redistribution.
Evidence from surveys, public discourse, and implicit bias data.
Consistent with elite capture of identity politics.
⬇️

Semra Sevi retweeted
It turns out people vote based on policy.
A sneak peek at our paper for MPSA next week, in a not-to-be-missed panel:
convention2.allacademic.com/…

Turns out most Canadians vote the party, not the person. Local candidates were decisive for just 5-8% of voters outside Quebec and 2-5% in Quebec. The data don't lie! /w @marcomavina & @ablais_ See paper here: cambridge.org/core/journals/…


My work with @marcomavina & @ablais_ shows that most Canadians vote the party, not the person! Local candidates were a decisive factor for 5-8% of voters outside Quebec, and just 2-5% in Quebec. See: cambridge.org/core/journals/…


Semra Sevi retweeted
@Nature has published three groundbreaking papers on reproducibility, analytical robustness, and replicability across the social sciences. Sincere thanks are due to the many folks who contributed to these projects. It’s painstaking work, and a great service to social science.


Semra Sevi retweeted
Our PNAS paper (@SemraSevi + Don Green) is a small step toward building this information layer, but as RAG gives way to massive context windows and agentic retrieval, the central challenge becomes curating and prioritizing high-quality information.

Amidst understandable concerns of AI dystopia, no one is offering a positive vision for how we can use AI to remake our institutions and reinvent how we govern. That’s what I try to offer today.
My argument is that we need an explicit research agenda to build “political superintelligence.” Here’s my case:
AI makes intelligence cheap and widely available, just as the printing press made information cheap and widely available—and that earlier revolution ultimately reshaped governance and society to our benefit.
To capture this benefit quickly, we need to build political superintelligence: a set of tools that help citizens, representatives, and institutions perceive the world more accurately, understand tradeoffs, contest power, and act more effectively.
I divide this research agenda into three layers:
1. The information layer: AI can make voters and governments dramatically smarter, but only if we fix political bias in models, improve the quality of sources AI draws on, and build trust through better performance.
2. The representation layer: AI can serve as tireless delegates acting on our behalf in political processes—monitoring government, filing comments, flagging decisions—but only if we solve preference drift, adversarial vulnerability, and the fundamental problem that we don't own our own agents today.
3. The governance layer: Even if we get the first two layers right, the infrastructure sits inside privately controlled companies. We need binding constitutional frameworks that distribute power, constrain companies, and ensure political superintelligence serves citizens rather than executives or shareholders.
Each of these layers has a concrete, tractable set of research questions: better evals, geopolitical forecasting as a test case, governance experiments at small scale, agentic simulations, and institutional designs modeled on centuries of constitutional thought.
The window for building these structures is narrow, and the right response is not to slow AI down but to speed up how fast we build the institutions that keep us free as AI grows more powerful.
As Thomas Paine wrote in 1776, “We have it in our power to begin the world over again.”
I hope you’ll read the full piece (linked below), which serves as a sort of manifesto for the Free Systems Lab, and that you’ll join me in the defining political economy research question of our time.

Semra Sevi retweeted

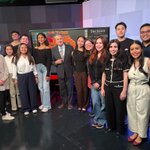
Great to welcome @UofT Professor Sevi’s 3rd-year political science class to #QueensPark this week!
From the gallery during Question Period to a conversation in the council chamber with Premier @fordnation, they got a front row look at how provincial politics works.
It was clear from their insightful questions that these students are receiving a world-class education that will set them up for success. I look forward to seeing all they will accomplish in their future careers!


Semra Sevi retweeted

New paper w/ @YamilRVelez! A lot of great research on political microtargeting discounts personalization: tailored ads (using AI or not) rarely beat a single-best message. We define two types of microtargeting, clarify when tailoring matters, & showcase a novel audio-based design

Semra Sevi retweeted

1/ Will voters participate in the primary of a party they oppose to prevent the nomination of a candidate they fear?
In a new paper in AJPS with @HayleyCohen, we study crossover voting using surveys and a large field experiment (N=83,902) in the 2024 New Hampshire Republican presidential primary.
onlinelibrary.wiley.com/doi/…
