

Joined November 2021
- Tweets364
- Following136
- Followers154
- Likes3.1K




Pinned Tweet
I always wanted a portfolio... but kept putting it off. since I'm not a designer.
I asked @ChatGPT Codex to plan UI, Claude did the mechanical work, and I gave feedback. My first portfolio, and I love it.
The kid in the stamp (me) follows your cursor.
samadpls.com
Ever wondered why some resumes never get a reply?
I opened the Indeed app with REA to see how applications get ranked.
One "No" on a must-have screener question can turn an application red before a human ever looks.
Tips in the video. Want more teardowns like this?
samadpls retweeted

When I launched Ask Pakistan, it could search 52 government websites. Today I added 140 more 🎉
It now searches 192 official sites, with 11,849 pages and 1,879 PDFs behind every answer.
Finding the right official page for something simple usually means ten open tabs and a broken link or two. That's the problem I'm trying to fix.
Some of what's new:
• Courts: Sindh, Peshawar and Balochistan High Courts, Federal Shariat Court, Wafaqi Mohtasib, Federal Tax Ombudsman
• Police & safety: Islamabad, Karachi, Balochistan, AJK and GB Police, Motorway Police, Punjab Safe Cities, Rescue 1122, NDMA and PDMAs
• Education & health: AIOU, NAVTTC, TEVTA, PMDC, DRAP, NIH, school education departments
• Utilities: Pakistan Post, WASA Lahore, KWSC, WAPDA, NEPRA, OGRA, PTA
• Business & tax: Pakistan Single Window, SMEDA, Board of Investment, Sindh Revenue Board, KP and Punjab Revenue Authorities
• Overseas Pakistanis: Ministry of Foreign Affairs, Ministry of Overseas Pakistanis
Ask the way you'd ask a friend, in English, Urdu or Roman Urdu 💬 Every answer still links to the official page it came from, so you can double-check it yourself.
It's still an independent project I'm building on my own. It isn't run by or connected to the government. I'm just trying to make official information easier to find 🇵🇰
Give it a try and tell me what's missing 🙌

indexing every database field sounds like a good idea.
but every index is another structure, often b-tree, that the db has to maintain.
reads can get faster.
writes get more expensive because inserts, updates, and deletes may also need to update those indexes.

spent this week around mountains and away from screens.
good reminder that life is bigger than ai agents, evals, latency, and whatever else we're optimizing this week.
sometimes the best reset is just going somewhere your laptop feels irrelevant.

one interesting design choice in whatsapp is that delivered messages aren't kept forever on whatsapp's servers.
once delivered, your phone becomes the main place that chat history lives.
if you enable backups, those can go to your google account on android or icloud on iphone.
that means whatsapp doesn't have to behave like permanent cloud storage for every delivered conversation.
at whatsapp scale, that's a meaningful architectural difference.
billions of users generate an enormous amount of text, photos, videos and voice notes.
keeping all of that permanently on whatsapp-owned infrastructure would be a very different storage problem.
sometimes an important backend decision isn't how to store more data.
it's deciding what data your backend doesn't need to own forever.

have you ever noticed cloud providers are very generous when you send data in, but start charging when you send data out?
that's ingress vs egress.
ingress is usually cheap or free because providers want it to be easy to move workloads into their cloud.
egress is different.
once data leaves their network, they have to pay for bandwidth, transit, peering, edge capacity, and the infrastructure carrying that traffic to users or another cloud.
but there is also a business reason.
free ingress makes migration in easy.
paid egress makes migration out expensive.
so over time your data develops gravity.
the more data you store in one cloud, the more expensive it becomes to move away.
this is why network cost matters more than most new developers expect.
compute is not always what gets you.
sometimes it's moving the bytes.

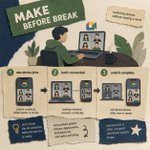
have you noticed when you switch a google meet from your laptop to your phone, the conversation barely breaks?
that tiny ux detail hides a nice systems idea: make-before-break.
instead of:
disconnect laptop → connect phone
the new device first joins the same meeting, establishes its media connection, and only then does the old device leave.
so for a short moment, both paths can exist.
once the new one is ready, meet switches over.
the general idea is simple:
don't destroy the old connection before the new one is ready.
sometimes seamless ux is just good distributed-systems design hiding underneath.

a common mistake i see newer developers make is calculating api latency using the average.
and here's the part you might not know: in production, we usually don't optimize latency around the average.
imagine 100 requests come in.
99 finish in 50ms.
1 takes 5 seconds.
the average is still around 100ms.
so your dashboard might say:
average latency = 100ms
sounds fine.
but that number doesn't tell you how many requests actually met your performance target.
this is why we use percentiles.
if we say:
p99 < 100ms
we're saying 99% of requests should finish within 100ms.
we accept that the remaining 1% can be slower because real systems will always have outliers: network delays, cold caches, slow database queries, gc pauses, external apis, etc.
if we need a stricter target:
p99.9 < 100ms
now 99.9% of requests need to stay below 100ms and only 0.1% can fall outside it.
that's the important difference.
average tells you the average of what happened.
p99 tells you whether almost all of your requests are actually meeting the latency target.
next i'll talk about latency vs request time vs throughput because those three also get mixed up a lot.
Content Generated using @HeyOz_AI
if you're using redis as a cache, there are three failure modes you should understand before you start trusting it with production traffic:
cache penetration , cache stampede and cache avalanche.
they sound similar. they are not.
cache penetration happens when requests keep asking for data that doesn't exist.
someone requests user:99999999. redis doesn't have it, so you check postgres. postgres says it doesn't exist. next request comes in and you do the exact same thing again.
redis is technically working perfectly, but it's protecting nothing because misses for nonexistent data keep going straight through to the database.
the fix can be as simple as caching the negative result for a short ttl. at larger scale you might put a bloom filter in front of the lookup so obviously invalid keys never reach the database at all.
cache stampede is different.
imagine one expensive key gets a lot of traffic. while it's cached, everything is fine. then the ttl expires.
now 2,000 requests arrive around the same time, all miss redis, and all decide they should regenerate the same value.
one expired cache entry turns into 2,000 database queries.
this is where request coalescing, distributed locking, or stale-while-revalidate matters. one request should rebuild the value. everyone else should wait or temporarily receive the stale value.
then there's cache avalanche.
this usually isn't one hot key expiring. it's thousands of keys expiring together.
maybe a deployment populated the cache at 10:00 and every key got a 60-minute ttl.
11:00 arrives and suddenly a huge percentage of your cache disappears at once.
traffic that redis had been absorbing gets dumped directly onto the database.
the boring fix is randomized ttl.
instead of every key living exactly 60 minutes, make it something like 50 to 70 minutes. expirations get spread over time instead of becoming a synchronized event.
what i found interesting is that adding redis doesn't automatically make your system more resilient.
sometimes you've just moved the failure point.
the important question isn't only "what happens on a cache hit?"
image generated using @HeyOz_AI


samadpls retweeted
We're heading to AI Seekho Builders Day 2026 with GDG Kolachi — 2 days, 1 real problem, and a product we're taking from idea to market.
📍 Ashritech, NASTP Karachi 🗓️ Aug 8–9, 2026
#AISeekhoBuildersDay #GDGKolachi #BuildInPublic #Hackathon2026 #Voicepls

if you're building evals for anything that generates images, audio, or video, don't hand your judge model the raw media. it will hallucinate.
this is the trap most multimodal eval systems fall into. you generate a 10-second ad video. you send it to gpt-5 vision and ask "does this match the brief." the model watches some of it, invents a transcript for the parts it didn't understand, praises a scene that doesn't quite exist, and returns a confident 8 out of 10.
that score is worthless. you can't reliably grade what the judge can't reliably perceive.
the fix is boring and correct. extract signals first. then hand the judge a compact brief instead of the raw file.
for a video that means: parse the actual duration with ffmpeg. run transcription and get the spoken words. sample frames at the start, middle, and end. compare the transcript against the script we planned. flag if the duration doesn't match the ask. then the judge opens its context with "duration 8s but script covers 5s, transcript says X vs planned Y, first and last frame attached."
half the verdict is computed before the judge speaks. the objective failures (wrong duration, missing headline in the ocr, no dialogue audio when the script called for it) become hard gates that don't need an llm at all. the judge only scores the subjective residue: does the composition feel right, is the opening hook strong, does the pacing land.
we do this at @HeyOz_AI for image, audio, and video creations. it dropped judge hallucination from a real problem to a rounding error, and it made the scores actually correlate with what customers keep versus what they delete.
if you're evaluating multimodal output, extract first. the judge should score the parts that need judgment, not the parts a script could have measured.
Content Generated using @HeyOz_AI

most teams treat "evals" as one thing. that's the first mistake.
I split ours into three separate processes. it's the reason our system actually catches regressions instead of just producing pretty dashboards.
process 1: deterministic checks.
plain code. no llm. runs on everything. this is where we catch the boring failures that make up most production bugs. did the agent pick the right tool. did the output leak a mongo id or a raw error. does the duration in the video request match the script we wrote. does the aspect ratio match the ask. all of that is regex, contract checks, and parameter comparison. costs nothing. runs on every turn. hard-gates ci if it fails.
process 2: quality checks with an llm judge.
this is for text: chat replies, generated documents, marketing hooks. we use rubric-based judges (relevancy, brand voice, faithfulness) with narrow dimensions. never ask the model "is this good." always ask "does this match the brief" or "is this our voice." decomposed grading is what makes the score usable.
process 3: multimodal with extract-first.
this one's the trick. we never hand a judge raw media. images, audio, and video get preprocessed first. ocr extracts text and colors. transcription extracts spoken words. ffmpeg extracts duration and frame samples. then the judge sees a compact brief with the extracted signals plus one or two reference frames. half the verdict is computed before the judge speaks, and it can't hallucinate a transcript we handed it.
the rule underneath all three: if plain code can decide, never pay an llm. if an llm has to decide, hand it structured signals not raw noise. and only the deterministic layer is allowed to break the build.
that separation is what makes evals work in production instead of turning into a science project.
content generated using @HeyOz_AI (my product)

so a common pattern i see on every scaling problem is someone saying "just put a queue in front of it." sometimes it's the right answer. often it just moves the problem somewhere else and hides it behind a healthy-looking metric.
a queue doesn't remove latency. it moves it. if the downstream work takes 30 seconds per message, the queue means those 30 seconds happen later. the api returns 200 ok in 50ms, and the actual work quietly sits in a queue for hours until someone notices the customer is still waiting.
a queue doesn't fix your slow database. it just gives you a bigger place to stack requests that will still be slow when they get there.
so when should you use one?
use a queue when the caller doesn't need an answer right away.
skip it when the caller needs a result immediately, or when the real problem is the database or the consumer, not the api.
before adding a queue, ask what's actually slow, what's actually failing, and whether the fix belongs at the source.
a queue in front of a broken system just gives the failure more room to grow.
there's an idea called the doorman fallacy that keeps coming to mind every time i see another "we're replacing x with ai" announcement.
@rorysutherland coined it in his 2019 book alchemy. picture a luxury hotel. a consultant watches the doorman for an hour and reports back. "he opens doors. we can automate that." sliding doors get installed. the doorman is let go. costs drop.
six months later, the atmosphere feels colder. regulars aren't remembered. taxis stop less often. someone dodgy hangs around the entrance and nobody moves them along.
the mistake was defining the job as "opens doors" when the doorman was also doing security, brand signaling, memory of regulars, informal customer service, and dozens of judgment calls that never made it into a job description.
this is happening at scale in 2026 and being called ai strategy.
commonwealth bank of australia fired 45 customer service staff and rolled out an ai voice bot. their reasoning: the bot cut call volumes. the union pushed back. the bank reversed the layoffs and admitted they "did not adequately consider all relevant business considerations." those considerations are the invisible parts of the doorman's job.
a study by orgvue found that 55% of companies that replaced staff with ai now admit they adopted too early.
the pattern is the same every time. take a role. reduce it to its most measurable task. automate that task. wonder why the metric moved in the wrong direction six months later.
the useful move isn't "replace humans with ai." it's "figure out which parts of a job are actually rule-based and repetitive, let ai handle those, and let the human focus on everything else."
worth thinking about before the next headline announces ai replacing another whole role.
image created using @HeyOz_AI (my product)

heard of the 3-second rule for api design? it's one of the simple habits that separates engineers who ship features from engineers who ship systems.
before you finalize any endpoint, ask yourself one thing: what if this exact request came in twice, three seconds after a database recovery?
if the endpoint handles it cleanly, meaning same result, no double side effects, you're safe. that's what idempotent means. call it twice, get the same outcome.
if the endpoint corrupts state on the second call, you've built fragility. because in production, this scenario happens constantly. networks drop mid-request.
clients retry. background jobs restart. one of your services times out and the client hits retry. from the database's perspective, all of these look identical.
the fix isn't hard. accept an idempotency key on writes. store the result keyed by that. next call with the same key returns the cached result instead of executing again. stripe does this. shopify does this. every payments system that refuses to charge cards twice does this.
but the rule isn't about the fix. it's about the reflex. senior engineers see a create endpoint and immediately ask what happens on retry. task executors see a create endpoint and immediately ask what fields to add to the response.
both endpoints work in staging. only one of them survives production.
content generated using agent @HeyOz_AI
here is the thing: type one character in cursor and by the time you look up, it's suggested 40 characters of code.
how is this fast enough to work?
three engineering tricks stacked on top of each other.
first, yes it's not claude opus or gpt-5. autocomplete uses a small specialized model. cursor built its own sparse mixture-of-experts model just for edits. it's much smaller than chat models but way better at one specific job: filling in code between what exists before and after your cursor. that's called fill-in-the-middle. it's why autocomplete feels smarter than chat when you're mid-line.
second, speculative decoding using your own code as the draft. normal speculative decoding uses a small draft model to guess tokens ahead. cursor realized that when you're editing, most of the output will be the same as what's already there. so instead of a draft model, they feed the existing code back to the model as the draft. the model mostly says "same, same, same" until it hits the spot that changes. cursor claims a 13x speedup on full-file edits from this alone.
third, prompt caching. the same file context gets sent on every keystroke. instead of reprocessing it, the model server caches the kv states from the last request. only the new bits get computed. this is what turns tab autocomplete from an unaffordable feature into a viable one.
client side: 75ms debounce so fast typing doesn't fire 20 requests, and cancellation so any in-flight response gets thrown away the moment you type another character.
that's how you get sub-200ms autocomplete on real code. not one clever trick. a stack of them working together.
content generated using @HeyOz_AI
🤖 Made with AI
are we about to see a shift in how everyone thinks about ai?
for two years, ai was a flat subscription. $20 a month, use it all you want. that model is breaking.
github copilot moved to usage-based billing on june 1. heavy users were consuming three to eight times the token value of their $10 plan. microsoft was losing about $20 per user every month. when you're losing money on every single user, that math has to change.
even microsoft, the deepest pocket in the room, cancelled its own internal claude code licenses on may 15 and moved engineers to a cheaper tool. if microsoft can't afford it, who can.
the pattern looks a lot like what happened to cloud a decade ago. early aws felt cheap. then companies grew, ran more workloads, and discovered the bill scales with usage. nobody calls aws a "subscription." they call it consumption.
ai is heading the same direction. it's stopping being a subscription and starting to look like a metered cloud service. you pay for what you use. heavy users pay a lot. light users pay almost nothing.
what changes for engineers building with ai. you start thinking the way devops teams think about aws. watch the tokens. cap the agents. measure cost per outcome, not cost per call. treat ai spend like any other infra line item, because that's what it's becoming.
the free trial era is closing. the meter is on
Content generated using @HeyOz_AI (heyoz.com)
i got gsoc 2024. acceptance rate was around 4 percent. here's how i did it when i wasn't supposed to.
there are two known ways in.
> one. you're already a strong candidate. your github is full of real projects. you've done internships at companies people recognize. mentors look at your profile and the choice is easy.
> two. you've been contributing to that org for months. the mentor knows your prs. they've seen how you work. by the time you apply, you're not a stranger.
i had neither.
so i made a third way.
i had been contributing to a repo that didn't get into gsoc the previous year. i was hoping it would get in the next round. by september i started getting nervous. what if it doesn't get in again?
then someone i follow liked a repo from a research lab at tu munich. a pure machine learning library built for a specific scientific use case. phd professors and their students. complex codebase. not on the gsoc list. not going to be on the gsoc list.
i spent weeks reading the code. then i shipped a real contribution. nothing small. real work on a real problem. and the domain mattered. it was the same kind of hardcore ml and neuroscience work i wanted to do in gsoc.
when @googleoss applications opened, i emailed mentors at the orgs running ml and neuroscience projects. i didn't lead with my resume. i led with what i had built at tu munich. same domain, same depth, real shipped work.
multiple mentors replied. one of them said "we've been looking for exactly this kind of background." they helped me fix my proposal directly. i knew i was in before results were out.
that's how i got gsoc 2024 at @INCForg