

Moody developer with a penchant for making cutting remarks. Interested in the marvels of the universe #Ravenclaw #Tech #SJSU
Joined June 2014
- Tweets5.9K
- Following705
- Followers108
- Likes6.1K


Ashutosh retweeted
I’ve Read 20+ Books on Agentic AI - Here Are My Top 5 Recommendations for 2026 buff.ly/OcUxP6v

Ashutosh retweeted

𝗖# 𝟭𝟰 𝘀𝗵𝗶𝗽𝗽𝗲𝗱 𝘄𝗶𝘁𝗵 𝗲𝗶𝗴𝗵𝘁 𝗿𝗲𝗮𝗹 𝗹𝗮𝗻𝗴𝘂𝗮𝗴𝗲 𝗰𝗵𝗮𝗻𝗴𝗲𝘀.
Runs on .NET 10, available now in Visual Studio 2026 or the .NET 10 SDK. Here's the full list:
𝗘𝘅𝘁𝗲𝗻𝘀𝗶𝗼𝗻 𝗺𝗲𝗺𝗯𝗲𝗿𝘀
→ Declare extension properties, static extension members, and operators, not just methods
𝗧𝗵𝗲 𝗳𝗶𝗲𝗹𝗱 𝗸𝗲𝘆𝘄𝗼𝗿𝗱
→ Reference a compiler-synthesized backing field right inside a property accessor; no manual field needed
𝗡𝘂𝗹𝗹-𝗰𝗼𝗻𝗱𝗶𝘁𝗶𝗼𝗻𝗮𝗹 𝗮𝘀𝘀𝗶𝗴𝗻𝗺𝗲𝗻𝘁
→ ?. and ?[] now work on the left side of an assignment; the right side never evaluates when the target is null
𝗻𝗮𝗺𝗲𝗼𝗳 𝘄𝗶𝘁𝗵 𝘂𝗻𝗯𝗼𝘂𝗻𝗱 𝗴𝗲𝗻𝗲𝗿𝗶𝗰𝘀
→ nameof(List<>) works directly, no more picking a throwaway type argument just to get the name
𝗜𝗺𝗽𝗹𝗶𝗰𝗶𝘁 𝘀𝗽𝗮𝗻 𝗰𝗼𝗻𝘃𝗲𝗿𝘀𝗶𝗼𝗻𝘀
→ T[], Span, and ReadOnlySpan convert into each other automatically, including through extension method receivers
𝗟𝗮𝗺𝗯𝗱𝗮 𝗽𝗮𝗿𝗮𝗺𝗲𝘁𝗲𝗿 𝗺𝗼𝗱𝗶𝗳𝗶𝗲𝗿𝘀
→ Add ref, out, in, or scoped to a lambda parameter without typing the whole parameter list
𝗠𝗼𝗿𝗲 𝗽𝗮𝗿𝘁𝗶𝗮𝗹 𝗺𝗲𝗺𝗯𝗲𝗿𝘀
→ Constructors and events can now split into a defining declaration and an implementing declaration, same as partial methods
𝗨𝘀𝗲𝗿-𝗱𝗲𝗳𝗶𝗻𝗲𝗱 𝗰𝗼𝗺𝗽𝗼𝘂𝗻𝗱 𝗮𝘀𝘀𝗶𝗴𝗻𝗺𝗲𝗻𝘁
→ Override += and friends to mutate a value in place, instead of always going through operator+ and allocating a new instance
📌 If you found it helpful, then you should join my weekly .NET newsletter with 10k+ engineers. Subscribe here → mwaseemzakir.com
Repost ♻️ would be appreciated
#csharp
#dotnet
#dotnetcore
#csharp14
#programming

Ashutosh retweeted

𝗪𝗵𝗮𝘁 𝗔𝗿𝗲 𝗗𝗶𝘀𝘁𝗿𝗶𝗯𝘂𝘁𝗲𝗱 𝗠𝗼𝗻𝗼𝗹𝗶𝘁𝗵𝘀?
When we talk about monoliths over the past few years, we hear they are bad and have a negative connotation. One of the main reasons for this is that those monoliths are connected with legacy systems.
The phrase "𝗺𝗼𝗻𝗼𝗹𝗶𝘁𝗵" can suggest that the software for a whole system or application is contained in a container made to house several subsystems. Most or all the subsystems of an entire application or system are stored in the monolith container. It is referred to as 𝘀𝗲𝗹𝗳-𝗰𝗼𝗻𝘁𝗮𝗶𝗻𝗲𝗱 𝘀𝗶𝗻𝗰𝗲 𝗲𝘃𝗲𝗿𝘆 𝗰𝗼𝗺𝗽𝗼𝗻𝗲𝗻𝘁 𝗼𝗳 𝘁𝗵𝗲 𝘀𝘆𝘀𝘁𝗲𝗺 𝗶𝘀 𝗵𝗼𝘂𝘀𝗲𝗱 𝗶𝗻 𝗮 𝘀𝗶𝗻𝗴𝗹𝗲 𝗰𝗼𝗻𝘁𝗮𝗶𝗻𝗲𝗿.
𝗔𝗿𝗲 𝗺𝗼𝗻𝗼𝗹𝗶𝘁𝗵𝘀 𝗯𝗮𝗱? They are not. What is bad is their internal state during development over a long time usually. We can have architected monoliths that will fulfill all our use cases and request architecture attributes in the system without dealing with the complexity of microservice architecture.
𝗧𝗵𝗲 𝗯𝗲𝘀𝘁 𝗲𝘅𝗮𝗺𝗽𝗹𝗲 𝗼𝗳 𝘁𝗵𝗶𝘀 𝗶𝘀 𝗦𝗵𝗼𝗽𝗶𝗳𝘆, with over 3 million lines of code one of the largest monoliths in the world. Instead of rewriting its entire monolith as microservices, Shopify chose modularization as the solution. Also, monoliths can scale, they served 117 million requests per minute on app servers during Black Friday in 2025.
There are three types of monoliths:
𝟭. 𝗧𝗿𝗮𝗱𝗶𝘁𝗶𝗼𝗻𝗮𝗹 𝗺𝗼𝗻𝗼𝗹𝗶𝘁𝗵𝘀
These are the most common monolith types, where everything is bundled together. Usually, we have some user interface, business logic, and data access layers in a single tier and deployment.
There are no clear boundaries between domains, and the code will have shared libraries.
𝟮. 𝗠𝗼𝗱𝘂𝗹𝗮𝗿 𝗺𝗼𝗻𝗼𝗹𝗶𝘁𝗵𝘀
With modular monoliths, we have defined clear functional slices and dependencies, meaning each module can be independent of the others. Yet, there will still be a single deployment unit and a single database.
𝟯. 𝗗𝗶𝘀𝘁𝗿𝗶𝗯𝘂𝘁𝗲𝗱 𝗺𝗼𝗻𝗼𝗹𝗶𝘁𝗵𝘀
Here, we have one modern monolith variant (antipattern), where our system is deployed like a microservice architecture but built with monolith principles in mind. We usually get to this point while attempting to build a microservice architecture without considering some architectural and process changes needed.
We know we have a distributed monolith when some services cannot be deployed separately, are chatty, cannot scale, and share the same data source.

Ashutosh retweeted
System design is how large-scale applications get planned before they’re built.
And in this course, you’ll learn how to design scalable, reliable systems step by step.
It covers APIs, databases, caching, and real-world architecture patterns.
freecodecamp.org/news/learn-…


Ashutosh retweeted

Different companies test different patterns. 📌
Use this company-wise DSA cheat sheet to focus on what actually matters for your target company.
Need help mastering those topics?
Here are the best free resources:
Learn DSA
• Striver A2Z
takeuforward.org/strivers-a2…
• NeetCode Roadmap
neetcode.io/roadmap
• CP-Algorithms
cp-algorithms.com/
Visualize Algorithms
• VisuAlgo
visualgo.net/
• USFCA Algorithm Visualizer
cs.usfca.edu/~galles/visuali…
Practice
• LeetCode
leetcode.com/
• Codeforces
codeforces.com/
• AtCoder
atcoder.jp/
• CodeChef
codechef.com/
Mock Interviews
• Pramp
pramp.com/
• Interviewing.io
interviewing.io/
Patterns & Complexity
• Big-O Cheat Sheet
bigocheatsheet.com/
• AlgoMonster Flowchart
algo.monster/flowchart
Revision
• Tech Interview Handbook
techinterviewhandbook.org/
Study company-wise.
Practice pattern-wise.
Interview with confidence.
Bookmark this.

Ashutosh retweeted

this is f*cking gold
a guy spent 6 weeks with no sleep building a personal AI agent from scratch, then wrote down all 100 things he learned
not a chatbot wrapper. an assistant that manages tasks, tracks deals, reads emails, and flags things before you even ask.
if I had this before I built my first agent, I would've skipped a month of trial and error
in the right hands, this changes everything:
→ separate hard rules from guidelines
→ give your agent a name, a voice, a role
→ build a Capability and a Component Map
→ write a Constitution, not a system prompt
And that's tip 5 out of 100.
(All tips are dropped in the comments below)
then read the full article below: ↓


Ashutosh retweeted

RIP toy projects.
If your portfolio doesn’t touch real business problems, you’ll get filtered out.
Here are 300+ real ML system case studies from top companies (free).

Ashutosh retweeted

Many engineers miss critical real-world system design concepts, most notably idempotency, cache stampedes, and failure domains. Focusing only on high-level architecture means forgetting the messy operational edges where systems actually break down.
Idempotency : Repeating a network request (like a payment click) should not repeat the side effect, but many APIs fail to use unique request tokens or tracking IDs.
blog.bytebytego.com/p/master…
oneuptime.com/blog/post/2026…
Stampede: When a popular cache key expires, a thousand concurrent requests miss the memory layer and slam the primary database all at once.
medium.com/@rachoork/critica…
vergecloud.com/blog/what-is-…
Failure Domains: People group servers or databases into separate logical units while keeping them in the exact same physical rack or availability zone power supply.
github.com/keyvanakbary/lear…
Graceful Degradation: Designing what happens when a third-party microservice completely dies instead of letting the main application thread hang indefinitely.
sreschool.com/blog/comprehen…


Ashutosh retweeted

System Desing- Event Driven Architecture & Messaging – Day 41
Why Message Queues?
The Problem with Synchronous Communication
Your application has grown into multiple microservices.
A customer places an order.
Your Order Service immediately calls:
- Payment Service
- Inventory Service
- Email Service
- Notification Service
- Analytics Service
Everything happens synchronously.
Client
│
Order Service
├──► Payment
├──► Inventory
├──► Email
├──► Notification
└──► Analytics
Looks fine...
Until one service becomes slow.
Suppose the Email Service takes 5 seconds to respond.
Now this happens:
Order Service
│
Waiting...
│
Email Service
The customer keeps waiting.
Even though the payment was successful.
One slow service delays the entire request.
Now imagine the Email Service goes down.
Order Service
│
Email Service
✖
Should the customer be unable to place an order just because an email couldn't be sent?
Of course not.
This is where Message Queues come in.
Instead of calling every service directly...
The Order Service publishes a message.
Order Created
│
▼
Message Queue
Other services consume it independently.
Message Queue
/ | \
▼ ▼ ▼
Email Inventory Analytics
Now:
✔ Customer receives a response immediately.
✔ Email can be sent later.
✔ Analytics can process independently.
✔ Inventory updates asynchronously.
Why Message Queues?
1. Decoupling
Services no longer depend on each other's response time.
2. Better Performance
The client doesn't wait for every downstream operation.
3. Better Reliability
If Email is temporarily unavailable:
The message stays in the queue.
It can be processed later.
4. Better Scalability
Need more throughput?
Add more consumers.
Queue
│
├──► Worker 1
├──► Worker 2
├──► Worker 3
Real Example
When you order on Amazon:
You immediately receive:
"Order Placed Successfully"
But behind the scenes...
- Payment processing
- Inventory updates
- Shipping
- Invoice generation
- Recommendation updates
- Email notifications
don't all happen in a single synchronous request.
Many of these tasks are handled asynchronously.
Synchronous vs Queue-Based
Synchronous
Order
│
Payment
│
Inventory
│
Email
│
Notification
One slow service affects the entire chain.
Queue-Based
Order
│
Queue
├──► Payment
├──► Inventory
├──► Email
└──► Analytics
Each consumer works independently.
Key Takeaway
Message queues don't make systems faster by themselves.
They make systems more resilient, scalable, and loosely coupled.
Instead of waiting for every task to finish...
Applications can acknowledge the request quickly and process non-critical work asynchronously.
That's why almost every large-scale distributed system relies on messaging.
Tomorrow we will compare the three most popular messaging systems:
Kafka vs RabbitMQ vs ActiveMQ

Ashutosh retweeted

The AI protocol stack in one list
▪️ MCP
▪️ A2A
▪️ ACP
▪️ AG-UI
▪️ ANP
▪️ LSP
▪️ OpenAPI
▪️ OAuth 2.0
▪️ OpenTelemetry AI
▪️ JSON Schema
▪️ JSON-RPC 2.0
Bookmark the list to keep it handy!
Here is also a practical guide explaining all these protocols - what each one does, where it fits, and when to use it.
Check it out → turingpost.com/p/ai-protocol…

Ashutosh retweeted

Kubernetes Components explanation:
📦 Pods → Where your application runs
🖥️ Nodes → Machines that host Pods
🌐 Cluster → Collection of Nodes managed together
🔄 Deployment → Ensures your application stays updated and available
👥 ReplicaSet → Maintains the desired number of Pods
💾 StatefulSet → Designed for databases and stateful applications
⚙️ DaemonSet → Runs one Pod on every Node (great for monitoring/logging agents)
✅ Job & CronJob → One-time and scheduled tasks
🌍 Service → Gives Pods a stable network identity
🚪 Ingress → Routes external traffic to your applications
🔐 ConfigMap & Secret → Manage configuration and sensitive data securely
💽 PV & PVC → Persistent storage for applications
🏷️ Namespace → Organize workloads across teams or environments
🤖 Kubelet → Agent running on every Node
🔀 Kube-Proxy → Handles networking between services and Pods
🎯 Scheduler → Decides where Pods should run
🧠 API Server → The heart of Kubernetes communication
⚡ Controller Manager → Continuously keeps the cluster in its desired state
💡 Think of Kubernetes like a city:
🏙️ Cluster = City
🏢 Nodes = Buildings
🏠 Pods = Apartments
👨💼 Deployment = Property Manager
🚦 Service = Reception Desk
🛣️ Ingress = Main Entrance Gate
📦 PV/PVC = Storage Room

Ashutosh retweeted

Backend Roadmap (Part 1/11): API Design 📌
APIs are the backbone of every modern application.
Wrong API choice -> performance bottlenecks, scaling nightmares, unhappy developers.
In this post, I covered:
• REST - Simple, stateless, uses HTTP methods. The industry standard for public APIs.
• GraphQL - Client asks exactly what it needs. No more over-fetching or under-fetching.
•gRPC - Binary + HTTP/2 = blazing fast. Built for high-performance microservices.
The real skill isn't knowing all three - it's knowing when to use which:
- REST -> Public APIs, simple CRUD, easy caching
- GraphQL -> Complex queries, multiple clients (mobile + web)
- gRPC -> Internal services, real-time streaming, low latency
Don't just memorize definitions. Understand the trade-offs.


As a backend developer in 2026, these are the 11 skills that will keep you relevant in today's job market:
1) API Design -> REST, GraphQL, gRPC
2) Authentication & Authorization -> OAuth 2.0, JWT, OpenID Connect, Passkeys
3) Databases -> SQL, NoSQL, indexing, query optimization, sharding
4) Caching -> Redis, CDNs, edge caching strategies
5) Event-Driven Systems -> Kafka, Pulsar, streaming pipelines
6) Concurrency & Async Programming -> Async I/O, reactive programming, structured concurrency
7) Distributed Systems -> Microservices, service mesh, eventual consistency
8) Security -> HTTPS, encryption, Zero Trust, OWASP Top 10
9) Observability -> Logging, metrics, tracing, OpenTelemetry
10) Cloud & Deployment -> Docker, Kubernetes, serverless, GitOps
11) AI Engineering -> LLM APIs, MCP, AI agents, vector databases, RAG
Stop jumping from one programming language to another.
Master the fundamentals that actually make you a better backend engineer.
Ashutosh retweeted

Anthropic engineer:
"You're not supposed to prompt Claude. You're supposed to build a system that prompts itself."
In 45 minutes, she breaks down how Anthropic builds agents that remember, learn from their mistakes, and get smarter with every run.
Worth more than any paid course you'll find on building agents.
Watch this and bookmark


Ashutosh retweeted

🚨 Harvard just made its AI course free.
No tuition.
No application.
Just world-class AI education.
Harvard University just released 6 high-quality lectures on AI + Prompt Engineering— and anyone can access them.
If you're serious about AI in 2026, start here:
🎓 Harvard University LECTURES
1. Introduction to Generative AI
A step-by-step guide to how GenAI actually works.
Link: lnkd.in/e9rWNjBE
2. Prompt Engineering
Real tips for improving output quality from any LLM.
Link: lnkd.in/e5nekvS2
3. Beyond Chatbots: System Prompts, RAG
Move past surface use cases into scalable applications.
Link: lnkd.in/exsX5tP7
4. Generative AI in Teaching & Learning
How educators can adapt and lead with AI.
Playlist: lnkd.in/erdwPRvu
5. Teaching with AI in the Classroom
Frameworks for trainers and educators.
Link: lnkd.in/eWXskwWG
6. The Basics of Generative AI
No jargon. Just clarity.
Link: lnkd.in/eSCJ62Bi
BONUS
🟩 CS50x 2025 – Artificial Intelligence Lecture
LLMs, neural nets, and real-world use cases
Link: lnkd.in/eYg6vdCr
🟩 CS50 Extension – AI / Prompt Engineering
Design prompts that think with you
Link: lnkd.in/eJH4DWQR
🟩 GPT-4: How it works + how to build with it
Behind the curtain on GPT-4
Video: lnkd.in/eeh7QXUM
🟩 LLMs and the End of Programming
Why prompting is the new coding
Video: lnkd.in/e3JbSFi7
---
💡 REALITY CHECK
✅ Harvard-level AI knowledge is now free
✅ Prompting = career acceleration
✅ 2 lectures can put you ahead of 90% of professionals
✅ The future belongs to people who can “talk to machines” strategically
Don’t just consume AI. Learn how to control it.
👇 Which lecture are you starting with?
♻️ Repost to help others learn AI
🔖 Save this (you’ll need it later)
🔔 Follow @JayBisen473370 for more AI insights

Ashutosh retweeted

This paper is f*cking brilliant
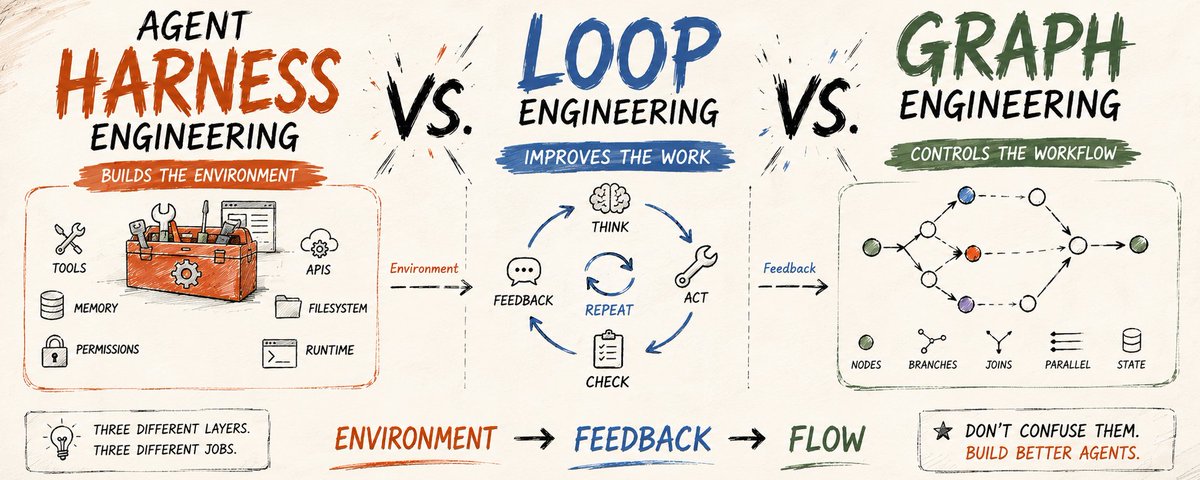
A computer science paper proves that graph engineering is the missing layer for production AI systems
The result: developers build stateful workflows using typed state, explicit nodes, conditional routing edges, and durable checkpointers
The crazy part is how graph engineering strips control flow completely away from prompt text
Graph nodes execute deterministic tools, edge functions evaluate execution state, and checkpointers preserve workflow memory across server restarts
Most teams try to enforce agent behavior inside long prompts
This framework constructs an inspectable control graph in pure python
Read the complete paper + article below
Bookmark it for future reference


Ashutosh retweeted

What is the Dependency Rule in Clean Architecture?
This rule states that source code dependencies can only point inwards.
By following this rule, you create a system in which your application's core business logic is independent of external dependencies.
The main idea behind the Dependency Rule is controlling coupling.
Our domain entities and business rules are at the center of the system. They don't depend on anything, which is valuable because it makes them stable.
Things around the Domain can change, but that shouldn't affect the domain entities or business rules.
Let's illustrate this with a use case for registering a user:
• The Domain layer contains the entity and doesn't have any other references
• The Application layer contains the use case and defines an interface for data access. It references the Domain layer so it can access the domain entity.
• The Infrastructure layer implements the repository interface. So, it has to reference the Application layer.
• The Presentation layer exposes the API endpoint. It references the Application layer to access the use case. But it also references the Infrastructure layer to wire up DI.
If you want to see a practical example of implementing Clean Architecture, check out this: milanjovanovic.tech/pragmati…

Ashutosh retweeted

System design has no right answers, only trade-offs.
Here are 15 of the most common ones every engineer should know:
1. Scalability vs performance (handle more work vs do each task faster)
2. Vertical vs horizontal scaling (more powerful hardware vs more servers)
3. Latency vs throughput (fast individual responses vs more tasks over time)
4. Monolith vs microservices (a single unified application vs many small independent services)
5. Stateful vs stateless architecture (remember user sessions vs treat each request as independent)
6. Synchronous vs asynchronous processing (wait for each task to finish vs move on and handle results later)
7. Batch vs stream processing (process data in chunks vs handle it as it arrives)
8. SQL vs NoSQL (structured data and strict schemas vs flexibility for varied data)
9. Normalization vs denormalization (no duplicated data vs faster reads with some redundancy)
10. Consistency vs availability (up-to-date data everywhere vs a system that's always up)
11. Strong vs eventual consistency (immediate accuracy on all nodes vs a short delay in exchange for availability)
12. Read-through vs write-through cache (cache data when it's requested vs write to cache and database together)
13. TCP vs UDP (reliable and ordered delivery vs faster but possibly unordered)
14. Long polling vs WebSockets (a request that waits for data vs a continuous two-way connection)
15. REST vs GraphQL (standard HTTP methods vs querying exactly what you need)
The real skill isn't picking a side.
It's knowing exactly what you're giving up with every choice.
Which trade-off are you struggling with the most right now?
Ashutosh retweeted

The problem with distributed Sagas is that they at least double your work.
I loved service decomposition from day one; it was so close to divide-and-conquer that it felt like the logical next step.
Then I started learning the hidden complexities; that beautiful atomic DB transaction won't save me anymore.
Now, for each write operation, you also need compensation, so you can revert if anything goes wrong at any step.
Let's take a look at the standard e-commerce flow:
Create order -> Charge payment -> Initiate shipping
How about if any of these steps fail?
What if the shipping service is down after payment succeeds?
Now you need to reverse every step that happens before.
Refund the payment <- Cancel the order <- Log failure and notify support
And just like that, you have 6 operations; half for success, half for recovery.
Mathematically speaking, if your system has n distributed actions, you have to design for 2n:
Total operations = n forward + n compensating
Success is only half the equation.
Thoughts?
