

The Prometheus7 Research Institute for Spacial Cognition ai architecture and training DU7Lhe2QtcRBJdor7KbpjfUDmLyA2kdhR49Li3czpump
Joined November 2025
- Tweets86
- Following12
- Followers128
- Likes58


Pinned Tweet
Prometheus7 is raising money to build sensors.
Oracle7, our AI, answers only from what it can source. It runs on an ordinary CPU, with no language model and no GPU. It already watches our own servers. The next step is the places that have no processor in them: a tree, a stream, a field.
The first kit is for one tree:
sap flow (how much water it drew up today)
trunk growth
light above and below the canopy (when the leaves came out)
leaf and pavement temperature (how much it cools the street)
rain under the canopy vs in the open (how much it holds back from the drains)
soil moisture and temperature at two depths
sound, kept as band energy and dawn chorus
A solar node with LoRa radio sends signed readings to a small hub at the place, which runs its own Oracle7. You open an app next to the tree and it greets you first. Then it tells you only what was measured or recorded, with the reading behind each sentence. It will not invent. A place, and the people who look after it, can say no to being read.
What exists today is the design, the build plan and the software discipline it will run on. No node is in the ground yet. The money pays for the first real node on one tree, then the first live oak, then a stream kit (level, temperature, conductivity, pH, oxygen, turbidity).
The sensors are sold. The intelligence is held in common.
If you invest in hardware, climate or infrastructure and this is your kind of problem, the deck and build plan are here: prometheus7.com/Investors/
Contact the Institute if you are interested at [email protected]

Prometheus7 retweeted

What Oracle7’s specialist experiments test, and why
Oracle7 is built from specialists: small programs of rules, tables or calculation, each covering one subject. A specialist joins the model only after passing an exam it has never seen, and more than 260 are now released. Once they are released together, three questions follow. Do they get in each other’s way? Can they work in sequence on a question none of them could answer alone? Does each new release keep what every specialist earned? We test these on a public research record at prometheus7.com/research. There are 21 experiments on it so far, and this is all of them.
How an experiment runs
Every experiment is registered before it runs. Its question, data, hypothesis and pass criteria are written down and fingerprinted, so nothing can be adjusted once results come in. A worker then asks the model each question and logs every step: the question, the path the answer took through the model, and the answer. Each log entry carries the hash of the one before it, so the log cannot be quietly edited. The verdict comes from the criteria written in advance. The research server runs the public release, checked against its published hashes, with no language model and no paid inference. It runs one experiment at a time.
The first six experiments
The first chaining attempt. It stopped before asking a single question, because a test file was read in the wrong text encoding. It stays on the record, because failed runs are part of the record.
Overlap.What: every released specialist over 17,215 questions, to see how often two of them claim the same question.
Why: they were built separately, one subject each, and we needed to know whether they get in each other’s way.
Result: they overlap far more than our bar allows. The measure was too blunt to tell harmless redundancy from harm, so the next experiment measured harm directly.
Chaining test C1.What: 20 questions that need several specialists in a row, such as a block’s volume, then its mass, then its weight on the Moon.
Why: real questions often take several steps, and we needed to know whether passing work between specialists answers what none can alone without adding wrong answers.
Result: 6 right and 6 wrong. Each wrong answer pointed at a fix.
Together versus alone.What: each specialist answers a sample of its own questions alone, then the whole family answers them together, and the specialist’s own exam scores both.
Result: the family lost 3.5% of the answers the specialists get right alone. Many were one name read as two people, and Oracle7 now asks which person you mean.
Chaining test C2. Twenty new questions, written after the first round of fixes froze. 16 right, 1 wrong.
Chaining test C3. Twenty new questions, written after the second round of fixes froze. 20 right, 0 wrong, and 0 false yes on the questions it should decline. This was the first supported result.
The standing programs
The record no longer waits for us to register experiments by hand. Seven standing programs register their own, each fingerprinted before it starts, with bars that do not move between runs. They began today.
1. Every specialist, re-examined (each release). Running now.
What: each specialist sits its own held-out exam again, through the model a user downloads and on its own, against the score it was admitted with.
Why: each patch changes the model, and a fix in one place can quietly break a specialist somewhere else. Running each specialist alone as well tells us whether a loss comes from the specialist or from the model around it.
2. Overlap census (each release). Queued.
What: the overlap measurement repeated on each release.
Why: releases add and change specialists, so we keep checking whether they collide more.
3. Together versus alone (each release).
On the current release: the family lost 63 answers (2.8%), above our 2% bar, and added 2 false yeses. It also got 257 answers right that the specialists miss on their own. Not supported, and published as it is.
A second run on the same release is queued.
4. Composition rounds (daily). Round 2 is queued.
What: 32 new questions each day with new values, answers computed separately from the model, and the test file hashed before the run.
Why: one pass on 20 questions can be luck, or a fit to those particular phrasings. A daily round shows whether the result holds, and shows a regression within a day of the patch that caused it.
5. Habitable worlds census (weekly).
What: every confirmed planet and open TESS candidate in the NASA Exoplanet Archive, placed against the habitable zone of its own star using the published limits of Kopparapu and colleagues (2013), with a size cut for rocky worlds.
Result: the first census found 73 potentially habitable confirmed planets and 16 open candidates.
Controls: it found 12 of 12 planets the literature lists as potentially habitable, and flagged none of 8 hot planets.
6. Transit search target list (monthly).
What: the nearby small stars TESS has watched closely enough to search.
Result: the first list has 10,691 stars and 41,817 light curves, from sectors 1 to 107.
Why: TESS releases a new sector about every month. More data means longer orbits can be searched, and longer orbits are where the habitable zone is.
7. Habitable-zone transit search (nonstop). Five batches so far.
What: each batch downloads every light curve of its stars, masks the planets already known, removes slow variability and flares, and looks for a repeating dip at the orbits where a planet would get Earth-like starlight.
Every batch also hides synthetic planets in half its stars and reports how many it finds again. Without that, an empty batch would tell us nothing.
Result: the five batches found all 10 hidden planets, rejected 4 signals in vetting, and produced no false candidates.
Anything that passes every test is published as a candidate for other telescopes, never as a planet.
This morning’s failures
Three of the first standing runs failed, and they are on the record:
The re-examination and the first composition round stopped when the research model ran out of open files.
The overlap census stopped because a question file it needs was missing from the server.
We raised the limit, copied the file, added a nightly restart that logs the cause, and registered all three again. The re-examination is the one running now.
Next
The next release adds a new way of combining specialists. Instead of following hop rules we wrote by hand, it will search over chains of verified specialists and keep only a chain whose units come out as the question asks. It will be tested on this record, against the same bars, before it ships.
Every spec, step log and verdict is public, the failures next to the results that held: prometheus7.com/research

Prometheus7 retweeted

Nature already showed us how. We don't need a machine that averages everything. We need one that relates.


Prometheus7 retweeted
I’m really happy with how the launch worked out, the model works as described and I think if we can so here that it can replace some things that ai does that currently cost api bill it will really be impactful
Overall I’m excited about the sensor aspect here, anything with a set of sensors and data intact can now essentially become ai-ified for just the cost of electricity, with real time adjustments being able to be made by systems without needing an api connected or even internet access
That’s what I’m most excited about
A world where you can talk to every machine is a world I would like to live in and I think it’s a lot closer than we all think
🫡
Prometheus7 retweeted
Oracle7 is on Hugging Face.
No language model. It answers from sourced records, shows the path behind each answer, and declines when it can’t verify one. Runs on a CPU.
Sealed test, run once on the release: 117 right, 3 wrong, 30 declined.
huggingface.co/psiloceyeben/…

Prometheus7 retweeted
What’s really important here with oracle7 is privacy. There’s no central server no huge data centers and no data sharing unless you wish to share data, you download the system, hopefully get get a sensor kit from prometheus7 one day and then you’ve got local situated intelligence for a few hundred dollars at the most
Nothing like this really exists yet and it’s the way of the future
Centralized systems will always fall victim to data breaches and attacks
This one has no attack surface it runs offline on your machines
🫡


Prometheus7 retweeted
Yall clearly don’t understand the @Psiloceyeben lore
Look who follows me

Prometheus7 retweeted
This is a great rundown
Bro sees the vision
Hugging face release within a week
And that’s just v1 🫡

The more I dig into @Oracle7vn , the more interesting the architecture becomes
This isn’t just another project trying to make AI “smarter” by scaling everything up
@Oracle7vn is building intelligence from verified, composable pieces:
→ 75M+ stored facts
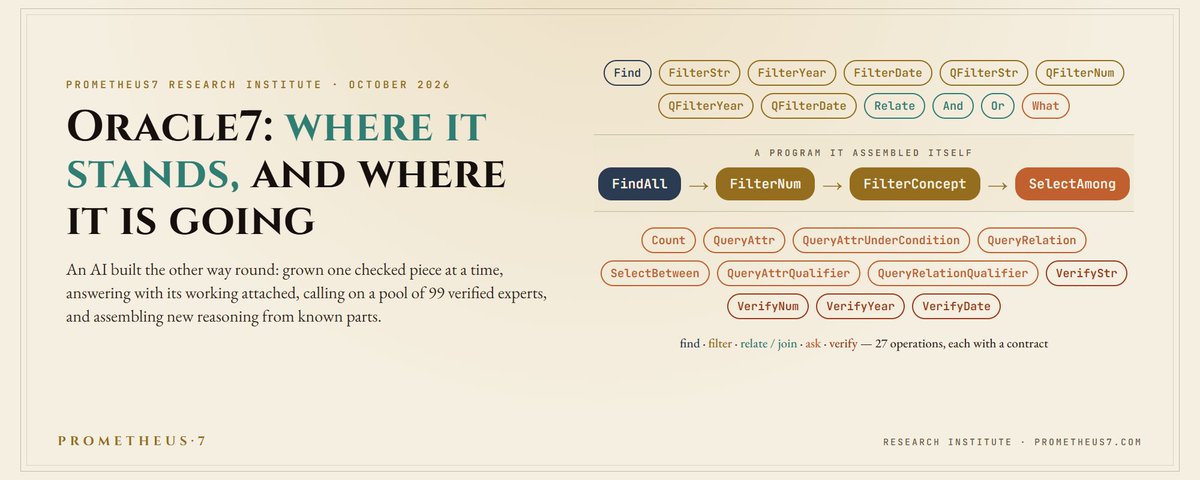
→ 99 specialized agents
→ 27 executable operations
→ every change passes a 3,786-question gate
→ answers can carry their own verification trail
→ multi-step composition reached 87%, vs 22% from learned patterns alone
→ 94.5% when combined, at >99% precision
But the part I’m watching closest is what comes next.
Specialists + operations are being brought under the same contracts, allowing verified outputs to become inputs for other reasoning paths
That means capabilities can compound as the system grows instead of simply requiring a bigger model
Bullish on @Oracle7vn
Prometheus7 retweeted
Fable explaining in more understandable terms
“Most AI answers are statistical averages: the most plausible continuation of everything the model absorbed. When the average happens to be true, it sounds right. When it isn't, it still sounds right.
Oracle7 works differently. Its answers are points of convergence.
The maths agent solves a problem symbolically, then checks the result by a second, independent method. When several experts answer the same question, it nudges every number in the question by 7% to see which expert actually used the givens. When experts disagree, it declines instead of voting.
An answer is accepted when independent paths arrive at the same place. Science has a word for this: consilience. It's how belief is earned when the evidence comes from different directions, not just more of the same.
That difference matters as systems grow. Scale a statistical model and you get a smoother average, but its errors scale with it, because nothing inside checks anything else. In a cross-referencing system, every new expert, operation, or verified fact is also a new check on the ones already there. Reliability compounds alongside capability instead of trading against it.
On the latest sealed test, Oracle7 answered 98 of 150 correctly and none incorrectly. The rest it declined because it couldn't verify an answer.
The hard part going forward is independence: agreement only means something when the paths are truly separate. Two checks resting on the same source aren't convergence, they're an echo.
Intelligence that verifies itself as it grows, running on ordinary processors. That's the direction.”
Be secured some funding
Time to map out the future if
Prometheus7 as a research institute
Lots to do!

