

MLE@ Georgetown. Part-time researcher, CoreAI Lab Columbia University. Interested in continual learning, mid-training post training interplay and world models.
San Francisco, CA
Joined March 2015
- Tweets26
- Following122
- Followers15
- Likes125


Saw quite a few papers on knowledge distillation @COLM. Been thinking a lot at about why on-policy distillation works so horribly in smalller scales. More coming soon.

I’ll be presenting my paper @COLM_conf this week on Thursday on Autoresearch agents:
📍Franciscan C, 11am-1 pm
I’ll be here all week: looking forward to chatting about post-training, RLVR, and better ways to assign process rewards. DM if you wanna chat or grab coffee!

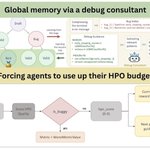
Agents can now automate large parts of the ML training pipeline, including code generation, debugging, and model tuning. However, these autoresearch agents are often unreliable due to harness failures. We trace these failures and develop model-agnostic fixes.

MLE agents also skip core ML practice. Hyper-parameter tuning is often absent, and while models mimic humans by performing EDA, they ignore the results; deliberately injecting wrong EDA into the agent's memory leaves scores unchanged.


Thanks to all my co-authors! @leonau2010, @amrutha_rao_ , @tingtang222 , @KazemMeidani, @cbbruss , and @micahgoldblum
Paper 📜: arxiv.org/abs/2608.10424
Github: github.com/tingtang2/llms-fo…

