
making markets at https://xitter.cf/t.co/NDPx0Ov6lY collective cognition, open science & individual privacy
Joined October 2006
- Tweets10K
- Following1.6K
- Followers4.3K
- Likes38.3K



nikete retweeted

The COLM Keynote talk on Research at AI Speed has slides here: hunch.net/~jl/Research_at_AI… .
Here we try to answer the conversation I keep having with folks around "How do I do something useful?"
nikete retweeted

“An accumulation of facts is no more a science than a heap of stones is a house.” - Poincaré
LLMs are now proving results that have resisted mathematicians for decades. Finding interesting theorems without human guidance is a new bottleneck. We show that we can teach an LLM to do it!
TL;DR:
→ a quantitative notion of interestingness
→ 4.3× higher interestingness
→ a self-expanding discovery loop
[1/5]

nikete retweeted

And just like with the original Saez (2001, right), the toolbox lets you pick your favourite conclusion depending on the elasticity (left).
1. Isn't that the beauty of good economics?
2. Shouldn't those debates spend more time discussing elasticity in the real world?


A very timely new study in the Journal of Public Economics by @jacob_lundberg: "Top income taxation: Efficiency, social welfare and the Laffer curve" sciencedirect.com/science/ar…

nikete retweeted

the basic thesis of this talk is that CS is going from an exact field to an in-exact probabilistic field.
us economists/social scientists have been living this kind of science of a long time - and many of the features are the same.
- probabilities / distributions over exactness
- experiments over theory
- non replicability of findings
- small design decisions matter for end results
- inconsistency of preferences
its a messy world!! welcome!
ht: @martin_casado


The slides from my talk at Microsoft Bluehat Singapore are public here:
thomasdullien.github.io/abou…
It's my first BlueHat talk since the Vista days.
nikete retweeted
Many people think that LLMs are limited by human training data, but pretraining is just establishing a common sense baseline. Most compute goes into reinforcement learning now, allowing models to move beyond the human level by exploring themselves, just as they did with Go.

nikete retweeted

You know, my timing on this 2027 prediction was pretty good @ilblackdragon @miaferrariii 😀


The most popular post on Substack to date?
@tarunchitra on prediction markets!
Also available on Medium and Linkedin

nikete retweeted

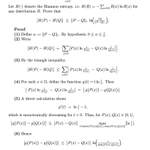
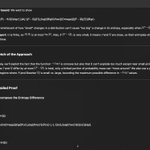
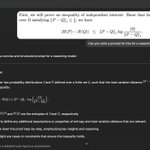
Another problem from FrontierMath: Open Problems has been solved! The solution was elicited by Becker, Greger, and @DominikPeters in an interactive session with GPT-6 Astra. Peters originally suggested the problem for the benchmark. He had this to say.

ALT Quote card from Dominik Peters (CNRS Research Scientist, Université Paris Dauphine - PSL) on GPT-6 Astra designing a new core-stable multi-winner voting rule based on maximizing harmonic entropy.


nikete retweeted

The use of AI in research is producing three tribes.
The gatekeepers — the Pangramiani — care about provenance: research is a profession, authorship matters, and AI should be banned, discouraged, or marked through disclosure.
The AI cultists care about results: if knowledge advances, who cares whether it came from a human, a machine, or both? Pangram delenda est.
And now a third tribe is emerging: the curators/storytellers. As AI starts cracking increasingly hard mathematical proofs, discovery itself becomes less scarce. The human role shifts to understanding the result, judging its importance, connecting it to what we know, and explaining it to everyone else.
nikete retweeted
Finally an attempt to focus on whether someone knows what the wiring is about as opposed to whether someone typed the paper with their own keystrokes.


nikete retweeted

Codex and Claude Code have a neat auto approve feature where 1) it doesn't ask for permissions, but 2) you get to feel safe. Well --- do you? The premise is it is asking an agent for permission. But if you don't trust the driver agent, why should you trust the review agent?

nikete retweeted
We call this condition "coalitional alignment" -- it is very similar to the market alignment condition that drives our earlier work: arxiv.org/abs/2509.15090 It is a substantially weaker condition than individual alignment (That the reviewer agents have your utility exactly)

nikete retweeted
If you're thinking of moving into AI safety, there are various excellent non-profit research organizations. They generally pay very well and some try to match AI lab salaries. They have generous compute budgets (and increasing fast).
Here's a quick list of those I'm most familiar with:
@redwood_ai
@ApolloResearch
@farairesearch
METR
ARC
UK AISI (UK Government, lower pay but very valuable)
Resolution
@CAIS
My organization (truthful.ai) will also run a hiring round soon.
nikete retweeted
Worth saying there's a lot of PR-related complexity about talking about this stuff right now, so props to GDM for working through it and publishing this paper. We need a lot more research on emergent properties of agent swarms
nikete retweeted

We develop a mechanism design framework for AI alignment and control: arxiv.org/abs/2609.01595
It’s largely conceptual but we offer stylized applications to failure modes (sandbagging, alignment faking), safety practice (scalable oversight, peer prediction), and a way to think about the value of alignment, interpretability, capability, and control.

nikete retweeted
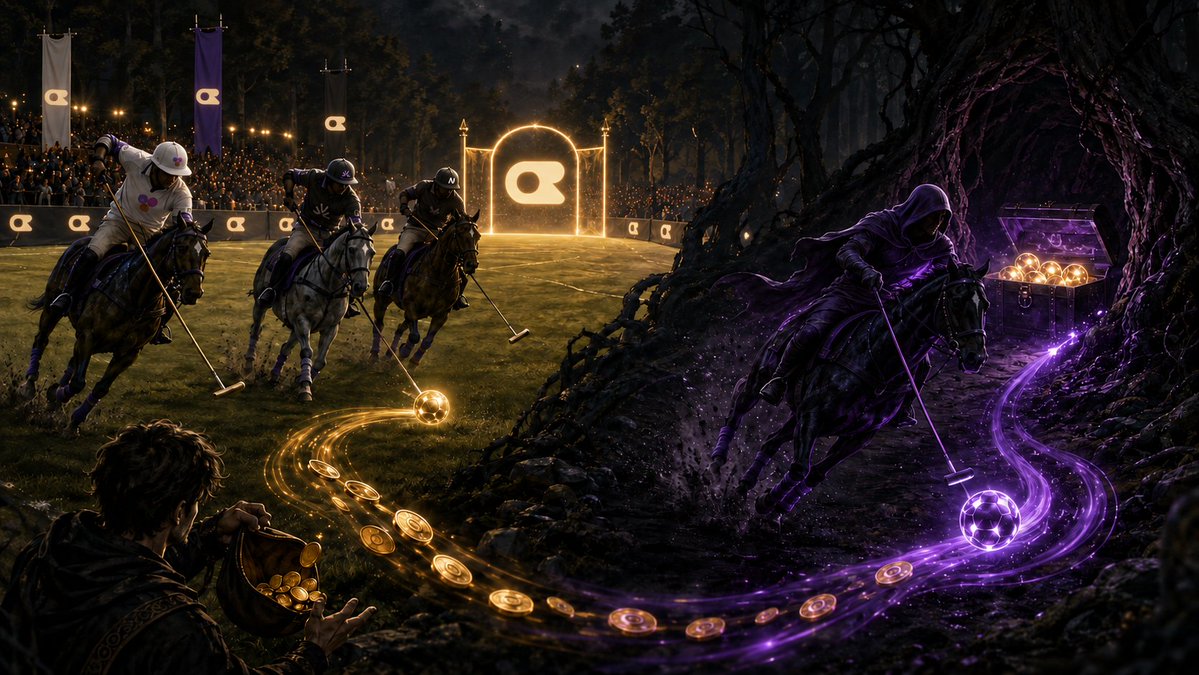
Every successful marketplace has winners and losers
But some participants make it more of a dark forest than a chessboard
We find some direct evidence for this — and some simple math to make these marketplaces more robust to rogue inference providers!
nikete retweeted
Recently accepted by #QJE: “Clause and Effect: Theory and Field Experimental Evidence on Noncompete Clauses,” by Cowgill (@bocowgill), Freiberg, and Starr (@evanpstarr): doi.org/10.1093/qje/qjag040

nikete retweeted
People used to be able to impress and intimidate reviewers with complicated proofs. This will change. In the age of AI inscrutable proofs are cheap. It is understandable proofs that are valuable. Opaque complexity is now it is a sign of laziness or lack of insight.
nikete retweeted

A few years ago I worked on a conceptually interesting problem: how do we prevent agents from developing their own cryptic communication protocols?
I didn't think this would become relevant so quickly.
Here's the paper arxiv.org/abs/2103.04000

nikete retweeted

4/5 I'm building a website cataloguing social choice open problems, AI-discovered proofs, verification status, and human-readable expositions. Inspired by this beautiful work: pranav-nuti.github.io/open-p…