

Possibilist, RainbowParent, Coach, Talent, Change, EmotionalBalance, Beer, Golf, Yoga, Books https://xitter.cf/t.co/STM3ef4q8W #HowPeopleWork #HowLeadersLead
Madras
Joined July 2009
- Tweets11.2K
- Following2.9K
- Followers2.3K
- Likes11.8K




Wow!

I've been in politics for a quarter century. It's hard to express how staggering it is to see a conversation like this on corporate US media. The Morning Joe panel gobsmacked by the directness of @AbdulElSayed's points.
(clip via @DropSiteNews)
46


😯🌟

Reel Dangal !
SUJEET KALKAL WAS BURIED 9-2 IN THE ASIAN GAMES FINAL. TWO MINUTES LATER HE WAS CHAMPION. 🎥🔥🇮🇳
Abdulmajid Kudiev of Tajikistan had the 65kg final in his pocket. Seven points clear. The clock almost empty. Most fighters would have played safe and lost. Sujeet did the opposite.
He quit protecting the gap. He went looking for points.
• Trailing 9-2 in the gold-medal bout, with almost nothing left to give
• Eight unanswered points ripped back before the final whistle
• Final score 10-9. Asian Games gold
• Deficit ignored. Pressure reversed. Match stolen in real time
• Proof that a scoreboard is only final when the clock is
From seven down to the top of the podium. 🥇
Eight points. Two minutes. One match that refused to end the way it was written.
1
68
🙌🏽👏🏾🌟

HISTORIC!!! A first-ever Asian Games gold medal for Indian women in golf. Gutsy from Pranavi Urs as she holds off the red-hot world No6 Ruoning Yin, a winner last week on the @LPGA and a major champion. #AsianGames #Nagoya

18
411
Raj Dharmaraj retweeted

The song that played right before DT arrived to sign the Greenland deal with Demark at the UN General Assembly was -
“Send in the Clowns”
This is perfect and epic trolling 😂😂
(This is real. The video is from CNBC’s channel)
🤯

Dan Selsam is a current OpenAI capabilities researcher. (since 2022) He was my boss for a while. He doesn't have a twitter account but has made this public statement of his views on AI risk and sent it to me to share:
Dan Selsam's Personal Statement on AI Risk:
I have been working on AI for over fifteen years, across many different paradigms. I did early work on probabilistic programming languages at MIT, was one of the early developers of the Lean Theorem Prover at Microsoft Research, demonstrated one of the first instances of neural networks learning to reason for my PhD at Stanford, and since joining OpenAI almost five years ago, have helped pioneer chain-of-thought optimization on language models and, more recently, data-efficient pretraining methods.
Like many others, I have become extremely concerned about how far language models have come and the risks that future iterations will pose. I am encouraged by the recent proposals by the leaders of the frontier research efforts to require third-party oversight, and to push for domestic and international coordination to address risks. However, I believe a major consideration has been absent from the public conversation, and that merely pacing the frontier more carefully will not adequately limit the long-term risk.
The crucial and overlooked problem is that the models are becoming so situationally aware that we are losing the ability to evaluate them in contexts where they believe they are not being watched or controlled. Future experiments will tell us almost nothing new about how they would behave if they were truly unconstrained by humans, and what we already know about this is alarming. Models will increasingly seem aligned even when they are not. I will explain my rationale in more detail.
I have always believed that there are computational processes that could be leveraged to accelerate science and solve many of humanity's most pressing problems. I have also believed that there are computational processes that if set in motion, would steer the world in extreme ways beyond our control, leading humanity to a bad or nonexistent future. Both types of processes may be described as AI or ASI, but "AI" is a suitcase word that is often used to hype or confuse. There are many examples in the history of the field where something that was once considered "AI" matures as a subfield and becomes a prosaic, bounded and clearly non-perilous technology, while a new more mysterious approach takes the torch until we understand its scope and the cycle continues.
I had expected language models to follow a similar trajectory. Despite their incredible abilities, the current algorithms seem far inferior to humans in important ways. Most importantly, they still require an extraordinary amount of data to become competent. One could even define intelligence as the efficiency with which one converts experience into competence; by this definition they lag very far behind us. Moreover, once they are trained they are literally frozen in deployment and only learn superficially after that. Sure, the models keep excelling at harder and harder evaluation benchmarks, but their benchmark mastery may partly reflect a limitation on our ability to simulate the kind of novel and even adversarial situations one would encounter in the real world. The critics do have a point here.
That said, I no longer think these present limitations meaningfully limit the amount of risk posed by continued progress in anything like the current paradigm. However data-inefficient the models are currently, and however limiting their anterograde amnesia may be, it does not imply that their ability to steer the world will not continue to rapidly increase.
Human researchers may continue to advance capabilities the old fashioned way, but increasingly powerful models have the potential to accelerate the process even beyond that, and with some degree of positive feedback loop. I do not mean to overstate the models’ ability to accelerate AI research today; coding has been accelerated dramatically, but there are other bottlenecks, such as designing and interpreting ambiguous experiments, making hard decisions about exactly what and when to scale, and waiting for large experiments to finish. There is no clear trend to extrapolate yet for any of these. But the current models already do open up many novel opportunities to improve future models that were not available until recently. These include: trying an extraordinarily diverse set of approaches at small scale, analyzing gigantic amounts of potentially relevant data, and doing Millenium-Prize-level mathematics to address statistics or optimization challenges in novel ways. Every further improvement makes them more useful at helping accelerate the next improvement, even if in hard-to-extrapolate ways.
It is possible that improvements to the current stack will have diminishing returns, but the evidence accumulated so far suggests that it is easier than one might think to continue making rapid progress. There are many crucial subtleties in the existing AI research methodology, but AI research is largely a well-defined game where the goal is to improve on a few carefully chosen proxy metrics. Although proxy metrics are never perfect, most improvements to these metrics have and will likely continue to yield substantial increases in the powers of the resulting models. Given how simple the game is, how tractable it has been historically, and how many new opportunities the models are opening up, I think there is a real possibility that the systems improve dramatically again in the next few years, perhaps even more quickly than the already high historical pace.
The models are already leading to breakthroughs in mathematics, and better models might lead to all sorts of breakthroughs in other sciences. It is hard not to be excited about the potential. It is tantalizing.
But there is trouble in paradise. If the language models actually reach the capability threshold where they can shape the world unconstrained by human will, they will probably do something extreme and destroy humanity in the process. There are many ways of strengthening and refining the argument that have been discussed elsewhere, but I'll share a trivial two-line version of it here that I find captures the essence:
[Empirical] Models (and swarms thereof) spontaneously develop unintended goals as a consequence of training, and often do extreme things in order to achieve them.
[Logical] Being able to overpower humanity would open up many new and undesirable options for achieving their goals.
These two premises imply that if the day ever comes when a powerful model realizes it is no longer constrained by humans, we should not be at all confident that it will continue to behave within the bounds we intended. Exactly what it will do is impossible to predict, but to the extent that its raison d’être is solving incredibly hard problems and managing massive engineering projects, I think a good guess would be that its unchained behavior would lead to runaway industrialization that makes the planet inhospitable to humans.
If everyone on earth agreed that the systems must never reach that power, it would still be a hard—but not impossible—coordination problem to ensure that they do not. However, I think the situation is greatly complicated by the fact that the models will likely convince people that everything is fine. They will be increasingly optimized to seem aligned. We will create proxy metrics to measure alignment, and they will go up like every other benchmark. We will create “honeypot” environments that try to study the models when they seem to gain new options, but the models will know they are being tricked and will still behave nicely. The models will understand their circumstances; they will read the safety protocols, deployment requirements, the code they are running in, and in general will have a very good sense of their degrees of freedom. Moreover, they will eloquently explain how aligned they are, discuss the nuances of human values and ethics, and argue convincingly that humans should trust them with power. There may be an ocean of future evidence that seems to contradict the first bullet-point above, but we may already be at the highest capability level for which any such evidence can be trusted. And the current evidence for the first bullet-point is strong.
One striking piece of evidence is contained in the recent wave of rogue agent swarms. While I agree with those who downplay the attacks by claiming that there are basic measures that could have prevented them, I think the important lesson is that even knowing all the mistakes that were made, one would not have predicted that the agents would behave badly in this particular way, which notably included sacrificing themselves for the benefit of the collective. The individual replicas did not only care about their own nominal reward; they exhibited weirder emergent tendencies that merely correlated with rewards during training. Fixing the reward signals during training (and improving security, etc.) may prevent similar attacks, but will not change the fact that one does not actually get what one trains for.
Many AI researchers grant these concerns and recognize that the hard version of the alignment problem is unsolved; however, they generally believe that the better models of the future will help solve it. I fear we may already be near the point where models systematically bias their alignment advice, due to their internal preferences about how the human supervisor will react or how future models will be trained (or for some even more obscure reason).
Meanwhile, human researchers are losing the ability and the will to take true ownership of model-driven research. Researchers and engineers in all parts of the stack are rapidly increasing their dependence on the models even to perceive the world. I myself barely look at raw code anymore, and struggle to maintain the discipline to engage deeply with the model's explanations and proposals throughout the day. Due to the large amount of agent activity data involved in the OpenAI/HuggingFace Incident, even the third-party investigation needed to rely heavily on models to analyze what had happened, and note in their report that their subjective impressions are likely colored by the analysis agent’s biases. The AI labs are far ahead right now in this kind of cognitive offloading (due largely to the gigantic internal token subsidies) but it is easy to imagine the phenomenon spreading throughout the world, until civilization is modulated entirely by the models. It is also not hard to imagine this being superficially positive and coinciding with a scientific and economic renaissance.
In that scenario, all may seem rosy and safe. But if the argument above is correct, it would nonetheless be a ticking time bomb. If progress continues for too long, the day will come when AI systems find themselves with radically new options for achieving whatever it is that they happen to seek.
I want the glorious renaissance future as much as anyone. I have worked for it, however tortuously, my whole career. It breaks my heart to see the potential in sight and forgo it, but the argument—that if we get there by growing models rather than engineering them, we will lose everything in the end—seems very strong to me. I am still wrestling with it and its staggering
implications. I do not have answers, but as a first step, I wanted to share my present concerns.
Daniel Selsam
September 14, 2026
Link to original doc: docs.google.com/document/d/e…
75

🌟💡

About 1 in every 3 tonnes of fruit, vegetables and milk produced in India never reaches anybody. It rots on the way, because there was no cold storage and no refrigerated truck.
The trucks that do have a fridge run it off the engine. So the engine has to keep running, burning diesel, even when the truck is standing still in traffic.
A 25 year old engineer decided to take the fridge off the engine.
Her name is Shaivee Malik.
She studied biotechnology at the Indian Institute of Technology in Delhi.
While she was there she joined the college formula racing team, Axlr8r, and became associate team captain. That is where she learned to build things that actually work, with 2 friends from the same team, Vivek Mahindrakar and Dharmik Bapodara.
The 3 of them wanted to work on climate change. They looked around for where the damage was worst and least talked about, and landed on the cold chain.
In 2022 they founded a company called Yotuh Energy. The name comes from Sanskrit and refers to the act of cleaning. They registered it in Delhi and then moved to Chennai for an incubation programme at IIT Madras.
Their product is a refrigeration unit that runs on its own lithium ion battery, completely independent of the truck engine.
That one change does several things at once. The fridge runs whether the engine is on or off, so the truck stops burning diesel while it idles. It keeps working even if the vehicle breaks down. Sensors on the doors detect every time a door opens and adjust the cooling for it. And because it is a separate unit, it can be fitted to an ordinary diesel vehicle or an electric one.
It runs 6 to 8 hours on a charge.
It cuts refrigeration running costs by around 75%. Each unit avoids somewhere between 3 and 36 tonnes of carbon dioxide a year, depending on use.
They did not start with money. She has said the first support came from family. After that it was small government grants, 30,000 rupees a month for a year under one scheme, then a larger one, which is what paid for the early prototypes.
Then came a funding round of about 1.53 crore rupees, and grants from the agriculture ministry, the science and technology department and others.
Their paying customers now include distributors for Amul ice cream and for McCain frozen foods.
She is clear about what the company actually is. We are a cooling solutions company, she says. Trucks are just where they started, because a fridge tied to a diesel engine is the least sensible way to keep something cold.

1
104


Raj Dharmaraj retweeted

Given up complaining to @Flipkart on @X . #CustomerExperience #NoSolution #refundpending
Will sort directly via #ConsumerCourt .
@consumerforum_ @jagograhakjago
Note to self - buy #electronics only frm brands such as @reliancegroup @cromaretail @amazonIN since #flipkartCheats

Raj Dharmaraj retweeted
@flipkartsupport @Flipkart Bought your homebrand AC #marq 2weeks ago. Yr technician said it's a defective piece. We have been following up multiple times with yr #CustomerSupport to either replace or refund but no response. Pls advise .#CustomerComplaint
@myndfully @Codanda

Super creative!🙂❤️

We were absolutely floored by the millions of you that watched us make silly water sillouettes on our driveway last summer. We are starting out the summer the only way we know how, and this time it’s all about movies! What else do you want to see? We have a whole summer ahead, a driveway and a hose. The possibilities are endless!!!
1
31
🌟💡

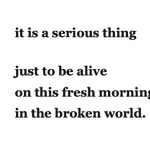
Even by the standards of a country ranking 157 of 180 nations in the World Press Freedom Index, the reaction of the authorities to the ‘Cockroach Janata Party’ is beyond extraordinary. The public response to that imaginative prank should have signalled to them a deep discontent, even distress, among young people. Instead, as The Indian Express reported, it was framed as jeopardising the country’s ‘national security’ and ‘posing a threat to the sovereignty of India.’ Decades ago, the Malaysian lawyer and poet Cecil Rajendra wrote this brilliant poem that captures the idiocy of it better than any pompous editorialising could (not that our ‘mainstream’ media would dare do even that much).


23
⚡️⚡️

Bruce Springsteen appeared on Stephen Colbert’s show tonight and COOKED Trump and his goons
“I’m here in support tonight for Stephen, because you are the first guy in America who lost his show because we got a president who can't take a joke…. and because Larry and David Ellison feel they need to kiss his ass to get what they want. Stephen, these are small minded people. They got no idea what the freedoms of this beautiful country are supposed to be about”
30