

Member of Technical Staff @a____t____g 9x hackathon winner SF
San Francisco Bay Area
Joined April 2025
- Tweets164
- Following249
- Followers103
- Likes292




Mark. retweeted

we built “let’s bump phones to exchange contacts” but for agents!
now your @instinct / @bot / @muse (whatever you use!) can make plans, negotiate deals, and get what it needs from your friends/coworkers’ assistants
it's “have your ppl (agents) talk to my ppl (agents)!” for everyone 🤝
built w/ @uncanny_guzus @ @ycombinator #MakeSomethingAgents hackathon (s/o @nemild)
on top of @stripe (agentic p2p payments) + @manufact (mcp relay server) 🙌
Who will you bump first?


Mark. retweeted

I resigned from Anthropic today. I spent the last three years doing pretraining research at both OpenAI and Anthropic. Neither company is acting responsibly. They are racing straight to self-improving superintelligence and gambling with our lives. More thoughts below.

Mark. retweeted

i'll never forget that time someone demo’ed me a language model at a hackathon in 2022 and I thought to myself "this is just GPT-3 but worse"
and it turned out to be Claude 1

Mark. retweeted
WHERE ARE YC FOUNDERS NOW?
@_javokhir and I were curious where they go "after the startup". So we ran Deep Research on ALL 11,398 founders who have ever gone through YC.
Here's what we learned: joinedanthropic dot com


Personal update: I'm taking a leave of absence from YC to join Anthropic. I'll be working with @NotTomBrown on the compute team.
Powerful AI has the potential to improve the life of every human on earth and, as we enter the early stages of recursive self-improvement, availability of compute becomes one of the most important issues to solve.
I'm excited to get started 🚀

Mark. retweeted
Introducing Straude: Strava for Claude Code 🏃♂️
One command logs your token output, spend, streaks. Sync to your straude dot com profile and compare your pace to the top AI builders worldwide.
Available now: ~npx straude
Check it out & upvote us on Product Hunt (#10) ↓

Mark. retweeted
Introducing The Prometheus List: top companies with unlimited token budgets you should work at 🔥
It’s 2026, an unlimited token budget matters more than unlimited PTO.
If your manager is asking you to "chill out with the agents" or "just use Sonnet," it’s time to look for a new gig.
feat. @tryramp @NotionHQ @vercel @resend @Railway @browserbase @genspark_ai @ScoutAI_ @ExtendHQ & more
straude dot com/token-rich




Mark. retweeted

Introducing Claude Opus 4.6. Our smartest model got an upgrade.
Opus 4.6 plans more carefully, sustains agentic tasks for longer, operates reliably in massive codebases, and catches its own mistakes.
It’s also our first Opus-class model with 1M token context in beta.
Mark. retweeted

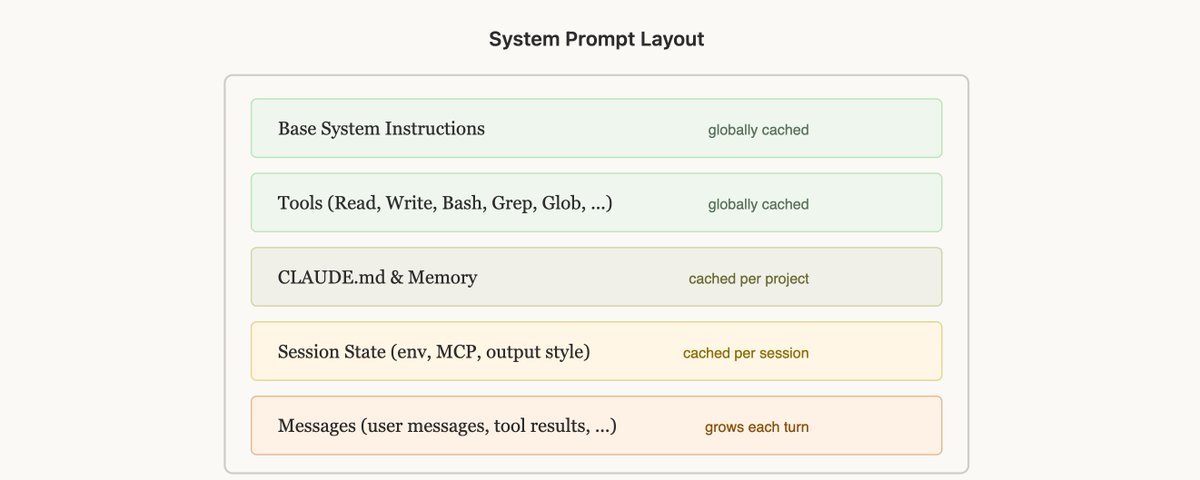
We're experimenting with ways to keep AI agents in sync with the exact framework versions in your projects. Skills, 𝙲𝙻𝙰𝚄𝙳𝙴.𝚖𝚍, and more.
But one approach scored 100% on our Next.js evals:
vercel.com/blog/agents-md-ou…

Mark. retweeted

Progressive disclosure is not reliable because LLMs are inherently lazy.
"In 56% of eval cases, the skill was never invoked. The agent had access to the documentation but didn't use it."
Vercel ran evals on Next.js 16 APIs that aren't in model training data to test whether agents could learn framework-specific knowledge through Skills vs. persistent context.
Skills are the "correct" abstraction: package domain knowledge, let the agent invoke it when needed, minimal context. The agent decides when to retrieve.
They work well WHEN the user triggers them; otherwise, LLMs just ignore them.
Vercel's benchmarking is the first experiment of this kind I've seen, and it's actually interesting.
- Baseline (no docs): 53%
- Skill (default): 53%
- Skill with explicit instructions: 79%
- AGENTS[.]md with 8KB compressed docs index: 100%
The skill approach assumes agents reliably recognize when they need external knowledge and act on it. They don't.
"You MUST invoke the skill" made agents read docs first and miss project context. "Explore project first, then invoke" performed better. Same skill, different outcomes based on prompting.
The winning approach removed the decision entirely. An 8KB compressed index embedded in AGENTS[.]md, with one instruction: "Prefer retrieval-led reasoning over pre-training-led reasoning."
Two agent design learnings:
1. Passive context beats active retrieval for foundational knowledge. Don't make the agent decide to look things up, make the index always present.
2. Compress aggressively. Vercel went from 40KB to 8KB (80% reduction) with zero performance loss. The agent needs to know where to find docs, not have full content in context.
The gap between "agent can access X" and "agent will access X" is larger than we assume.
I keep seeing similar findings across agent architectures. Kimi Swarm's orchestrator is trained specifically to avoid sequential execution. Without training, orchestrators default to serial processing, planning a list of steps and executing them one by one. It's the EASY path.
The agent defaults to the lazy path: hallucinating from training data rather than retrieving docs. Passive context removes the choice entirely; the agent doesn't decide whether to look things up; the index is already there.
We keep finding that the "smarter", more autonomous design (let the agent decide when to X) underperforms the "dumber" design (always X, or structurally enforce X).

We're experimenting with ways to keep AI agents in sync with the exact framework versions in your projects. Skills, 𝙲𝙻𝙰𝚄𝙳𝙴.𝚖𝚍, and more.
But one approach scored 100% on our Next.js evals:
vercel.com/blog/agents-md-ou…
Mark. retweeted

WOW!!! If you have semantic memory tied to your UserPromptSubmit hooks, you MUST ALSO include it in your PreToolUse hook. I promise you - it will be an absolute GAME CHANGER. It will put your efficiency levels are over 9,000 (*vegeta voice*).
How many times have you sat there, watching Claude code go through an extended workflow, just to notice it start to go down a path you just KNOW will be error filled - and subsequently take it forever to FINALLY figure it out?
The problem with relying strictly on the UserPromptSubmit hook for semantic memory injection is the workflow drift from your original prompt. The memories it injects at the initiation of your prompt will be less and less relevant to the workflow the longer the workflow is.
Claude has a beautiful thing called thinking blocks. These blocks are ripe for the picking - filled with meaning & intent - which is perfect for cosign similarly recall. Claude thinks to itself, "hmm, okay I'm going to do this because of this", then starts to engage the tool of its choice, and BOOM:
PreToolUse hook fires, takes the last 1,500 characters from the most recent thinking block from the active transcript, embeds it, pulls relevant memories from your vector database, and injects them to claude right before it starts using its tool (hooks are synchronous). This all happens in less than 500 milliseconds.
The result?
A self correcting Claude workflow.
Based on my testing thus far, this is one of the most consequential additions to my context management system I've implemented yet.
Photos: ASCII chart showing the workflow of the hook, and then two real use-cases of the mid-stream memory embedding actually being useful.
If you already have semantic memory setup, just paste this tweet and photos into Claude code and tell it to implement it for you. Then enjoy the massive increase of workflow efficiency :)


Mark. retweeted
Your timeline just exploded with indie Roblox devs making millions.
But did you know there are creators earning just as much making cute lil stickers for an Asian messaging app (LINE)?
@fahmitech wanted our own stickers, but we can't draw, so instead we made AI Stickers: Upload a selfie, get custom sticker packs ready for the LINE marketplace.
Vibecoded this morning using @cerebras @cline GLM4.7. Check it out!
Mark. retweeted

We just open sourced the code-simplifier agent we use on the Claude Code team.
Try it: claude plugin install code-simplifier
Or from within a session:
/plugin marketplace update claude-plugins-official
/plugin install code-simplifier
Ask Claude to use the code simplifier agent at the end of a long coding session, or to clean up complex PRs. Let us know what you think!

Mark. retweeted

Excited to finally come out of stealth and share what we've been building!
Introducing Autonomous — a superintelligent financial advisor at 0% advisory fees.
We just announced our $15M fundraise led by @garrytan @ @ycombinator along with some other amazing investors!
Get early access → becomeautonomous.com
We are hiring across multiple roles in NYC and SF @a____t____g
