

Founding Engineer at AiStrike, AI Agents, distributed systems, real-time pipelines, building whatever it takes to make things actually work.
Joined May 2025
- Tweets686
- Following145
- Followers141
- Likes826



Pinned Tweet
Thanks for the shoutout in the weekly update !
Excited to see my contribution live in production.
More contributions on the way! @geminicli


Here is Gemini CLI’s February 2nd weekly update for v0.28.0
- ⚙️ Extension Settings: Gemini CLI extensions now support extension settings, allowing users to be prompted on installation to set API keys, base URLs, passwords, etc.
- 🎨 Custom Themes for Extensions: Extensions can now contribute custom themes via a themes property in their gemini-extension.json. These themes are automatically discovered and listed in the /theme selection dialog.
- 🎉Gemini CLI Extensions:
- Miro: Link Gemini CLI to Miro boards to build diagrams, extract context, generate code, and track tasks using natural language.
- Apiiro: Integrate Apiiro Guardian Agent to secure code, query risks, analyze repositories, and manage findings directly within Gemini CLI
- 💻 Background Shell Commands: You can now run shell commands in the background, which is useful for long-running tasks.
- ⌨️ Undo/Redo Keybindings: Updated undo/redo keybindings to Cmd+Z/Alt+Z and Shift+Cmd+Z/Shift+Alt+Z for a more native editing experience.
- 🧩 Skill Discovery Alias: Added .agents/skills directory alias to streamline skill discovery and management.
- 📂 Directory Persistence on Resume: Fixed an issue where directories added via /dir add were not saved across sessions. Now, added directories are correctly persisted and restored when using the --resume flag.
- 📚 CLI Reference Documentation: Comprehensive improvements to CLI reference documentation covering all commands, options, and parameters.
Other Updates:
- 🆔 User Identity Display: Your authentication status, email, and tier are now displayed on startup and with the stats command.
-🛡️ Folder Trust: When opening Gemini CLI in a folder for the first time surfaces a trust dialog. This is now enabled by default.
github.com/google-gemini/gem…
🧵

The bigger your LLM context window, the more your KV cache bloats and that means more GPU memory, more cost, more pain.
this is one of the dirtiest bottlenecks in running LLMs at scale. you want long context? pay up.
Google just dropped turboquant.
turboquant compresses your KV cache down to 3 bits using two clever tricks, PolarQuant rotates vectors to compress cleanly, then QJL (a 1-bit error checker) kills any leftover bias.
early results shows 6x less memory. 8x faster attention on H100s. zero accuracy loss. zero retraining needed.
not all details are public yet, full paper drops at ICLR 2026. but what's out already is wild.
research.google/blog/turboqu…

Day 4 of agentic
AI engineering series human-in-the-loop (HITL)
Why do fully autonomous agents fail in production?
Because not every decision should be made by the model alone. irreversible actions, high stakes outputs, low confidence steps, the agent should pause, not guess.
Most devs build agents that either interrupt too much (useless) or never interrupt (dangerous). no middle ground.
The pattern is simple. define checkpoints. before destructive actions like delete, send, deploy pause and confirm. for low confidence branches surface to human. for everything else let the agent run. tools like langgraph make this clean with interrupt_before on specific nodes, stream state back to user and resume after approval.
the goal isn't a fully autonomous agent. it's an agent that knows when it's not enough.
Day 3 of agentic AI engineering series
Agent observability & tracing
your agent failed at step 12. was it a bad tool call? hallucinated output? wrong context passed? you have no idea.
That's the real problem multi-step agents are black boxes by default. no visibility into what the model decided, what tools fired, what context it had at that point.
the fix: trace every llm call, tool invocation, and decision point.
tools like langfuse, langsmith let you see the full agent run inputs, outputs, latency, token usage, where it went off track.
Day 2 of agentic AI engineering series. Context Compacting.
Your agent works great for 5 steps. by step 20 it's hallucinating, repeating itself, forgetting what it already did.
Not a model problem. it's a context problem.
as conversation grows, old noise drowns out what actually matters. the model attends to everything including junk.
context compacting = summarize + prune the history periodically. keep the signal, drop the noise. agent stays sharp across 100+ steps.
Day 1 of agentic AI engineering series context engineering
Most agent systems fail not because the model is dumb, but because we don’t trust it enough too many guardrails, conflicting instructions, over-specified prompts you’re not guiding the agent, you’re confusing it give the model clean context, clear objective, right tools. that’s it.
The model knows what to do. your job is to not get in the way.
Krishna retweeted

Do not keep looking for beginner-friendly content, because for harder topics, there is none. Also, they often optimize for feeling smart rather than becoming smart.
Try to build a habit of reading, watching, and absorbing detailed information and concepts. This will not only help you move away from being spoon-fed, but it will also make you better at abstract thinking.
I believe abstract thinking will become crucial in the coming decade, as the world shifts toward solving more complex and ambiguous problems that are not easily visualized and comprehended.
We are seeing an early sign of the drift with you-know-what. Extrapolating from here, I would say it is going to be increasingly vital for us to think beyond the obvious.
The people who will navigate that well are not the ones who found the best beginner guide. They will be the ones who learned to sit with the hard stuff until it made sense.
google says ai writes 30% of their code. microsoft says similar. the question isn't whether ai can write code it's who's responsible when that code fails at 3am. spoiler: still you. understanding the code you didn't write is the new core skill.
kafka 4.0 share groups (kafka queues) change the game - record-level distribution instead of partition assignment. when you need parallelism but not ordering, you can scale consumers without provisioning 100+ partitions. spring kafka 4.0 supports it with @kafkalistener and concurrency built-in.
spring.io/blog/2025/10/14/in…

Ordered food on Swiggy (usually 20 min delivery). After ~50 mins I called the delivery guy, he said he had an accident. Swiggy’s bot kept telling me he’s at the restaurant and my order will arrive in 9 minutes.
Tried cancelling → ₹0 refund. After pushing for human support they sent another partner. Then the restaurant called and said the delivery partner was literally eating my food.
Almost 2 hours wasted for this. What is going on @Swiggy
Starting a daily series on agentic AI engineering
Not the basic stuff (tool calling, RAG, you know the drill)
Real concepts:
→ Building reliable agents
→ Context engineering & compacting
→ Token-efficient context awareness
→ Streaming done right
→ Giving agents the right tools
Code drops on GitHub every day.
The level of commitment I have for a website is directly tied to which email I use.
If I’m using my primary Gmail, we’re in a serious relationship. If I’m using one of my 10 'random' accounts, I’m just here for the free trial and we are never speaking again.
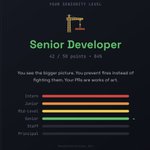
Spent some minutes on @Lovable building "How Senior Are You?", a fun quiz to test your dev seniority level
Spoiler: the results hit different 👀
Give it a try and share your results with me! Curious to see where everyone lands
howseniorareyou.lovable.app


Filesystem + bash are underrated agent superpowers. When an API returns 50K JSON records, don't dump it in context - write to file, pass the path. Let the agent jq, grep, or awk what it needs. LLMs know shell commands better than parsing giant blobs. Tools > prompts.
Every time I open an app on my Mac, I get a storage warning. How can I fix this? Is there an app that can help?

Neo4j isn’t just “SQL with relationships” - it’s a fundamentally different way of thinking about data. When your Postgres query has 5 JOINs to answer “friends of friends who bought product X,” that’s a sign you’re fighting your database.
Graph databases shine where relationships ARE the data: fraud detection rings, recommendation engines, knowledge graphs, IAM systems. Traversing 3 hops in Neo4j is O(1) per hop - no temp tables, no Cartesian products.
Key lessons from production:
> Model for queries, not entities. Your traversal patterns define the schema
> Index node properties you filter, not relationships (that’s native graph traversal)
> Page cache = your dataset size, heap = 2-4GB. Most teams get this backwards
> EXPLAIN/PROFILE every query. CardinalityEstimate mismatches mean stale stats
> Use APOC carefully - procedures like apoc.periodic.iterate are memory-safe for bulk ops
Cypher is expressive but can bite you. OPTIONAL MATCH with large fan-outs? Memory explosion. Cartesian products from multiple MATCHes? Query death. Always profile before production.
If your SQL has 5 JOINs to answer “find friends of friends who like pizza,” you’re using the wrong database. Graph databases like Neo4j traverse relationships in constant time - no JOINs, no temp tables. Social networks, recommendation engines, fraud detection? Graphs win every time.