

Working on data processing and analysis infrastructure for ML @ Google.
California, USA
Joined September 2015
- Tweets145
- Following0
- Followers164
- Likes143
Jiri Simsa retweeted

Today at @MLSysConf, @MichaelKuchnik will present Plumber, our tool for diagnosing and removing performance bottlenecks in ML input data pipelines.
Joint work with @jsimsa, @GeorgeAmvrosia2 and Virginia Smith.
Paper: proceedings.mlsys.org/paper/…
If you are interested in advancing infrastructure that provides large scale data analysis and processing for ML workloads across Google, my team is hiring:
linkedin.com/jobs/view/29053…
Jiri Simsa retweeted
Our VLDB’21 talk about tf.data, a ML data processing framework, is now online: youtu.be/VsOvy3eGK8Y
More details in our paper: vldb.org/pvldb/vol14/p2945-k…
It has been great to collaborate on this work with @mrry @jsimsa & Ihor Indyk!
Jiri Simsa retweeted

Five years ago, we open sourced @TensorFlow, our machine learning framework that's now the most popular machine learning library in the world. 🌎 To celebrate, we’re sharing few interactive demos and tutorials you can try, no experience required → goo.gle/3nz22Xh
Awesome to see the success of TensorFlow and JAX, both using tf.data to ingest data fast enough to train to convergence in under 30 seconds!

Very excited to see the MLPerf 0.7 results released today, where Google TPUs set records in six of the eight benchmarks!
We need bigger benchmarks, because we can now train the ResNet-50, BERT, Transformer, & SSD benchmarks each in under 30 seconds.
cloud.google.com/blog/produc…

Jiri Simsa retweeted

In 2016, when I was working on machine translation, it took me more than a week on a multi-GPU machine to train a competitive system on WMT English-German.
Today, JAX on a TPU v3 supercomputer can train a better model on the same data in 16 seconds! cloud.google.com/blog/produc…

Jiri Simsa retweeted

👉 tf.data supports *any* machine learning framework (JAX, @TensorFlow, PyTorch, more!), and is a great way to speed up your data input pipelines.
Be sure to try out our new features for tf.data, available in TF 2.3: github.com/tensorflow/tensor…

1. Start with TF Data
2. Enable non-deterministic ordering
3. Cache data
4. Turn on experimental optimizations
5. Autotune parameter values
--> >10% performance improvement! 🤯
#EuroPython


Jiri Simsa retweeted

🔍Inside TensorFlow: tf.data + tf.distribute
In this presentation, Jiri Simsa showcases best practices. You’ll learn about the input pipeline, parallel extraction, distributed training, and more.
Watch here → goo.gle/2wYGEG7

Jiri Simsa retweeted

If your dataset is small, use an in-memory cache:
ds = ds.cache()
If large, create an on-disk cache:
ds = ds.cache("my_file")
Afterwards, you can call ds.batch() and ds.shuffle() as always.
Complete example: tensorflow.org/tutorials/loa…

Jiri Simsa retweeted

Speaker spotlight - @jsimsa, tech lead of the tf.data project & software engineer at Google, to present on tf.data the recommended API for creating #TensorFlow input pipelines @ #DataOrchestrationSummit. RSVP: lnkd.in/d-M6cRz
#opensource

Presented tf.data and tf.distribute at #GoogleMLSummit in Tokyo! Stay tuned for a recording.



Thank you for the kind words!

Loving the "Inside Tensorflow" series. The latest release on the TF data API highlights just how much effort the @TensorFlow team has invested in making highly performant pipelines accessible to the end user. Major kudos. 👏👏👏 @mrry @jsimsa et al
youtube.com/watch?v=kVEOCfBy…

Jiri Simsa retweeted

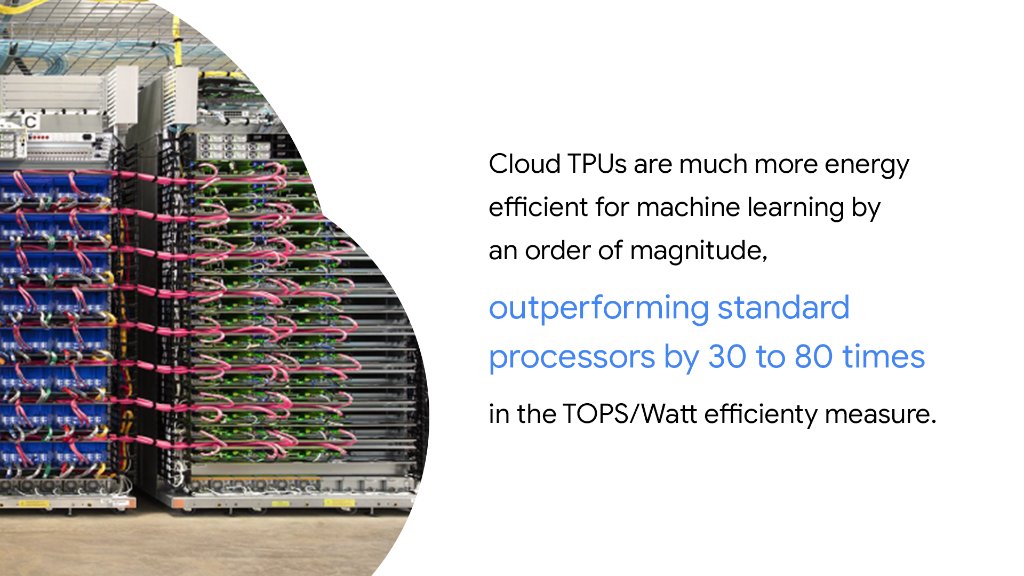
Not only are TPUs fast for doing machine learning, but they are also more energy efficient than alternative platforms, so you can feel great as you train that language model on scientific articles about climate change. xitter.cf/GCPcloud/status/988054…

Our Cloud TPUs are designed with energy efficiency in mind, specifically to accelerate deep learning workloads at higher teraflops per watt compared to general purpose processors → blog.google/topics/google-cl… #EarthDay
Jiri Simsa retweeted

Today in #CloudTPU announcements: (1) @TensorFlow 1.8 now available with a slew of perf improvements (2.7k to 3.2k images/sec on ResNet-50, aka 12.5 hours is now 9 hours to fully train), and (2) we have opened up a new zone (us-central1-b) for HA & load balancing.
Jiri Simsa retweeted

Our latest DAWNBench results are live: 8h52m for @TensorFlow to train ResNet-50 on ImageNet on a single @GCPcloud TPU (<$60), and just 30 minutes on half a TPU pod!
dawn.cs.stanford.edu/benchma…
Jiri Simsa retweeted
We just posted new DAWNBench results for ImageNet classification training time and cost using Google Cloud TPUs+AmoebaNet (architecture learned via evolutionary search). You can train a model to 93% top-5 accuracy in <7.5 hours for <$50.
Results: dawn.cs.stanford.edu/benchma…

Jiri Simsa retweeted
Cloud TPUs (now in !!open!! beta) are a leap forward in price & performance for Machine Learning. (See dawn.cs.stanford.edu/benchma… for end-to-end benchmarks.) Spin one up at console.cloud.google.com/com… today!
Jiri Simsa retweeted

If you want to find out more about tf.data performance after my talk at #TFDevSummit, check out this awesome guide by @jsimsa and @bsaeta! xitter.cf/math_rachel/status/979… – at Mountain View, CA

Jiri Simsa retweeted
I'll be speaking about tf.data at 10am PDT. Hope you can tune in to the livestream!
tensorflow.org/dev-summit/ xitter.cf/TensorFlow/status/9797…

Hundreds of researchers, developers & TensorFlow enthusiasts arrive in Mountain View CA for the #TFDevSummit! We kick things off live in ~45 minutes.
You can find the event livestream here → goo.gl/sxFLxD
pscp.tv/TensorFlow/1djGXdZEq…
