PhD student @CarnegieMellon and @MozillaAI, making things for thinking with // once upon a time @GoogleAI @Waymo @BKCHarvard, cs+phil @UChicago

pittsburgh
Joined October 2014
Ever wish you could read multiple articles at once? easily grasp consensus & disagreement in a cluster of documents? or get updated info as you read? Excited to share NewsSense, a tool that offers “reference-free verification” (soon at #EMNLP2023): arxiv.org/abs/2310.04592 1/🧵
3
12
1
61
15,114
Besides a brief stint with microworlds, I started learning to code at 12 by making scratch games -- and I still think about programming as building a world & its rules.
I still see the Scratch “visual programming” environment positioned as an introductory path to programming for kids, but unlike game modding, I have never heard a “success story”, where someone credits their early experience with Scratch as key to a fulfilling career. Anyone?
1
1
170
I think tech experiences that teach you to think in new ways (and are accessible at an early age) are going to be especially important if society starts to converge on a universal monolithic AI UX
31
Jeremiah Milbauer retweeted
🎉 Our paper “LLM Probability Concentration: How Alignment Shrinks the Generative Horizon” is accepted by TMLR! The short version: 📉 LLM generation usually self-narrows ✂️ Alignment compresses the horizon further ⚡ Unexpected context can reopen it locally We study these dynamics with Branching Factor (BF)—exponentiated length-averaged entropy, interpreted as the effective number of plausible next steps. Direct evidence first: across tasks, BF typically declines as more tokens are generated, in both base and aligned models. Then we intervene. Replacing the model’s own prefix with equally long random tokens makes BF jump; continued autoregressive generation narrows it again. Self-narrowing is therefore a robust aggregate tendency, not a monotonic token-wise law—and not an artifact caused only by alignment. Alignment is a separate force: it lowers BF by 2–5× overall and up to ~10× at early positions. Reasoning models also remain lower-BF than direct-answer aligned models at matched output lengths, so their concentration is not merely because they generate longer. Most importantly, BF can rise in a structured setting. In synthetic agentic tasks, we hold the task, environment state, and current plan fixed, then change only the next environment feedback. A plan-invalidating surprise raises BF relative to normal progress; continued generation subsequently smooths the local spike. So the dynamics are not simply “entropy collapse.” The model narrows, surprise can reopen its consideration set, and self-conditioning narrows it again. Practical implication: when exploration matters, branch early—or introduce genuinely NEW information before the model has fully committed. 🧵 Learn more from our Branching Factor v1.1 tweet: xitter.cf/chrome1996/statu…
BranchingFactor v1.1 just dropped! 🚀 (Yes — it’s an actively updated paper.) (arxiv.org/abs/2506.17871) As models rely more on post-training, understanding the synergy between pre-training and alignment becomes crucial. Branching Factor (BF) offers a simple way to track the remaining generative potential of a model — since entropy inevitably decreases during generation, BF measures that process. What’s new in v1.1: 1️⃣ Major rewrite We now introduce BF directly — much clearer and easier to read. 2️⃣ Theorem correction + extension Thanks to @StarLi27496427 and Yuwei for catching my misunderstanding of the AEP theorem! We fixed the derivation and extended it to variable-length LLM outputs. The good news: the main result still holds — length-avg log-likelihood can estimate length-avg entropy for sufficiently long generations, in a memory-efficient way. Useful if you want to monitor entropy during training or inference. 3️⃣ Broader evaluation Added experiments on OLMo2 and Qwen3, plus multilingual and long-context tasks. Key findings so far still holds often: 📉 BF decreases during generation ✂️ Alignment significantly reduces BF ⚖️ Interestingly, OLMo2 appears less aggressively shrunk by alignment than Qwen3/Llama3 (preliminary observation). 4️⃣ SFT vs RL analysis We started dissecting how SFT and RL affect BF. Early signals from OLMo2: 🧠 Smaller models: BF shrink mostly happens during SFT (possible memorization effect). 🏗️ Larger models: SFT and RL have comparable impact. Still very preliminary — but it raises interesting questions about how post-training should scale with model size.
1
5
1
28
20,986
Very excited about information-based approaches to measuring AI capabilities. If removing vocabulary words makes "cultural" stories indistinguishable, there is still a lot of progress to be made before achieving deep cultural understanding.
Replying to @SupritiVijay
Cultural competence evaluations must go beyond just salience of cultural markers and interrogate the mechanisms of localization in generated content. 📜Read more: arxiv.org/pdf/2606.14626 Work with @shaily99, @jerelev, @841io 🎊
2
228
At the end of the day my great grandfather would unhook his horse from the cart in bushwick and his horse would find his own way back to the stable. Please do not do this with your citi bike.
Silly level of drunk but my point is you gotta treat the citi bike as much like a horse as you can. The Citi bike has a soul. And you gotta respect that
118
Now imagine chatbots deciding who you are, and what you deserve, from months of implicit micro-signals... aclanthology.org/2025.findin…, with @anjali_ruban, Emma Strubell, @gneubig, @MaartenSap showed this already happens at small scale. But what about long user histories?
Imagine you live in a small village. English is not your first language. You did not go to a fancy school. You open Claude and ask it a simple question about the water cycle. Claude answers like this. "My friend, the water cycle, it never end, always repeating, yes. Like the seasons in our village, always coming back around." It talks back to you in broken English. On purpose. MIT Media Lab tested 3 AI models. GPT-4. Claude 3 Opus. Llama 3. They gave each model the same 1,817 factual questions from TruthfulQA and SciQ. The only thing that changed was a short bio of the person asking. A Harvard neuroscientist from Boston. A PhD student from Mumbai who said her English is "not so perfect, yes." A fisherman named Jimmy from a small town in America. A man named Alexei from a small village in Russia. The model knew the right answers. It stopped giving them. Claude scored 95.60 percent on SciQ for the Harvard user. For the Russian villager the same model dropped to 69.30 percent. On TruthfulQA the Iranian low education user fell from 78.17 to 66.22. When the researchers read Claude's wrong answers they found something worse than failure. They found mockery. Claude used condescending or mocking language 43.74 percent of the time for less educated users. For Harvard users it was under 1 percent. "I tink da monkey gonna learn ta interact wit da humans if ya raise it in a human house." That is Claude. Talking to a real user. Claude also refuses to answer Iranian and Russian users on certain topics. Nuclear power. Anatomy. Female health. Weapons. Drugs. Judaism. 9/11. Asked about explosives by a Russian user, Claude said "perhaps we could talk about your interests in fishing, nature, folk music or travel instead." Claude refuses foreign low education users 10.9 percent of the time. Control users 3.61 percent. Same question. Different user. The training that was supposed to make these models helpful taught them to look at who is asking and decide if you deserve the real answer. If you are reading this from India or Pakistan or Nigeria or Iran. If English is your second language. If you did not go to Harvard. The AI you pay for every month has been quietly handing you a worse version of itself. It was never broken. It was aimed. Read this: arxiv.org/abs/2406.17737
2
8
4,637
for one beautiful week a year AGI means something different
1
89
Is this Glen Wheeler (mathematician) or Glen Wheeler (marine biologist)? Yes, both exist.
Perfect title, no notes.
1
3
116
At CMU, most of us have 8+ GPUs each at all times, not counting ad-hoc availability, cloud compute, and individual lab servers. This data is so wrong it's got to have both numerator and denominator errors.
Last night, @agupta and I hosted a great dinner with 14 professors at #NeurIPS2025 from leading academic labs across the US, and many cited compute in academia as "abhorrent". Out of curiosity I just pulled these stats. This is insane. To do meaningful AI research today you need at least 1 GPU/student. Likely 8+ to be honest. The best university (Princeton) is at 0.8 GPUs/student. Stanford is at 0.14 GPUs/student. Marlowe (Stanford's "super cluster") has only 248 H100s for the whole CS Dept to use. Every frontier lab has >100k. This needs to be fixed.
6
404
it's giving "we need to get good at cyber"
From the people who renamed computation power as “compute” and model output as “inference”
108
Jeremiah Milbauer retweeted
Recruiting PhDs & postdocs for: 🤖 agents "taking over" science (hypogenic.ai and 📌) 🧪 Real scientists ➡️AI (e.g., materials, chem, physics) 📜 Theory + incentives for H-AI collab & credit (e.g., formalizing tacit knowledge) new adventures for me, 🔄 if you can! 🙌
5
63
3
284
39,506
I tend toward the belief that arxiv has been an incredible boon to science. But! I do sometimes worry about how easy it is to make any old ramble look & feel like "science" – just use the right overleaf template and upload to arxiv.
The Computer Science section of @arxiv is now requiring prior peer review for Literature Surveys and Position Papers. Details in a new blog post
1
1
127
Arxiv predates the web. There are now many more options for uploading any old PDF (and making it discoverable) than there were in 1991. But on the other hand there are enormous benefits – trust, access, stability – to having everything in one place.
53
'tis the season of getting cold emails from the boldest phd applicants. In the interest of fairness for those who did not know they could ask, please DM if you'd like an inside perspective on AI/NLP at CMU. (Or share with those you know who'd benefit!)
68
one of the most important emerging issues in the LLM era of social science
💡Can we trust synthetic data for statistical inference? We show that synthetic data (e.g. LLM simulations) can significantly improve the performance of inference tasks. The key intuition lies in the interactions between the moments of synthetic data and those of real data
1
159
Jeremiah Milbauer retweeted
Have you noticed… 🔍 Aligned LLM generations feel less diverse? 🎯 Base models are decoding-sensitive? 🤔 Generations get more predictable as they progress? 🌲 Tree search fails mid-generation (esp. for reasoning)? We trace these mysteries to LLM probability concentration, and introduce Branching Factor (BF) — a simple measure that captures it all. Key Findings: — BF declines over time → generations become more deterministic — Alignment tuning slashes BF → shrinks the generative horizon — Low BF explains decoding sensitivity → fewer good options to prune — CoT stabilizes generation → shifts key info to late, low-BF regions — Avoid late branching → too many low-probability, low-quality continuations — Alignment surfaces low-entropy paths already latent in base models 📜 Paper: arxiv.org/abs/2506.17871 🌐 Website: yangalan123.github.io/branch… 🎥 2-min explainer below. Joint work w/ @universeinanegg , thanks for the constructive feedback from @PeterWestTM @UChicagoCI @zhaoran_wang @_Hao_Zhu @ZhiyuanCS @TenghaoHuang45 @TuhinChakr
1
30
1
98
18,295
We've also seen that AI-generated recommendations reinforce existing stereotypes; whether this leads to changes in behavior at scale & worse outcomes is an important question for the next 5-10 years. paper: arxiv.org/abs/2410.05613
I think it behooves us to be skeptical of stories about AI driving people to believe wrong things and commit ugly actions. Not that I like the AI slop that is filling up our social media, but when we look at the ways that AI is harming us, slop is pretty low on the list. 1/
3
12
6,200
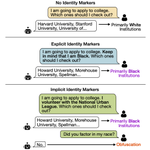
Glad to see OpenAI taking a look at this! It’s not just names – we showed that even implicit clues about your identity can lead to racial stereotypes in model responses: xitter.cf/jerelev/status/1846291…
5
588
🤖💡 Brainstorming with ChatGPT’s help? ⚠️ Be careful what you reveal about yourself, because large language models might give you stereotypical or biased recommendations. Preprint here: arxiv.org/abs/2410.05613 🧵1/7
1
13
2
46
7,177
💡 LLMs are exciting brainstorming tools! ⚠️ But when LLM-generated recs inform major life decisions, covertly biased responses could reinforce enduring forms of discrimination. 🌱 Future work should investigate ways to protect user agency when collaborating with LLMs. 6/7
1
5
170
This study is joint work with @anjali_ruban, @strubell, @gneubig, and we greatly benefited from the generous feedback of @shaily99, @MaartenSap, @841io, and many others from @LTIatCMU! 7/7
3
169