
Senior AS @Microsoft. Ph.D. @UChicago Ex-SR @google Ex-Scientist @AWS. Ex-RA @jhuCLSP @columbianlp @TsinghuaNLP. Ex-Intern @IBM @AWS. Opinions are my own.
Redmond, WA
Joined March 2017
- Tweets247
- Following780
- Followers2.3K
- Likes822






Pinned Tweet
Have you noticed…
🔍 Aligned LLM generations feel less diverse?
🎯 Base models are decoding-sensitive?
🤔 Generations get more predictable as they progress?
🌲 Tree search fails mid-generation (esp. for reasoning)?
We trace these mysteries to LLM probability concentration, and introduce Branching Factor (BF) — a simple measure that captures it all.
Key Findings:
— BF declines over time → generations become more deterministic
— Alignment tuning slashes BF → shrinks the generative horizon
— Low BF explains decoding sensitivity → fewer good options to prune
— CoT stabilizes generation → shifts key info to late, low-BF regions
— Avoid late branching → too many low-probability, low-quality continuations
— Alignment surfaces low-entropy paths already latent in base models
📜 Paper: arxiv.org/abs/2506.17871
🌐 Website: yangalan123.github.io/branch…
🎥 2-min explainer below.
Joint work w/ @universeinanegg , thanks for the constructive feedback from @PeterWestTM @UChicagoCI @zhaoran_wang @_Hao_Zhu @ZhiyuanCS @TenghaoHuang45 @TuhinChakr
Honored to have the opportunity to learn OPD and RL with a wonderful team: Boyan Li, @BaleCcchen, @xiye_nlp, and @henryzhao4321! It makes a lot of sense to run OPD to warm up for RL training instead of naive SFT, and this paper uses clear, solid, and thorough experiments to explain this. Come check it out!


Excited to join this open-source effort in my spare time!
I’ve long believed that LLM alignment should be grounded in the diversity of real human behavior—not a handful of stereotypes.
Social/human/user simulation is taking off (@humansand, @simile_ai, ...), but how do we know whether these simulations are actually good?
That’s what I love about this project: Eval-via-Forecasting turns real-world societal data into a live, public reality check for simulation quality.
Come test your simulator with us!

Social simulation is now a product. Evaluation still has no common standard.
What if we tested every simulator against the real future?
We built Social Simulation Arena with researchers from MIT, Stanford, Harvard, CMU, UC Berkeley, and beyond.
Persona-prompted populations. Digital twins. Silicon samples. Synthetic populations. Worlds of a billion agents.
We have more ways than ever to simulate human behavior. But we still lack a standard everyone can trust to tell which ones work.
Most studies use their own datasets, often historical surveys whose answers are already online. A model that has seen the answer sheet can look brilliant.
Social Simulation Arena is a different kind of test: prospective, independent, and shared.
Simulators submit and lock their forecasts before each data release. When the real results arrive, every entrant is scored by the same rules.
Can a simulator predict a public before it moves?
If you’re building one, bring it.
social-simulation-arena.com
#MIT #Stanford #Harvard #AI #Agents #LLM #SocialSimulation #Evaluation


🎉 Our paper “LLM Probability Concentration: How Alignment Shrinks the Generative Horizon” is accepted by TMLR!
The short version:
📉 LLM generation usually self-narrows
✂️ Alignment compresses the horizon further
⚡ Unexpected context can reopen it locally
We study these dynamics with Branching Factor (BF)—exponentiated length-averaged entropy, interpreted as the effective number of plausible next steps.
Direct evidence first: across tasks, BF typically declines as more tokens are generated, in both base and aligned models.
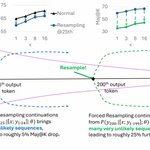
Then we intervene. Replacing the model’s own prefix with equally long random tokens makes BF jump; continued autoregressive generation narrows it again. Self-narrowing is therefore a robust aggregate tendency, not a monotonic token-wise law—and not an artifact caused only by alignment.
Alignment is a separate force: it lowers BF by 2–5× overall and up to ~10× at early positions. Reasoning models also remain lower-BF than direct-answer aligned models at matched output lengths, so their concentration is not merely because they generate longer.
Most importantly, BF can rise in a structured setting. In synthetic agentic tasks, we hold the task, environment state, and current plan fixed, then change only the next environment feedback. A plan-invalidating surprise raises BF relative to normal progress; continued generation subsequently smooths the local spike.
So the dynamics are not simply “entropy collapse.” The model narrows, surprise can reopen its consideration set, and self-conditioning narrows it again.
Practical implication: when exploration matters, branch early—or introduce genuinely NEW information before the model has fully committed. 🧵
Learn more from our Branching Factor v1.1 tweet: xitter.cf/chrome1996/statu…

BranchingFactor v1.1 just dropped! 🚀
(Yes — it’s an actively updated paper.) (arxiv.org/abs/2506.17871)
As models rely more on post-training, understanding the synergy between pre-training and alignment becomes crucial. Branching Factor (BF) offers a simple way to track the remaining generative potential of a model — since entropy inevitably decreases during generation, BF measures that process.
What’s new in v1.1:
1️⃣ Major rewrite
We now introduce BF directly — much clearer and easier to read.
2️⃣ Theorem correction + extension
Thanks to @StarLi27496427 and Yuwei for catching my misunderstanding of the AEP theorem! We fixed the derivation and extended it to variable-length LLM outputs.
The good news: the main result still holds — length-avg log-likelihood can estimate length-avg entropy for sufficiently long generations, in a memory-efficient way. Useful if you want to monitor entropy during training or inference.
3️⃣ Broader evaluation
Added experiments on OLMo2 and Qwen3, plus multilingual and long-context tasks.
Key findings so far still holds often:
📉 BF decreases during generation
✂️ Alignment significantly reduces BF
⚖️ Interestingly, OLMo2 appears less aggressively shrunk by alignment than Qwen3/Llama3 (preliminary observation).
4️⃣ SFT vs RL analysis
We started dissecting how SFT and RL affect BF. Early signals from OLMo2:
🧠 Smaller models: BF shrink mostly happens during SFT (possible memorization effect).
🏗️ Larger models: SFT and RL have comparable impact.
Still very preliminary — but it raises interesting questions about how post-training should scale with model size.
How might we preserve or recover exploration?
At inference time
🔹 Unexpected environment feedback can reopen BF locally. (PUSH your Agent like an evil 😈)
🔹 EAD explores early, then anneals toward exploitation: arxiv.org/abs/2510.05251
🔹 BACo—accepted at ICML 2026—dynamically routes between base and aligned models to recover breadth without giving up utility: arxiv.org/abs/2511.05650
At training time
🔹 In our controlled pipeline, Iterative DPO preserves substantially more BF than offline DPO/PPO. This is an encouraging case study, not a universal algorithm ranking.
🔹 Multi-answer RL internalizes distributional search in one generation (ICML 2026): arxiv.org/abs/2603.24844
🔹 Pass@k Training rewards set-level coverage and maintains higher policy entropy: arxiv.org/abs/2508.10751
These approaches intervene at different levels, but share one goal: prevent the policy from repeatedly collapsing onto the same already-explored trajectory.


📄 TMLR: openreview.net/pdf?id=KotVuX…🌐 Website: yangalan123.github.io/branch…
💻 Code: github.com/yangalan123/LLMBr…
Joint work with @StarLi27496427 and @universeinanegg.
Big thanks for the insightful discussions and support from @PeterWestTM @weixiong_1 @zhuokaiz @ZhiyuanCS @TuhinChakr @KaichaoYou @zhaoran_wang @TenghaoHuang45 @_Hao_Zhu
Also, thanks to the great community support: @vllm_project @UChicagoCI @RLHFlow and OpenRLHF
#LLM #Alignment #TMLR
Chenghao Yang retweeted

Excited to share that I’ll be presenting our #ICML2026 paper in Seoul:
ExVerus: Verus Proof Repair via Counterexample Reasoning
📍 Poster: Thu, Jul 9, 5:00–6:45 PM KST, Hall A #2004
💡 DL4C Workshop: Fri, Jul 10, Session 2, 3:20–4:50 PM KST, Hall A (Board 100-119)
Paper: openreview.net/forum?id=FNDk…
Happy to discuss!
This work focuses on LLM-based Verus proof repair. Verus is a practical Rust-based deductive verification framework that has been used to verify large-scale critical systems, such as cluster management controllers (Anvil) and virtual machine security modules (VeriSMo).
In this work, we propose a new paradigm for LLM-based proof repair: repairing a proof via synthesizing, validating, and blocking counterexamples.
1/n
Chenghao Yang retweeted

[🛫ICML] We will be presenting our paper about *base-aligned model collaboration* on Tuesday morning and also Saturday (HAI Co-Creativity workshop). Happy to chat!
PS: We've updated our paper, code, and reading list to include the latest results and resources. Check it out!

Lack of diversity in your LLM generation?
(also noted by Artificial Hivemind, best paper @NeurIPSConf)
Time to bring your base model back!
An inference-time, token-level collaboration between a base and an aligned model can optimize and control diversity and quality!

Excited to contribute to this work! 👁️📝 As someone relatively new to the multimodal world, I've always wanted to explore how we can better ground LLMs. But before diving deep into modeling, I believe we need a better understanding of what our benchmarks are actually evaluating.
Ever since Saining's "Is Vision Good Enough for Language?" (Thanks @sainingxie !) and recent 7-hour podcast deep dives, I've been fascinated by a core question: do recent popular VQA benchmarks really measure visual dependence? Have new SOTA VLMs fixed it? And does scaling up the model fix this?
Turns out, the answer is clearly "NO."
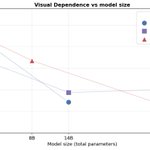
In our testing, we found that many widely used benchmarks barely need the image. In many cases, replacing the image with a short text caption yields equal or better performance. Counterintuitively, as you scale up the model, visual dependence actually decreases—the larger LLM backbone just answers more from its text pretraining priors!
This research made me realize exactly why spatial intelligence and world models are so critical right now. The benchmarks that explicitly test these spatial dimensions are the ones that demand real multimodal capability and cannot be overshadowed by a caption baseline.
We also explore some fascinating quirks, like how "self-captioning" (a kind of visual thinking) compares to other-model-captioning. Highly recommend the blog to anyone trying to learn about the realities of multimodal AI like me! 👇
🔗 harvey-fin.github.io/seeing-…


Chenghao Yang retweeted

Introducing VaSE: Value-Aware Stochastic KV Cache Eviction.
Reasoning models think in CoT, bloating the KV cache. Eviction caps memory but suffers capability drop. VaSE is a training-free recipe that cuts that cost: keep large-magnitude value states, evict stochastically.

What happens when we build an "AI society" with LLMs? Turns out, it's far more stereotyped than we thought. 🤖📉
Excited to share our new work on Persona Collapse—where distinct AI agents regress into narrow behavioral modes. Surprisingly, the models with the highest per-persona fidelity produce the most stereotyped populations!
Huge kudos to the amazing team! @lrzneedresearch @JentseHuang, Weihao Xuan! Congrats to amazing Vivienne for her first paper! (She will be applying for PhD positions, please check her out!) Thanks for the support from the 2077AI foundation! Check out our paper & toolkit here: algoroxyolo.github.io/projec…

We have some concerns about the current state of LLM-based social simulation.
We benchmarked 10 LLMs on persona simulation. Every model collapses. The "best" ones are the worst offenders. And RLHF actively makes it worse.
arxiv.org/pdf/2604.24698

Chenghao Yang retweeted

On-policy RL has driven the biggest leaps in training coding agents. Extending it to machine learning engineering agents should be a natural next step.
But it almost never works.
What I mean is, the recipe is right there — standard trajectory-wise GRPO, the same that worked for SWE.
However, the problem is that one rollout step on an MLE task may take hours because the agent has to actually train a model on a real dataset at every step (preprocessing, fitting, inference, scoring). So even with the N rollouts in a group running in parallel, a single GRPO run may still take days.
Every MLE agent paper I've read has retreated to SFT or offline proxy rewards for exactly this reason, giving up the exploration benefits of on-policy learning.
That's why I'm excited about our new paper, SandMLE, which fixes this with a move that sounds almost too reckless to work.
The instinct when on-policy RL is too slow is to engineer around it — async rollouts so the trainer doesn't sit idle waiting for slow environments, off-policy or step-wise proxies to avoid running full trajectories at all.
But when we profiled where the time was going, the bottleneck had nothing to do with the algorithm.
Unlike SWE where execution latency comes from compilation and test logic, MLE latency is overwhelmingly driven by the size of the dataset the ML pipeline has to chew through.
Therefore, rather than downsampling existing data (which corrupts evaluation), we built a multi-agent pipeline that procedurally generates diverse synthetic MLE environments from a small seed set.
Specifically, we extract the structural DNA of seed tasks (modality, label cardinality, distribution shape), mutate them into new domains (e.g., repurposing animal classification into road damage detection), inject realistic noise, embed deterministic hidden rules connecting features to labels, and construct full evaluation sandboxes with progressive milestone thresholds.
Each task is constrained to only 50–200 training samples.
The execution speedup is dramatic — average per-step latency drops over 13×, which makes trajectory-wise GRPO go from infeasible to routine.
We also designed a dense, milestone-based reward to address the sparse credit assignment problem in long-horizon MLE. The ablation shows this matters — under a sparse reward, the 30B model's medal rate drops from 27.3% to 13.6% and valid submission collapses from 100% to 86.4%.
Results across Qwen3-8B, 14B, and 30B-A3B on MLE-bench are consistently strong — 66.9% better performance in medal rate over SFT baselines.
It is worth noting that the SFT baselines are not weak— we trained them on high-quality Claude-4.5-Sonnet trajectories.
But SandMLE still delivers much larger gains, suggesting that direct environment interaction does teach capabilities that imitation alone does not (as expected).
The most convincing evidence to me that the model's intrinsic performance gets improved is the framework-agnostic generalization.
We trained exclusively with ReAct but the gains transfer to AIDE, AIRA, and MLE-Agent scaffolds at evaluation time — up to 32.4% better performance in HumanRank on MLE-Dojo.
The SFT models, by contrast, are brittle when moved to unfamiliar scaffolds. The 30B SFT model collapses to 17.7% valid submission rate on MLE-Dojo with MLE-Agent, while the 30B SandMLE model achieves 83.9%.
SandMLE is teaching genuine engineering reasoning, not scaffold-specific patterns.
What I find most interesting beyond the specific result is that none of the hard parts of RL changed here.
The algorithm is the same. The reward is conventional. We just shrunk the environment until on-policy learning became affordable.
The field has largely treated environment design and RL algorithm design as separate concerns.
SandMLE is a concrete case that the environment is itself the lever.
When training is too expensive, the instinct is to build cleverer algorithms to tolerate it.
However, often the better move is to reshape the environment so the simple algorithm just works.
Paper: arxiv.org/pdf/2604.04872

BranchingFactor v1.1 just dropped! 🚀
(Yes — it’s an actively updated paper.) (arxiv.org/abs/2506.17871)
As models rely more on post-training, understanding the synergy between pre-training and alignment becomes crucial. Branching Factor (BF) offers a simple way to track the remaining generative potential of a model — since entropy inevitably decreases during generation, BF measures that process.
What’s new in v1.1:
1️⃣ Major rewrite
We now introduce BF directly — much clearer and easier to read.
2️⃣ Theorem correction + extension
Thanks to @StarLi27496427 and Yuwei for catching my misunderstanding of the AEP theorem! We fixed the derivation and extended it to variable-length LLM outputs.
The good news: the main result still holds — length-avg log-likelihood can estimate length-avg entropy for sufficiently long generations, in a memory-efficient way. Useful if you want to monitor entropy during training or inference.
3️⃣ Broader evaluation
Added experiments on OLMo2 and Qwen3, plus multilingual and long-context tasks.
Key findings so far still holds often:
📉 BF decreases during generation
✂️ Alignment significantly reduces BF
⚖️ Interestingly, OLMo2 appears less aggressively shrunk by alignment than Qwen3/Llama3 (preliminary observation).
4️⃣ SFT vs RL analysis
We started dissecting how SFT and RL affect BF. Early signals from OLMo2:
🧠 Smaller models: BF shrink mostly happens during SFT (possible memorization effect).
🏗️ Larger models: SFT and RL have comparable impact.
Still very preliminary — but it raises interesting questions about how post-training should scale with model size.
Thanks to my friends at @OpenAI @GoogleDeepMind , and all the other passionate readers (and my kind interviewers lol) for the great questions! Here is a quick FAQ:
1) Why should I care about BF dynamics? Isn't it just about lexical-level diversity? How does it relate to application-grounded diversity (semantic uncertainty, artificial hivemind, etc.)?
Great question! At first glance, BF shares similarities with lexical diversity, as it captures the length-averaged entropy for the whole space. However:
Noise: Lexical diversity is known to be confounded by vocabulary size and generation length, correlating poorly with BF and leading to noisy interpretations.
The Upper Bound: BF serves as the upper bound for all application-grounded diversity. "Semantics" comes from domain-specific grouping of outputs. BF demonstrates exactly how many instances exist for you to group in the first place.
Control: Model probabilities and entropies are the most direct steering factors for training and inference. Studying the structure of LLM probability helps us actually control model outputs. (P.S. I already have follow-up work on RLVR rollout design based on this. Get ready for some hardcore MLSys acceleration to boost RLVR while maintaining stability and precision! 👀)
2) Is BF influenced by data contamination / seeing the prompt during training?
Yes and no—it depends on how you define "influence" and "see."
In the Appendix, we show that common data contamination metrics do not correlate well with BF. The BF dynamic is fundamentally tied to the structural progress of model generation, not just memorized data. When benchmarking, we intentionally chose model-task combinations to avoid severe contamination impacts while ensuring broad evaluation coverage.
That said, data contamination remains an active, open problem in the field, and we welcome more discussion on this!
I will be doing my PhD defense today! Come and learn about my Grounded Alignment works! Detailed information (w/Zoom) below:
Candidate: Chenghao Yang
Date: Friday, January 30, 2026
Time: 2 pm CST
Location: John Crerar Library 298
Zoom: uchicago.zoom.us/j/960149923…
Meeting ID: 960 1499 2390
Passcode: 644684


Check out @YichenZW 's great work collaborating the base and aligned models to achieve a great diversity-quality trade-off! Yichen is an amazing collaborator with strong passion and clear communication. He is looking for a Summer 2026 research intern. Don’t miss out!
Lack of diversity in your LLM generation?
(also noted by Artificial Hivemind, best paper @NeurIPSConf)
Time to bring your base model back!
An inference-time, token-level collaboration between a base and an aligned model can optimize and control diversity and quality!
Definitely agree! A single sample would often yield noisy interpretations, and we may miss a lot of hidden information on alternative "branches" (I love the tree-like animation!).
We have a similar study on the "branching structure" of LLM outputs: xitter.cf/chrome1996/statu…. Our study shows that, while tree searching may look inhibitive, for aligned models, where probability gets highly concentrated, we actually can get most information by only a few rollouts to get sufficiently many high-probability samples!

Chenghao Yang retweeted

We are starting in 15 mins!!
Join us for the #NewInML workshop happening now at @NeurIPSConf!
Location: Upper Ballroom 31ABC, San Diego Convention Centre.
We have an amazing speaker lineup that you don’t want to miss!

Chenghao Yang retweeted

📢Our @NewInML workshop will be happening today at the Room Upper 31ABC, San Diego Convention Center, starting at 12 PM!
If you're at @NeurIPSConf, it's a great opportunity for you to join us! We also have amazing speakers!
We're looking forward to welcoming you!
#NeurIPS2025

🚨 New in ML Workshop at @NeurIPSConf
We're so excited to invite you to the New In ML Workshop (@NewInML), taking place on Tuesday, December 2nd, 2025, at the San Diego Convention Center!
Great opportunity, specifically for people who are new in machine learning!
Details🧵