

Make sure you own your AI. AI in the cloud is not aligned with you; it's aligned with the company that owns it.
Sofia
Joined August 2013
- Tweets6.6K
- Following1.5K
- Followers5.1K
- Likes12.8K




Mitko Vasilev retweeted

Six months ago we booted up the first @luceboxai prototype (Strix Halo + RTX 3090 + gray chassis).
You can see the excitement (and the 🤝) in the video. We'd thought about this product/company for years, then finally went all in to build it.
Today we're scaling production of Lucebox Zero 495, thanks to our amazing customers. We have many new products lined up for the future.
This is just the start. I’m proud of the team and excited for the future.
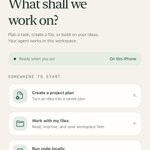
I’m running a full AI agent and model inside my iPhone
Pi durable agent
20B on-device Apple Foundation Model v3
Codemode and tools executing in sandbox
The entire agent, the tools, the model all of it is living rent-free in my pocket
Can it run Doom is now Can it run AI agent


Mitko Vasilev retweeted

Vision-related capabilities are rapidly advancing since we introduced vision to our flagship model. Now everyone can describe an idea and build their own games!

🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4


Mitko Vasilev retweeted

🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
Mitko Vasilev retweeted

We've open sourced our sandbox platform. I run thousands of sandboxes on SPACE every single day and now you get it for free. Enjoy! github.com/perplexityai/SPAC…

HP just handed me the remote keys to a ZGX Fury GB300 for the big open-source models release week
This workstation has no idea it’s about to experience the most stressful 7 days of its silicon life
No whispering "please" to the GPU gods, just the smell of burning matmul

Mitko Vasilev retweeted

We are releasing Ultramarine 1 Flash, a frontier-class model built for knowledge work. It is open-source and achieves similar performance to Fable 5, while being 60x cheaper.
It was post-trained by a team of 5 for ~$300k all-in. Available on API now, with weights releasing in 2 weeks.


Mitko Vasilev retweeted

Our lil workshop on training agent is 5x over subscribed got GitHub's office. We don't want to increase capacity. This should be a focused community thing.
So, if you're on the list and not going, please drop out to make space.
If you're want to go, please sign up and be patient. I'll do my best to make sure it's all real attendees and make a waiting list for no-shows.
luma.com/awautg3p

Mitko Vasilev retweeted

I have always been a major fan of @moondreamai, their research has always inspired me
I and so hyped to be working with @vikhyatk and @jason_allen now

Mitko Vasilev retweeted
Now I need a list of all the people who told us at launch that clustering Luceboxes was a bad idea

A lot of you asked for details on Lucebox clustering.
DeepSeek V4.1 Flash runs at up to 103 tok/s on two 128 GB Luceboxes connected by one 100 GbE link.
A single Lucebox Zero 495 with 192 GB does 54 on the same engine, so that's 1.9x when writing code. Prose after a 2K-token prompt gains less, 56 vs 37.
Each step sends about 95 small messages between the boxes, one after another, so what counts is how fast each one crosses.
Full details on our blog post, link below ⬇️

Mitko Vasilev retweeted
Over two weeks, Prime Agent orchestrated a swarm of over 2,000 agents to rewrite itself in Rust.
With 10,000+ sandboxes, 200B+ GLM-5.3 tokens, and 16,000 agent-to-agent messages, this was our largest test yet of Prime Agent’s multi-agent capabilities and our infrastructure powering these agent swarms.
Prime Agent now reaches usable input ~13× faster and uses 83% less startup memory than before.
Friday evening on my terrace at 19°C. Last warm autumn evenings in Sofia
Down in the software factory, the workers are on shift
500 million tokens deep grinding. No union rep. No breaks. Just vibes and gradient descent
Friday AI goal delegation with complete absence of guilt


