
Robot Learning PhD @ Georgia Tech
Atlanta, GA
Joined May 2018
- Tweets31
- Following89
- Followers451
- Likes31





Pinned Tweet
We have a new ICML paper! Adaptive Horizon Actor Critic (AHAC). Joint work with @krishpopdesu @xujie7979 @eric_heiden @animesh_garg
AHAC is a first-order model-based RL algorithm that learns high-dimensional tasks in minutes and outperforms PPO by 40%.
🧵(1/4)
Ignat Georgiev retweeted

Most world action models learn to act by predicting videos.
We find that predicting how the scene moves in 3D performs better.
Introducing FloMo: a world action model that uses 3D motion as the bridge between video pre-training and robot control.
Proud of this work! It's time to add RL to robot learning and exceed human demos. Nice work @VarunGiridhar3

You fine-tune a robot foundation model on a hard task. It gets 25%. Now what?
Introducing Q-Planning, a learning-based harness that lets large black-box robot policies recursively self-improve.
On a hard fine-grained task: 25% → 80% in 100 robot attempts (~30 mins), no extra human data.
q-planning.github.io/
1/n 🧵
Ignat Georgiev retweeted

You fine-tune a robot foundation model on a hard task. It gets 25%. Now what?
Introducing Q-Planning, a learning-based harness that lets large black-box robot policies recursively self-improve.
On a hard fine-grained task: 25% → 80% in 100 robot attempts (~30 mins), no extra human data.
q-planning.github.io/
1/n 🧵
Ignat Georgiev retweeted

Introducing EgoVerse: an ecosystem for robot learning from egocentric human data.
Built and tested by 4 research labs + 3 industry partners, EgoVerse enables both science and scaling
1300+ hrs, 240 scenes, 2000+ tasks, and growing
Dataset design, findings, and ecosystem 🧵
Ignat Georgiev retweeted

Heading to Seoul to present this work at CoRL 2025! Looking forward to lots of fun discussions this weekend. If you want to chat sometime please send a DM!

Ignat Georgiev retweeted
Imitation learning has seen great success, but IL policies still struggle with OOD observations
We designed a 3D backbone, Adapt3R, that can combine with your favorite IL algorithm to enable zero-shot generalization to unseen embodiments and camera viewpoints!
Ignat Georgiev retweeted
Robotics data is expensive and slow to collect.
Robotics labs and companies spend months just to collect around 10k hours of demonstration data, all while that much video is uploaded to YouTube every 20 minutes. However, none of this video data contains action labels. How can we bridge the gap?
AMPLIFY solves this problem by learning Actionless Motion Priors that unlock better sample efficiency, generalization, and scaling for robot learning.
Ignat Georgiev retweeted

I have Post-Doc, PhD, and Research Assistant positions available, for a new project working with me on dexterous robot learning!
Come and join me, my team, and our robots, at Imperial College London! 🤖🧑💻🇬🇧💂🤖
See robot-learning.uk/dexterous-… for more info.
Please share/retweet!
Behavior Cloning (BC) has been the new hot thing in #Robotics for the past year. I finally sucked my teeth into it and tried to decipher why it has worked so well for problems where RL struggles
imgeorgiev.com/2025-01-31-wh…
Let me know if you have other interesting perspectives!

Ignat Georgiev retweeted

How can robots compositionally generalize over multi-object multi-robot tasks for long-horizon planning?
At #CoRL2024, we introduce Generative Factor Chaining (GFC), a diffusion-based approach that composes spatial-temporal factors into long-horizon skill plans. (1/7)
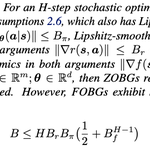
We derive a bound on this sample error and find that backproping through contact. From these insights, we propose AHAC, which dynamically adapts its horizon to avoid differentiating through contact. AHAC scales to 152 action dimension tasks and beats model-free baselines by 40%!

2
3
760
You can find the paper, video and code on our website adaptive-horizon-actor-criti…
1
4
583
Excited for ICML next week! I'll be presenting Adaptive Horizon Actor Critic - a model-based RL method that learns high dim tasks in minutes using differentiable simulation.
Stop by Hall C 4-9 or get in touch if you want to grab a coffee some other time!
More on AHAC in the 🧵
🔔New Paper - PWM: Policy Learning with Large World Models
Joint work with @VarunGiridhar3 @ncklashansen @animesh_garg
PWM is a multi-task RL method which solves 80 tasks across different embodiments in <10m per task using world models and first-order gradient optimization🧵
We also tested PWM on 30 and 80 multi-task settings from dm_control and MetaWorld. After training a single large multi-task world model, we extract policies in <10 min per task using PWM. We surpassed TD-MPC2 by 27% and 8% respectively, without the need for online planning! 🧵

1
6
769
This means that PWM can scale to billion-parameter models more effectively. Incredibly, multi-task PWM almost matches the performance of single-task experts like DreamerV3 and SAC
Check out the paper, code and models at imgeorgiev.com/pwm