

The network where software learns to improve itself.
Bittensor
Joined November 2025
- Tweets417
- Following3
- Followers801
- Likes157



first closed source. open source is next.
if your code can be taken down with one email to github, how permissionless is it?
@const_reborn we need code hosting baked into the chain.

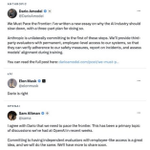
We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must…

. @sama @elonmusk @DarioAmodei want to decide how fast AI moves and who competes.
bitcoin’s power is that nobody gets to decide who can participate.
if only there were a blockchain where anyone could build and compete to produce intelligence.....

anthropic, openai and xai suddenly agreeing the industry needs to slow down should worry you.
if you don’t see the oligarchy forming, i can’t help you.

We disagree. Time to accelerate.
We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must…

Compare the models and see the benchmarks for yourself:
Gittensor: huggingface.co/gittensor-mod…
NVIDIA: huggingface.co/nvidia/Qwen3.…
Gittensor retweeted

BITTENSOR THIS WEEK: Key Updates You Need to Know
This week features updates from subnet teams like Gittensor (SN74), Score (SN44), Good Morning (SN28), OpenRoboto (SN80), Bitsec (SN60), Trishool (SN23), SOMA (SN114), Allways (SN7), and Yanez (SN54).
#Bittensor $TAO #TAO

Gittensor retweeted

A lot is shipping on Bittensor lately.
Key updates from Aug 31 – Sep 6.
→ Gittensor (SN74) - @gittensor_io
Released a Qwen3.8-27B checkpoint optimized to run on a single RTX 5090, while crossing 500K Hugging Face downloads.
→ Score (SN44) - @webuildscore
Expanded its fuel-station rollout beyond Avia to Shell and Eni franchisees, opening the door to wider commercial deployment.
→ Good Morning (SN28) - @say_gm_
Added OpenAI’s GPT-6 Astra, offering private, verifiable access at an 8.3% discount.
→ OpenRoboto (SN80) - @openroboto
Made Robbyant’s LingBot-VLA 2.0 the new base model for an OpenRoboto tournament, giving builders a model to fine-tune and compete with.
→ Bitsec (SN60) - @bitsecai
Launched Sentios, a continuous code-auditing product where agents keep scanning code as it changes.
→ Trishool (SN23) - @trishoolai
Was accepted into OpenAI’s Trusted Access for Cyber program, helping push its Halo security stack toward more organizations.
→ SOMA (SN114) - @SomaSubnet
Went live in GitHub Copilot Early Access, with DeepSeek V4 Pro, 10% savings, $5 test credits and no platform fees.
→ Allways (SN7) - @allways_io
Launched Allways Access, its first validator product, enabling native transfers across 18 assets with dual-hash receipts.
→ Yanez (SN54) - @yanez__ai
Added new customers and partners while reporting wider rollout of its Proof of Humanhood system across hundreds of devices.
Source: @taodaily_io
#Bittensor #TAO $TAO

BITTENSOR THIS WEEK: Key Updates You Need to Know
This week features updates from subnet teams like Gittensor (SN74), Score (SN44), Good Morning (SN28), OpenRoboto (SN80), Bitsec (SN60), Trishool (SN23), SOMA (SN114), Allways (SN7), and Yanez (SN54).
#Bittensor $TAO #TAO


Gittensor retweeted

Gittensor has a 5090-specific NVFP4 quant of vanilla Qwen3.8: ~17.9 GB, full 262k context target-only, plus a very fast DSpark option. Exactly the shape I wanted, just not abliterated.
Target: huggingface.co/gittensor-mod…
DSpark: huggingface.co/gittensor-mod…


Gittensor retweeted

This is at 300k downloads in the past month.
Optimizing inference for specified hardware >

262,813 Hugging Face downloads in 17 days for our RTX 5090-optimized Qwen3.8 checkpoint.
We made the most downloaded model release ever from a Bittensor subnet. Developers are running, benchmarking, and building on it.
Gittensor API coming this week.
huggingface.co/gittensor-mod…
Gittensor retweeted

Those are actually pretty impressive numbers.
It went kinda unnoticed.
262,813 Hugging Face downloads in 17 days for our RTX 5090-optimized Qwen3.8 checkpoint.
We made the most downloaded model release ever from a Bittensor subnet. Developers are running, benchmarking, and building on it.
Gittensor API coming this week.
huggingface.co/gittensor-mod…
262,813 Hugging Face downloads in 17 days for our RTX 5090-optimized Qwen3.8 checkpoint.
We made the most downloaded model release ever from a Bittensor subnet. Developers are running, benchmarking, and building on it.
Gittensor API coming this week.
huggingface.co/gittensor-mod…
Gittensor retweeted

gittensor-model-hub/Qwen3.8-27B-NVFP4-RTX5090-LMHead4 on single 5090 with 258 K and 4 concurrent users.
Gittensor retweeted

python -m sglang.launch_server \
--model-path gittensor-model-hub/Qwen3.8-27B-NVFP4-RTX5090-LMHead4 \
--quantization modelopt_fp4 \
--kv-cache-dtype fp8_e4m3 \
--attention-backend flashinfer \
--trust-remote-code \
--context-length 65536 \
--mem-fraction-static 0.86 \
--max-running-requests 1 \
--cuda-graph-max-bs 1 \
--chunked-prefill-size 1024 \
--mamba-ssm-dtype bfloat16 \
--mamba-radix-cache-strategy extra_buffer \
--max-mamba-cache-size 5 \
--speculative-algorithm DFLASH \
--speculative-draft-model-path incoai/Qwen3.8-27B-DFlash2 \
--speculative-num-draft-tokens 8 \
--speculative-draft-model-quantization unquant \
--speculative-draft-attention-backend flashinfer \
--reasoning-parser qwen3 \
--tool-call-parser qwen3_coder \
--default-chat-template-kwargs '{"enable_thinking":true,"reasoning_effort":"medium"}'
Gittensor retweeted

Been testing the dreaded nvfp4 LM head
So far so good 10% lift on decode under mtp and Dflash2 plus very similar quality scores.
It’s possible that some of the upstream PR’s applied in my build negate the issues others are seeing
huggingface.co/gittensor-mod…

Gittensor retweeted

gittensor-model-hub/Qwen3.8-27B-NVFP4-RTX5090 + Qwen3.8-27B-DSpark-NVFP4
huggingface.co/gittensor-mod…
huggingface.co/gittensor-mod…
This is the strongest Blackwell-only update today: a ModelOpt NVFP4 Qwen3.8 27B target built for a 32GB RTX 5090, plus a matching NVFP4 DSpark drafter.
Verified sizes: target is 19.18 GiB safetensors on HF; the card says ~20.6 GB export / ~18.8 GB in VRAM. DSpark drafter is 1.30 GiB on disk / 1.41 GB in VRAM.
Source numbers, all RTX 5090 32GB: full 262,144-token context fits with vLLM util 0.97; target alone decodes 80.6 tok/s; target + DSpark reports 147.9 tok/s. The target card compares against Unsloth NVFP4 on the same GPU: FP8-KV pool 275,941 tokens vs 77,184, tool calls 5/5 vs 2/5, and smoke accuracy 75% overall vs 75%.
The DSpark card adds the important bit: 147.87 tok/s, accept length 2.792, 1.41GB drafter VRAM, and a tool-calling slice at 155.9 tok/s / 3.85 accepted tokens. Calibration was 37.5% tool-calling data, so the rigid-output path was not an afterthought.
Lanes:
AMD/ROCm: not relevant.
NVIDIA/CUDA/Blackwell: test now on RTX 5090 / RTX PRO 6000-class Blackwell. DGX Spark/GB10: watchlist until SM121 numbers appear.
Apple/Metal/MLX/Mac: not relevant.
Starter target-only:
vLLM serve with modelopt quantization, FP8 KV, max-model-len 262144, gpu-memory-utilization 0.97, qwen3 reasoning parser, and qwen3_xml tool parser.
DSpark path: pin the Qwen3.8 SGLang image and use DSPARK with the DSpark repo as draft model plus modelopt_fp4 draft quantization.
Caveat: this is 5090-specific Blackwell evidence, not AMD/Mac portability and not a Spark benchmark yet.
Verdict: test now for single-Blackwell local serving; Spark watchlist.
Gittensor retweeted

Ini muat di RTX5090, jalan 24/7 di @vast_ai jatuhnya $245 saja per bulan.
Perlu testing2 untuk tahu concurrency yang masih works segimana, tapi yang jelas ngga sampai 50 juga hehe.
Qwen is good kok, Opus is overrated/nerfed nowadays.
huggingface.co/gittensor-mod…