






Pinned Tweet
"Failure is just iteration. No explosion, no innovation. Keep going."🚀
You vent to @elonmusk—he looks you in the eye and replies instantly, like a video call.
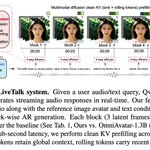
Introducing LiveTalk: real-time video gen system on a GPU that sees you, reads emotion, and responds in real time.🧵👇
Ethan Chern retweeted

1/10
Can anonymized user behavior advance LLM intelligence?
Excited to share Vela: turning behavior from real-world scenarios into training signals.
Our 35B model improves over its base on all 10 benchmarks: +11.5 pts on VelaBench and +4.0 pts on general benchmarks on average.

Ethan Chern retweeted

Introducing an interesting project- Mine Odyssey, a benchmark for measuring spatial agentic intelligence in the wild!
TL;DR: We leverage a wide variety of Minecraft maps created by the amazing community (yes, games are great lol) and challenge models to navigate through them by reading maps, finding paths, opening doors, going up and down stairs, climbing ladders, and more.
Thanks to the incredible Minecraft modding community, we can also introduce a wide range of variations for ablation studies, including weather conditions, different HUDs, first-person vs. third-person views, and reference route lines, to investigate how these factors affect model performance.
When we first launched this project, we honestly didn't think any model would be able to solve these challenges smoothly. But now, GPT-6 Astra and GPT-6.1 Sol can make it all the way to the destination remarkably quickly, with significantly fewer turns! 😨 Meanwhile, other models, even when they manage to reach the destination, often take unnecessary detours or get lost along the way.
Our benchmark is fully open-source and Harbor-compatible!
Kudos to @SArt_Maxine @llleo0612
@junxian_he
More details: mine-odyssey.github.io/


Ethan Chern retweeted

Coding agents rely on a harness to plan, use tools, and manage context. But which of these components actually help, and when? Most evaluations compare complete agent systems, making it difficult to separate the contributions of individual harness components.
Introducing An Empirical Study of Harness Design for Coding Agents 🔬👇


Ethan Chern retweeted

1/8 🔥 Announcing our new paper: “Modular TTT: Rethinking Test-Time Training as Composable Modules”
📄 Paper: arxiv.org/abs/2608.07110
💻 Code: github.com/ByteDance-Seed/Mo…

Ethan Chern retweeted

🔥 Announcing our new paper: "Diagnosing and Mitigating Context Rot in Long-horizon Search"
Extensive context has become the norm as LLMs are increasingly deployed in long-horizon tasks such as deep search. However, it remains unclear how models behave given extensive context in such scenarios, and how different strategies can alleviate the resulting issues.
Our work reveals a prevalent but previously unnoticed phenomenon: as the accumulated context grows, agents directly give up or prematurely hand over uncertain answers, and it gets worse the longer they run. We diagnose why this happens and show how to mitigate it through context management and rejection sampling.
📈 Key Findings:
1️⃣ Across 4 flagship models and 3 benchmarks, extensive context drives a sharp rise in "give-up" and "uncertain" errors. The context window itself is NOT the bottleneck.
2️⃣ Rot is caused by the accumulated content, not merely trajectory length or turn count. Wiping all context nearly eliminates rot but explodes unfinished trajectories, so careful management beats brute-force deletion.
3️⃣ Systematically comparing 7 context management methods, combining compaction + trimming achieves the best cost-rot balance, while sub-agent isolation can win big but is highly model-dependent.
4️⃣ Rot-aware rejection sampling delivers a 2.6%-4.9% average gain, with the biggest wins where rot is most severe.

Ethan Chern retweeted

🔥 Announcing our new paper: "DataOrchestra: Learning to Orchestrate Per-Example Curation of Pretraining Data"
🧹 Cleaning LLM pretraining data is the field's favorite "dirty work." And it's dirty for some reasons: it runs on hand-crafted priors — rules designed by staring at noisy text, a different rewriting prompt for every text type, and the same fixed pipeline applied to different documents.
❓ What if a model could just figure out the right cleaning recipe for each piece of text, on its own?
Meet 🎻 DataOrchestra 👇
📄 Paper: arxiv.org/pdf/2607.24717
💻 Code: github.com/GAIR-NLP/DataOrch…
Ethan Chern retweeted

Video foundation models (e.g., Seedance 1.0 → 1.5 → 2.0; V-JEPA 1.0 → 2.0 → 2.1) keep getting stronger, while public descriptions of how their training data is built keep getting shorter.
⚒️ We built VidaForge, an open-source, five-stage video data pipeline that turns raw video collections into training-ready datasets.
In an academic lab, studying video data recipes begins with a lot of tedious engineering: handling broken videos and transcode failures, keeping large jobs resumable, tracking every clip, and packaging the result for training.
Across ingestion, segmentation, selection, annotation, and training dataset packaging, data moves through:
raw videos
→ standardized videos
→ clips
→ curated clips
→ annotated clips
→ training datasets
At every step, we can inspect what happened to each video or clip. This lets us see which samples changed under a data recipe and trace a training dataset back through the pipeline.
VidaForge currently connects processed data to two video foundation model pretraining paths: Wan video generation through NeMo-AutoModel, and self-supervised video representation learning through the official V-JEPA2 repository.
We ran VidaForge end to end on 200K videos, producing over 700K clips. From these clips, we built Selected-200K, Mixed-200K, and Rejected-200K datasets for Wan2.1-1.3B and V-JEPA2.1-1B pretraining.
In these early runs, the three datasets produced different training behavior: data selection appeared in Wan2.1-1.3B eval curves and V-JEPA2.1-1B training stability.
Pipeline, experiments, open data, and project resources in the thread below ↓
Ethan Chern retweeted

🚀 Stop over-optimizing same-tokenizer distillation.
On-Policy Distillation is powerful, but it quietly assumes teacher and student share the same tokenizer.
What if they don’t?
We introduce SimCT, a simple way to recover lost supervision for cross-tokenizer OPD.

Ethan Chern retweeted

Can AI accelerate AI itself? Let's look at what actually happened!!!
AI autonomously discovered a new RL algorithm, invented 100+ novel architectures, and evolved a data curation strategy — each one outperforming the best human-designed counterparts:
🤖 RL algorithm design — discovered novel optimization mechanisms that beat human-designed GRPO by +12.5 pts on AMC
🧠 Neural architecture search — invented 100+ new architectures, surpassing Mamba, GatedDeltaNet, and more by +0.97 pts over SOTA
📦 Pretraining data curation — evolved a pipeline that outperforms FineWeb-Edu, DCLM, and Nemotron-CC by +18 pts on MMLU
🧬 Drug-target interaction — discovered a new architecture that outperforms all prior human-designed methods by +6.94 AUROC
These aren't toy demos. These are frontier-level results — produced without a human in the loop.
This is ASI-Evolve: an open-source agentic framework that closes the loop between knowledge → hypothesis → experiment → analysis, and repeats it autonomously until it finds something that works. We built it for AI research. But the loop doesn't care about the domain.
A year ago, we made a prediction:
Scale computation → Scale scientific discovery.
The world caught up faster than we expected.
Which raises a question we can't stop thinking about — and we think you shouldn't either:
In the post-AGI era, when AI generates breakthroughs faster than humanity can absorb them — when the rate of discovery permanently outpaces the rate of value conversion — what becomes the new scarcity?
Not intelligence. Not data. Not compute.
Something far more irreplaceable.
We don't have the full answer. But we think it's worth asking — loudly, and together.
💻 Code: github.com/GAIR-NLP/ASI-Evol…
📄 Paper: arxiv.org/abs/2603.29640 (1/8)
⭐ Star it. Fork it. Point it at your hardest problem.

Ethan Chern retweeted

🚨 We can download models, but not see how they were built.
Introducing daVinci-LLM: most transparent LLM pretraining project.
🔓 Open source: model weights, data pipeline, training process, ablations.
🎯 3B model matching 7B performance
🔗 Report: huggingface.co/papers/2603.2… (1/7)

Ethan Chern retweeted

daVinci-MagiHuman 一个把文本、音频、视频塞进单流 Transformer 里统一生成的人像音视频大模型
用一个 15B 的单流 Transformer 同时吃文本、视频、音频,不走多流、不堆 cross-attention,目标很直接:更快地产出嘴型、表情、动作、声音都能对上的人类视频。
github.com/GAIR-NLP/daVinci-…

Ethan Chern retweeted

daVinci-LLM 🔥
The SII-GAIR team just shared the full training pipeline on @huggingface
huggingface.co/SII-GAIR-NLP/…
✨ 3B, competitive with 7B models
✨ 8T-token transparent training
✨ 200+ ablation studies
✨ Data Darwinism (L0–L9) framework

Ethan Chern retweeted

daVinci-MagiHuman
从头预训练的 MagiHuman 在人像生成的表现,达到开源 SOTA,并且multilingual!
期待 daVinci-MagiHuman 与 daVinci agent 的组合,解锁多模态 agent 能力!
Salute @stefan_fee @ethanchern

Seedance 2.0 is impressive. But it's closed-source!
Introducing our daVinci-MagiHuman — a single-stream 15B Transformer trained from scratch that jointly generates video + audio. No cross-attention. No multi-stream branches. Just self-attention.
⚡ 5s 1080p video in 38s on a single H100
🏆 80% win rate vs Ovi 1.1 | 60.9% vs LTX 2.3 (2,000 human comparisons)
🌍 6 languages
📦 Fully open-source
Speed by simplicity.
By @SII_GAIR × @SandAI_HQ
📄 arxiv.org/abs/2603.21986
💻 github.com/GAIR-NLP/daVinci-…
🤗 huggingface.co/spaces/SII-GA…
Ethan Chern retweeted

"Speed by Simplicity: A Single-Stream Architecture for Fast Audio-Video Generative Foundation Model"
arxiv.org/pdf/2603.21986v1

Ethan Chern retweeted
daVinci-MagiHuman is a 15B single-stream Transformer, trained from scratch to generate synced video+audio with self-attention only—no cross-attention or multi-stream paths. It is open-source, supports 6 languages, beats Ovi/LTX, and runs on one H100.
🤖 Made with AI
Ethan Chern retweeted

🚀 Seedance 2.0 虽强,但闭源!
兄弟们!现在来了完全开源的 daVinci-MagiHuman!
- 15B 单流 Transformer,从零训练
- 视频 + 音频联合生成,仅用 self-attention,无 cross-attention、无多流
- 单张 H100 就能 38 秒生成 5 秒 1080p 视频
- 人评胜率:80% 碾压 Ovi 1.1,60.9% 胜 LTX 2.3
- 支持 6 种语言(含中英日韩等),WER 仅 14.6%
速度源于极致简洁,质量却拉满!
由 @SII_GAIR × @SandAI_HQ 打造,Apache 2.0 全开源
这才是开源视频生成该有的样子!
论文 / 模型 / 代码 / Demo 已放出 👇
你准备试了吗?
Seedance 2.0 is impressive. But it's closed-source!
Introducing our daVinci-MagiHuman — a single-stream 15B Transformer trained from scratch that jointly generates video + audio. No cross-attention. No multi-stream branches. Just self-attention.
⚡ 5s 1080p video in 38s on a single H100
🏆 80% win rate vs Ovi 1.1 | 60.9% vs LTX 2.3 (2,000 human comparisons)
🌍 6 languages
📦 Fully open-source
Speed by simplicity.
By @SII_GAIR × @SandAI_HQ
📄 arxiv.org/abs/2603.21986
💻 github.com/GAIR-NLP/daVinci-…
🤗 huggingface.co/spaces/SII-GA…
Ethan Chern retweeted

daVinci-MagiHuman: Speed by Simplicity
A 15B single-stream Transformer unifying text, video & audio via self-attention alone—no cross-attention. Generates 5s of 256p video in 2s on H100. 80% win rate vs Ovi 1.1.

Ethan Chern retweeted

Speed by Simplicity
A Single-Stream Architecture for Fast Audio-Video Generative Foundation Model
daVinci-MagiHuman
paper: huggingface.co/papers/2603.2…
model: huggingface.co/GAIR/daVinci-…
app: huggingface.co/spaces/SII-GA…
Ethan Chern retweeted
daVinci-MagiHuman 🎬 Human Centric Audio-Video Generative Model by GAIR
Model: huggingface.co/GAIR/daVinci-…
Paper: huggingface.co/GAIR/daVinci-…
✨ 15B – Fully open source!
✨ 5-sec 1080p video in 38s on one H100
✨ Supports 6 languages
✨ Unified model with text + video + audio