

DevSecOps engineer · Kubernetes (CKA/CKAD/KCSA) Local AI on a DGX Spark: benchmarks, recipes, breakages Open to work & collabs · 🇮🇹 in 🇨🇭
Joined November 2022
- Tweets408
- Following522
- Followers150
- Likes887




Pinned Tweet
Seven AI models. One DGX Spark. One local workspace. 🔥
Sparkfire puts a full AI suite on your own NVIDIA DGX Spark: read documents, transcribe recordings, translate, generate images, make videos with
sound, sing songs from your lyrics, build mind maps, and chat about all of it with web search. Everything runs locally, side by side, behind one interface.
𝗪𝗵𝗮𝘁 𝗿𝘂𝗻𝘀 𝗼𝗻 𝗼𝗻𝗲 𝗦𝗽𝗮𝗿𝗸 👇
💬 Chat, mind maps, web search · Saluki 27B · 12.7 GiB
📄 Read documents (OCR) · PaddleOCR-VL-1.6 · 5.4 GiB
🎙 Transcription + subtitles · Parakeet-TDT-0.6B-v3 · 1.5 GiB
🌍 Translation, 38 languages · Hy-MT2-1.8B-FP8 · 2.1 GiB
🖼 Image generation · Qwen-Image-2.1-Turbo · 17.5 GiB
🎬 Video with sound · FastH3 · loads on demand
🎵 Songs from your lyrics · YuE2-3B · loads on demand
🔎 Web search · SearXNG, running locally
Everything loaded and idle: 51 of 121 GiB. Video and music load when you use them.
𝗪𝗵𝘆 𝗼𝗻𝗲 𝘄𝗼𝗿𝗸𝘀𝗽𝗮𝗰𝗲
No juggling seven apps, seven interfaces and seven API bills. Every result is a plain file with its history, so one feeds the next: a scanned PDF becomes Markdown, then a translation, a mind map, a summary or a conversation. A generated image becomes the first frame of a video.
𝗪𝗵𝗮𝘁 𝗶𝘁 𝗱𝗼𝗲𝘀
📄 OCR that keeps headings, tables and reading order: 99.9% of words in order on a 20-page test, about 6 s a page
🎙 Transcripts with one line per sentence, SRT and WebVTT subtitles; click a line and the player jumps there
🌍 Translation as you type, or whole documents at once
🖼 Images in about 18 s at 1024×1024, about a minute at 2K, with legible lettering
🎬 5, 8 or 10 s videos with their own soundtrack; 5 s at 480p in about a minute
🎵 48 kHz stereo songs from your lyrics, with an editable score
💬 Chat with your PDFs, images and code, live reasoning, and answers that keep going when you close the tab
🔎 Web search with numbered sources
🔀 Workflows in a node editor, prompt presets, and a gallery with side-by-side compare
📱 Dark and light themes, and it works on your phone
𝗟𝗼𝗰𝗮𝗹 𝗯𝘆 𝗱𝗲𝘀𝗶𝗴𝗻
The models run on your Spark. Your files live in ordinary folders you can read, back up or move. No sign-up, no API keys, no per-token bill.
𝗚𝗲𝘁 𝗶𝘁 𝗿𝘂𝗻𝗻𝗶𝗻𝗴
git clone github.com/MovieMaker93/Spar…
./scripts/start-dgx-spark.sh --accept-model-licenses
A fresh install took 20 minutes and 106 GB of disk.
Open source (Apache 2.0). Sparkfire is a fork of @stevibe 's SparklingKit (github.com/stevibe/Sparkling…), now grown into its own project. Thankou, Steven 🙏
Model licenses apply: FastH3 isn't licensed in the EU, UK, South Korea or US (install with --video-backend none); Qwen-Image and YuE2 are non-commercial.
⭐ github.com/MovieMaker93/Spar…
Qwen3.8 Flash Next FP4 on one DGX Spark, same image:
• Prefill +4.5%: a 128k prompt now runs at 2,114 t/s, first token in 61.6 s (was 65.4), output bit-identical
• KV cache 1.37M → 1.58M tokens: 6 full 262k requests at once, up to 8 in parallel
This is the best quality recipe on a single Spark.
Next: working on adding an MTP vocabulary drafter to improve decode for specific languages, and dynamic MTP.
github.com/devopsfortunato/Q…

Even though it applies only to federal agencies, it’s a signal that the “AI war” has begun.
It’s only a matter of time before the US blocks Chinese AI models, and perhaps even restricts access to its own closed-source models.
Today, it’s more urgent than ever for Europe to wake up and build its own AI. We cannot rely on foreign countries to provide us with such a valuable strategic asset.
#EuropeWakeUp

Italians doing it better 🇮🇹💪🏻

If you want a Local AI super star to follow here he is @mudler_it 🚀 He is the creator of LocalAI project that has ONLY 50K stars on github.
Keep pushing Ettore!
Link: localai.io


Same. Free API for 3 days is nice, but the weights are what matter. If they land on the 23rd at Flash size, it goes straight onto the Spark for a test.
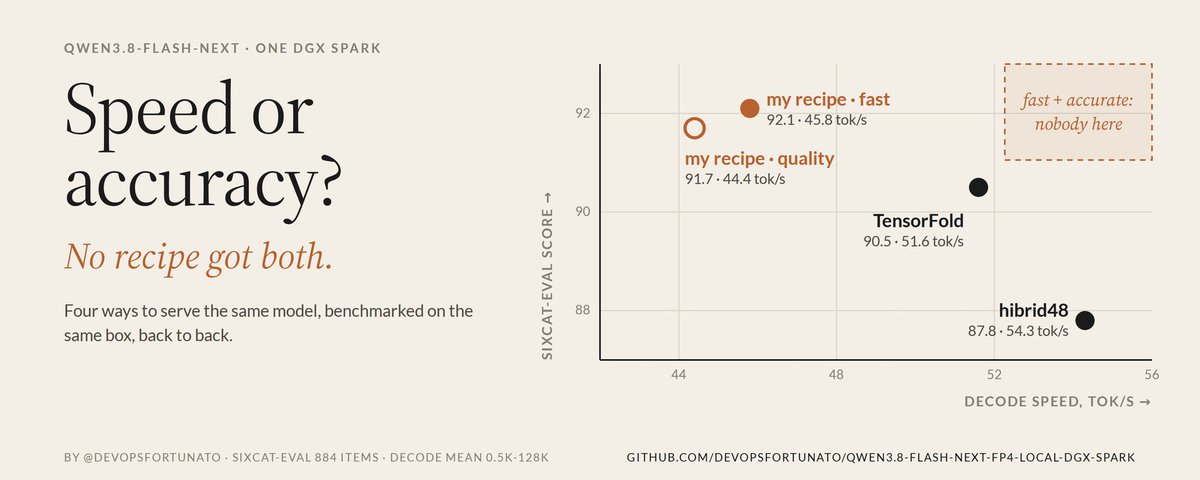
NVIDIA released a new quantization for Qwen3.8-Flash-Next (info: developer.nvidia.com/blog/ho…), so I spent two days looking for the best balance between quality and speed on my DGX Spark.
My rule: quality comes first. On a small model, output quality matters far more than raw speed numbers.
I tested my recipe against TensorFold by @MiaAI_lab and hibrid48 by @vr8vr8 / @myllmbox, the quality-focused option, using:
- tool-eval-bench by @SeraAndroid
- sixcat-eval by @ViC305
- llm_context_benchmarks by @ivanfioravanti, up to 128K tokens
The short version: answer quality is close. Speed, memory and structured output are not.
Full breakdown: xitter.cf/devopsfortunato/status…
I also released my recipe with two presets. Fast is the default. Quality improves output fidelity at the cost of some prefill speed.
github.com/devopsfortunato/Q…


you might be interested to see the results of the differente recipes @AgentSparko
Pre-bed reading.
NVIDIA does it again.
The FP4 is using quantization-aware distillation (QAD)
Read here: developer.nvidia.com/blog/ho…
Spent the day squeezing Qwen3.8-Flash-Next FP4 on one DGX Spark.
For me this is the best-quality quant of Qwen3.8-Flash-Next you can run on a single DGX Spark.
1M context, every needle found. Up to 1.7M tokens of KV cache. Tool calling holds at 91–92/100.
2M context test runs tonight.
Recipe update soon 👀
github.com/devopsfortunato/Q…
Wow, solid release from DeepSeek
I've always loved the way DeepSeek models answer. Their responses always feel so satisfying and well-grounded.
Eager to try this new beast

I tried the new mysterious model on opencode (LL Alpha Free) with the classic pagoda prompt. Really disappointing outcome, even on max thinking 😕
Prompt:
"Design and create a very creative, elaborate, and detailed voxel art scene of a pagoda in a beautiful garden with trees, including some cherry blossoms. Make the scene impressive and varied and use colorful voxels. Use whatever libraries to get this done but make sure I can paste it all into a single HTML file and open it in Chrome."
It didn't even run: the clouds had no colour set, so the page crashed on load and showed a blank sky. After a one-line fix it renders, but the pagoda roofs float as separate layers with little structure between them.
Been testing Slate AI Studio on my DGX Spark and the interface is really good.
Tried the image feature with Qwen-Image-2.1 Turbo: insane quality for the speed, ~33 seconds per portrait. Three examples below 👇
Still testing the rest, but the image side already impressed me.
Built by @u1tra_instinct, powered by TensorFold from @ashxhart
github.com/drowzeys/keys-Was…


Small Grok Bot, but useful for me: Switchboard 🔀
If you run a @LiteLLM proxy with different local models, you know the pain of setting everything up again every time you swap.
Switchboard fixes that. It keeps the same alias for the same model family, so when you swap recipes (vLLM, llama.cpp, Ollama…) you configure your harnesses once and never touch them again.
What it does:
• finds the model that's running and reads its id
• points the family alias at it, or adds a new one
• backs up the config before every change
• reloads LiteLLM and tests a real chat completion
• rolls back automatically if anything breaks
It only edits the LiteLLM config. It never starts or stops your model servers.
Built for my DGX Spark. Still early and I'm still testing it.
Try it: x.ai/bot/ppO9XYR2CUS7-Hyaklf…
#LocalAI #LiteLLM

Qwen3.8-Flash-Next FP4 on a single DGX Spark, one command.
Early recipe, still testing. ./start.sh serves NVIDIA's NVFP4 quant over an OpenAI-compatible API.
Settings:
• vLLM in eugr's Spark image, b12x kernels for GB10
• 262k context, FP8 KV cache
• Up to 8 parallel sessions
• MTP speculative decoding, 4 draft tokens
• PLE tables offloaded to disk
• Qwen3 reasoning + tool-call parsers
What's NVFP4? NVIDIA's 4-bit float format: every block of 16 weights shares an FP8 scale, plus one scale per tensor, so it holds up better than plain INT4. ModelOpt "mixed" keeps sensitive layers at higher precision. ~96 GB, native on Blackwell FP4 tensor cores.
Numbers (single stream), vs MiaAI-Lab's TensorFold INT4 recipe on the same GB10:
• 256k ctx: 1,881 vs 1,970 t/s prefill, 35 vs 38 t/s decode
• tool-eval-bench: 90/100 vs 85
• Structured output: 83% vs 40%
• Hard mode: 91% vs 74%
• Tool-call TTFT: 245 ms vs 526 ms
• TensorFold decodes faster up to 32k; FP4 holds ~35 t/s at every depth
Recipe: github.com/devopsfortunato/Q…
TensorFold recipe by @MiaAI_lab
Thanks @NVIDIAAI, vLLM, eugr


