
Postdoc at MIT BCS, interested in language(s) and thought in humans and LMs
Joined March 2022
- Tweets216
- Following590
- Followers619
- Likes1.8K





Pinned Tweet
New preprint! 🤖🧠
The cost of thinking is similar between large reasoning models and humans
👉 osf.io/preprints/psyarxiv/m2…
w/ Ferdinando D'Elia, @AndrewLampinen, and @ev_fedorenko (1/6)

Andrea de Varda retweeted

New blog post! I wrote about why I think it's useful to use metaphorical (and anthropomorphic) terms to describe AI. I start by describing the role of metaphor in language and cognition, and how metaphors can help us to efficiently understand relations and make predictions 1/2

ALT in defense of metaphor: why metaphorical descriptions of AI are useful, even if they are sometimes imperfect. a watercolor of an MLP, with a thought bubble showing a path to a goal.
Andrea de Varda retweeted

Congrats to @devarda_a, named one of the 2026 #STATWunderkinds by @statnews!
Andrea is doing groundbreaking work in @ev_fedorenko + @roger_p_levy labs to understand how brains and machines process language.
Learn more: statnews.com/wunderkinds/and…
@mitbrainandcog @ScienceMIT

Thrilled to be one of @statnews's 2026 #STATWunderkinds for my work on language processing and reasoning in 🧠 and 🤖
Big thanks to my current/previous advisors @ev_fedorenko @roger_p_levy Marco Marelli and everyone I get to work with!

Andrea de Varda retweeted

Why do neural networks become modular? Our paper is now out in Nature Machine Intelligence! @NaturePortfolio We show that multi-task learning promotes modularity under limited capacity and task demands help explain features of brain architecture in addition to the spatial constraints.
Great thanks to all the co-authors. @WHYWYH007 @yifannnwu @DaniSBassett @marcelomattar
rdcu.be/YJ12NBxvrHsa

Check out CogGym, led by @LanceYing42! 258 experiments from 100 cogsci papers (!!) in one format. Main takeaway: models are getting more human-like, but way slower than improvements on math and coding

Have we built machines that think like humans? 🧠🤖
In a new preprint, we propose CogGym, which compares AI and human judgments across 258 commonsense-reasoning experiments from 100 cognitive-science papers.
Paper: arxiv.org/abs/2609.21259
Platform: coggym.org

ALT CogGym workflow diagram: research experiments are standardized in EML by an LLM agent with human review, then rendered for human participants and computational models. Replicated and original human data are compared with model responses in a shared analysis.
Andrea de Varda retweeted

📄👀 Check out our new survey on Eye Tracking and NLP, where we reflect on past work in this space, and outline a roadmap for what's next.
Not needless to say - it's fully human written. The humans are Lena Jäger, David Reich, Omer Shubi and me. zenodo.org/records/22933169
Andrea de Varda retweeted

📢 The CORE COGNITION lab (core-cognition.github.io) is looking to hire another PhD student, working on automated scientific discovery and knowledge representation in cognitive science.
Starting date: March to September 2027.
🙏 Please share widely!
New preprint! 🤖➕➗
Shared circuits predict whether LLMs generalize across formats in arithmetic reasoning
w/ @sanapandey, @pengrui_han, @jacobandreas, and @ev_fedorenko
If you can solve 2+5, you can solve "two plus five" without learning math again. LLMs are more brittle (1/5)

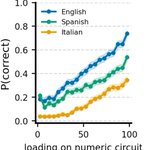
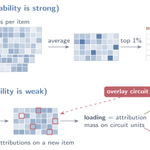
Circuit overlap predicts generalization at three levels: which formats are hardest (English > Spanish > Italian), which models generalize best, and which individual items get solved (fig below). If the numeric circuit is not engaged, the answer is almost always wrong. (4/5)

The circuit metric (unsupervised) predicts generalization as well as or better than supervised probes.
Behavioral generalization is grounded in circuit generalization: if the circuit does not transfer the ability does not either.
Pre-print 🔗 arxiv.org/abs/2609.04463 (5/5)

Andrea de Varda retweeted

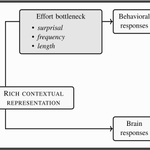
Go, @devarda_a! A beautiful and comprehensive study!🔑 finding: behav. measures are ~fully reducible to simple predictors of effort (surprisal, word length+frequency), but for 🧠 measures, LLM embeddings carry additional predictive power, likely capturing aspects of meaning.

New preprint! 🧠👀🤖
Behavioral and brain responses to language reflect different levels of linguistic representation
w/ @whylikethis_ , @ev_fedorenko , and @roger_p_levy (1/10)

Andrea de Varda retweeted
Wonderful work by @devarda_a linking behavioral and neural manifestations of language comprehension using language models. With @roger_p_levy and @ev_fedorenko
New preprint! 🧠👀🤖
Behavioral and brain responses to language reflect different levels of linguistic representation
w/ @whylikethis_ , @ev_fedorenko , and @roger_p_levy (1/10)
A similar asymmetry emerges within the effort measures. Eye movements are driven mostly by length and frequency (context-independent). Brain responses are driven mostly by surprisal (context-dependent). (9/10)
👀!=🧠
A unified theory needs both kinds of data with a clear understanding of which levels of representation each measure reflects. (10/10)
Pre-print 🔗 tinyurl.com/mr3cre4b
New preprint! 🧠👀🤖
Behavioral and brain responses to language reflect different levels of linguistic representation
w/ @whylikethis_ , @ev_fedorenko , and @roger_p_levy (1/10)

We test this on 13 datasets: 👀 4 eye-tracking, 3 self-paced reading, 1 Maze, 🧠 1 ERP (N400), and 4 fMRI. All responses are averaged across participants and brain responses are averaged across voxels/electrodes so brain and behavior are comparable (1-dimensional). (7/10)

Our hypothesis: behavior shows a bottleneck. Rich representations get compressed into effort dimensions (SFL) before they can influence processing times. Brain responses have more direct access to the high-dimensional representations. (6/10)

We use LMs to operationalize effort and meaning in one framework. From the same GPT/GPT-2 models we get (i) surprisal (+freq and len; SFL) for effort, and (ii) contextual embeddings (EMB), high-dimensional vectors that encode form and meaning. (5/10)
