
Nexus @FireworksAI_HQ Prev: @Google @RobinhoodApp @ycombinator Alum
Palo Alto, CA
Joined June 2010
- Tweets134
- Following1
- Followers2.5K
- Likes33.8K

Sriram retweeted

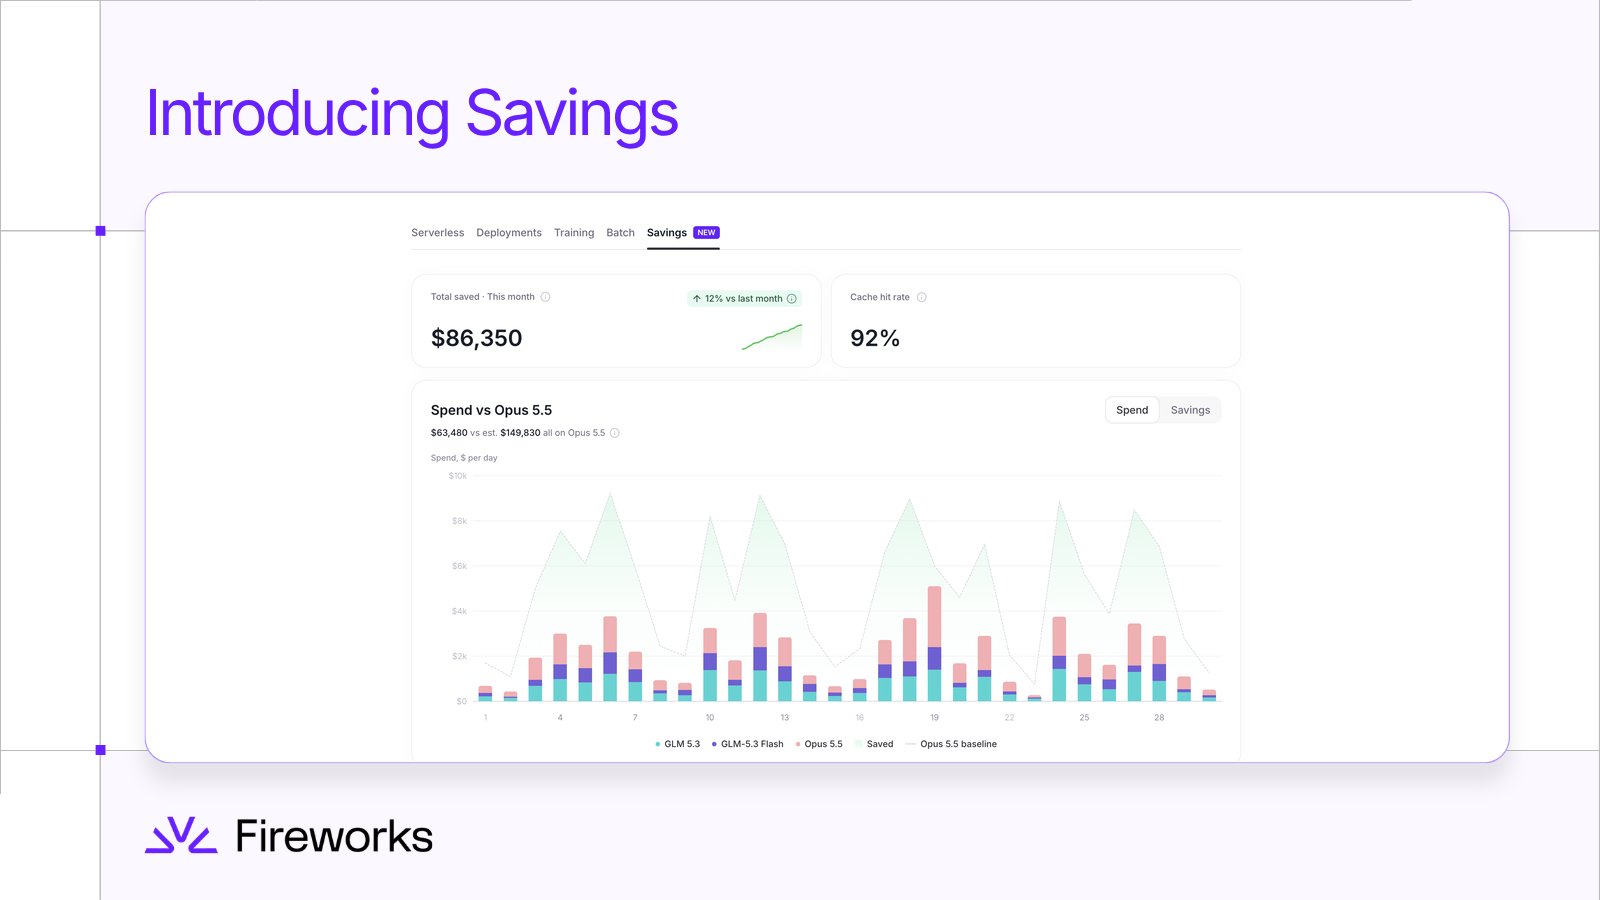
New in Nexus: Savings
See how much Fireworks open models and FireRouter are saving your team, by user and model.
Plus, track your cache hit rate.
Check out Nexus: bit.ly/4y3vrfW

Introducing Ember-1.
A model with K3-level quality at ~40% fewer tokens, live on Fireworks Serverless.
Fireworks Research & Training team has spent years helping AI companies build specialized models for their use-case.
So we asked: what if we bring the efficiencies to open models and offered them to everyone?

Ember-1 is a specialized model from Fireworks Research designed to make every token go further.
Built on Kimi K3, it produces shorter reasoning traces, using roughly 40% fewer tokens while maintaining top-tier quality.
fireworks.ai/models/firework…

You can't just rely on vibes around the model. A model that is good at coding, can be bad at securing your service or preparing your slides.
We built something very cool so you can see how models do on REAL benchmarks, not the benchmaxed ones.
If you are building a product in a specific domain or evaluating a model, point yourself and your agent at fireworks.ai/index.
Lots more coming :)

Today we're launching the Specialized Intelligence Index (SII): one destination for real-work benchmarks across industries, built by the teams that use them every day.
Hear from Fireworks co-founder @the_bunny_chen on the importance of specialized benchmarks:
Sriram retweeted
We ran 18 models across 113 real coding tasks on DeepSWE, then went back and asked a simple question: what if every task had routed to the model that handled it best?
Answer: 97.6% solve rate at $1.88 per task, versus the best model at 74.1% at $6.52.
The next frontier is a router.
Full analysis: fireworks.ai/blog/the-fronti…

Sriram retweeted

Prediction: within 12 months, top three models will be open source.
Economic winners will be the American clouds that serve them:
Nebius
Iren
Baseten
Together
Fireworks

Looks like today may be a record day for token volume % of open models on Vercel AI Gateway:
🟦 Open 78.4% 🟨 Closed 21.6%
While spend 💲 usually tells a different story, #3 and #4 today are Moonshot AI & DeepSeek. Adding Z.ai, their combined spend surpasses OpenAI (#2).
(Do note that's the spend for inference of the model across providers (mostly in the US), not revenue going directly to the open weight labs.)

Sriram retweeted
Excited to continue our partnership with the @alibaba_cloud team on this one, bringing the latest version of Qwen's flaship model to the Fireworks community. Start building with Qwen3p8 today: fireworks.ai/models/firework…


Developers need speed and uncompromising production quality. 🚀
We’ve partnered with @FireworksAI_HQ to deliver exactly that for Qwen 3.8 Max. Build faster, scale effortlessly. 🤝
#Qwen #FireworksAI #LLM #OpenSource

Sriram retweeted
We invite you to Forge.
At Forge, we will challenge you to make your own frontier.
You'll spend the day with the builders, researchers, and technical leaders pushing AI forward.
Lin Qiao. Jensen Huang. Jay Parikh. And more.
Apply to attend: fireworks.ai/forge

Sriram retweeted
GLM 5.3 is now available for training on the Serverless Training API, joining Kimi K3, Qwen 3.8 27b and more. GLM 5.3 Flash coming soon.
No sales demo or DMs required.
Here to help as needed, but you can also spend that time building.
Start with docs or a pre-made recipe ➔ github.com/fw-ai/cookbook/tr…


Sriram retweeted

periodic reminder: cache hit rate and model token efficiency (# of turns, # reasoning tokens) matter more for cost than per-token sticker price
working on more updates to ⬆️ cache hit rate on @FireworksAI_HQ

same model. same list price. 5.7x apart in real cost.
glm-5.2 across 6 hosts:
@FireworksAI_HQ 18% of list
@sferenceai 30%
@tensorx_ai 43%
@nebiustf 100%, caches nothing
the price sheet tells you almost nothing. cache hit rate is the price.

Sriram retweeted
The most ambitious companies are training models to outperform the frontier on the capabilities that differentiate their business.
Today, we announce the general availability of our Training API and Fireworks Lab, making model specialization accessible to all organizations.

Sriram retweeted

🧵How we trained Tenet version zero in under two months:
Recently @Harvey introduced Tenet, its first model, trained for long horizon legal work.
Harvey post-trained it from a Kimi K3 base in collaboration with Fireworks using async RL on our Training API.
A thread on promising initial results for both performance and cost-efficiency🧵

Sriram retweeted

Around 2 months ago we started working with the @harvey team with the vision to train a SOTA model for long horizon legal work.
It was a very fun ride with some huge learnings on post training the largest MOEs for domain specific work, some learnings in the thread ....
This is the biggest trend -- number of companies asking for open models is surging.
I wouldn't be surprised if Open models become the the standard across the harnesses for enterprises.
Today's a record day for open weight share of tokens on Vercel AI Gateway.
Aug 22 (today)
🟦 Open: 62%
🟨 Closed: 38%
Jun 24 (~2 months ago)
🟦 Open: 28.4%
🟨 Closed: 71.6%
This is very likely just the start, because enterprise adoption is still early, and harnesses, CLIs, IDEs, SDKs, etc need to be adapted to be model agnostic.

Do you know you can use open weight models like GLM, Deepseek, Kimi in Claude Code?
Setup Fireworks account - you get free credits on signup
$ curl -fsSL raw.githubusercontent.com/fw… | bash
$ fireconnect login
$ fireconnect claude
That's it!
Best part? you can use /model to switch b/n Anthropic and Open models.
Sriram retweeted
Congrats to @harvey on Tenet, their first model and a milestone for legal AI.
We’re proud to have co-developed it with them, setting the foundation for firms to build their own specialized intelligence.
Read the full writeup: harvey.ai/blog/post-training…
