
PhD Student @BerkeleySky | Prev. @UWSyFI @sjtu1896 | https://xitter.cf/t.co/ryX6LxgDpV | Systems & AI
Joined August 2019
- Tweets59
- Following320
- Followers118
- Likes358


Yi Pan retweeted

This project has been a lifesaver tbh. It's not only high fidelity, but its agent-first design and modularity makes it super easy to iterate on new ideas! I've been using it for some RL work (coming soon 👀 ). I've been seen saying to follow @KanZhu854772 and @UWSyFi!

🔥 Optimizing LLM serving requires repeated experiments, and running them on real hardware is slow and costly.
Performance depends on how models, kernels, hardware, and serving policies interact. As models and workloads change, engineers must revisit their configuration choices.
🚀 Introducing ServingStudio: an integrated workbench for simulating, analyzing, and optimizing LLM serving systems.
🧵 More in the thread below. (1/9)

Yi Pan retweeted

GPU time is too expensive for blind trial and error.
Introducing ServingStudio: simulate LLM serving configurations, use an agent to find and implement promising optimizations, then validate on real hardware.
🔥 Optimizing LLM serving requires repeated experiments, and running them on real hardware is slow and costly.
Performance depends on how models, kernels, hardware, and serving policies interact. As models and workloads change, engineers must revisit their configuration choices.
🚀 Introducing ServingStudio: an integrated workbench for simulating, analyzing, and optimizing LLM serving systems.
🧵 More in the thread below. (1/9)
Yi Pan retweeted

Qwen3.8-Flash-Next now runs on a single RTX 5090 at 68.3 tok/s — no extreme quantization, no speculative decoding.
· Production-level checkpoint: GB300-validated NVFP4 checkpoint from RadixArk
· 63GB host RAM — less than what 1-bit quants of this model need
· The 51GB n-gram table? It lives on your NVMe, at ~0.5% throughput cost
In the video: one prompt → a playable minecraft-style world, then FreeToken on my 5090 desktop fixing a real FreeToken bug in 10.5 minutes.
Meet FreeToken 🧵
Yi Pan retweeted
If you want an in-depth analysis of how your coding agents work when you use them, based on thousands of traces from *real* workloads, check out TraceLab!
Paper: arxiv.org/abs/2606.30560
Website: tracelab.cs.washington.edu/

During an agentic session, a quick “hi” after a coffee break can cost a full dollar.
But it’s not because of the “hi.” It’s the million tokens of context you’re repaying for the moment your cache goes cold.
Here's the caching math from @evan_a_frick:
0:00 Why you're billed for last turn's context, not just this one
0:17 Cache hits: ~10% of full price
0:41 Agentic AI = way more back-and-forth than chat
1:16 Paying full price for context even on a 1-token tool call
1:40 Cache hit vs. cache miss
2:13 The $1 "hi": walk away for an hour, come back to a cold cache
2:59 Cost grows by the square, even with caching
3:28 How context compaction helps
4:03 Why Claude Code/Codex may compact at ~200-300K, not the full 1M window
Yi Pan retweeted

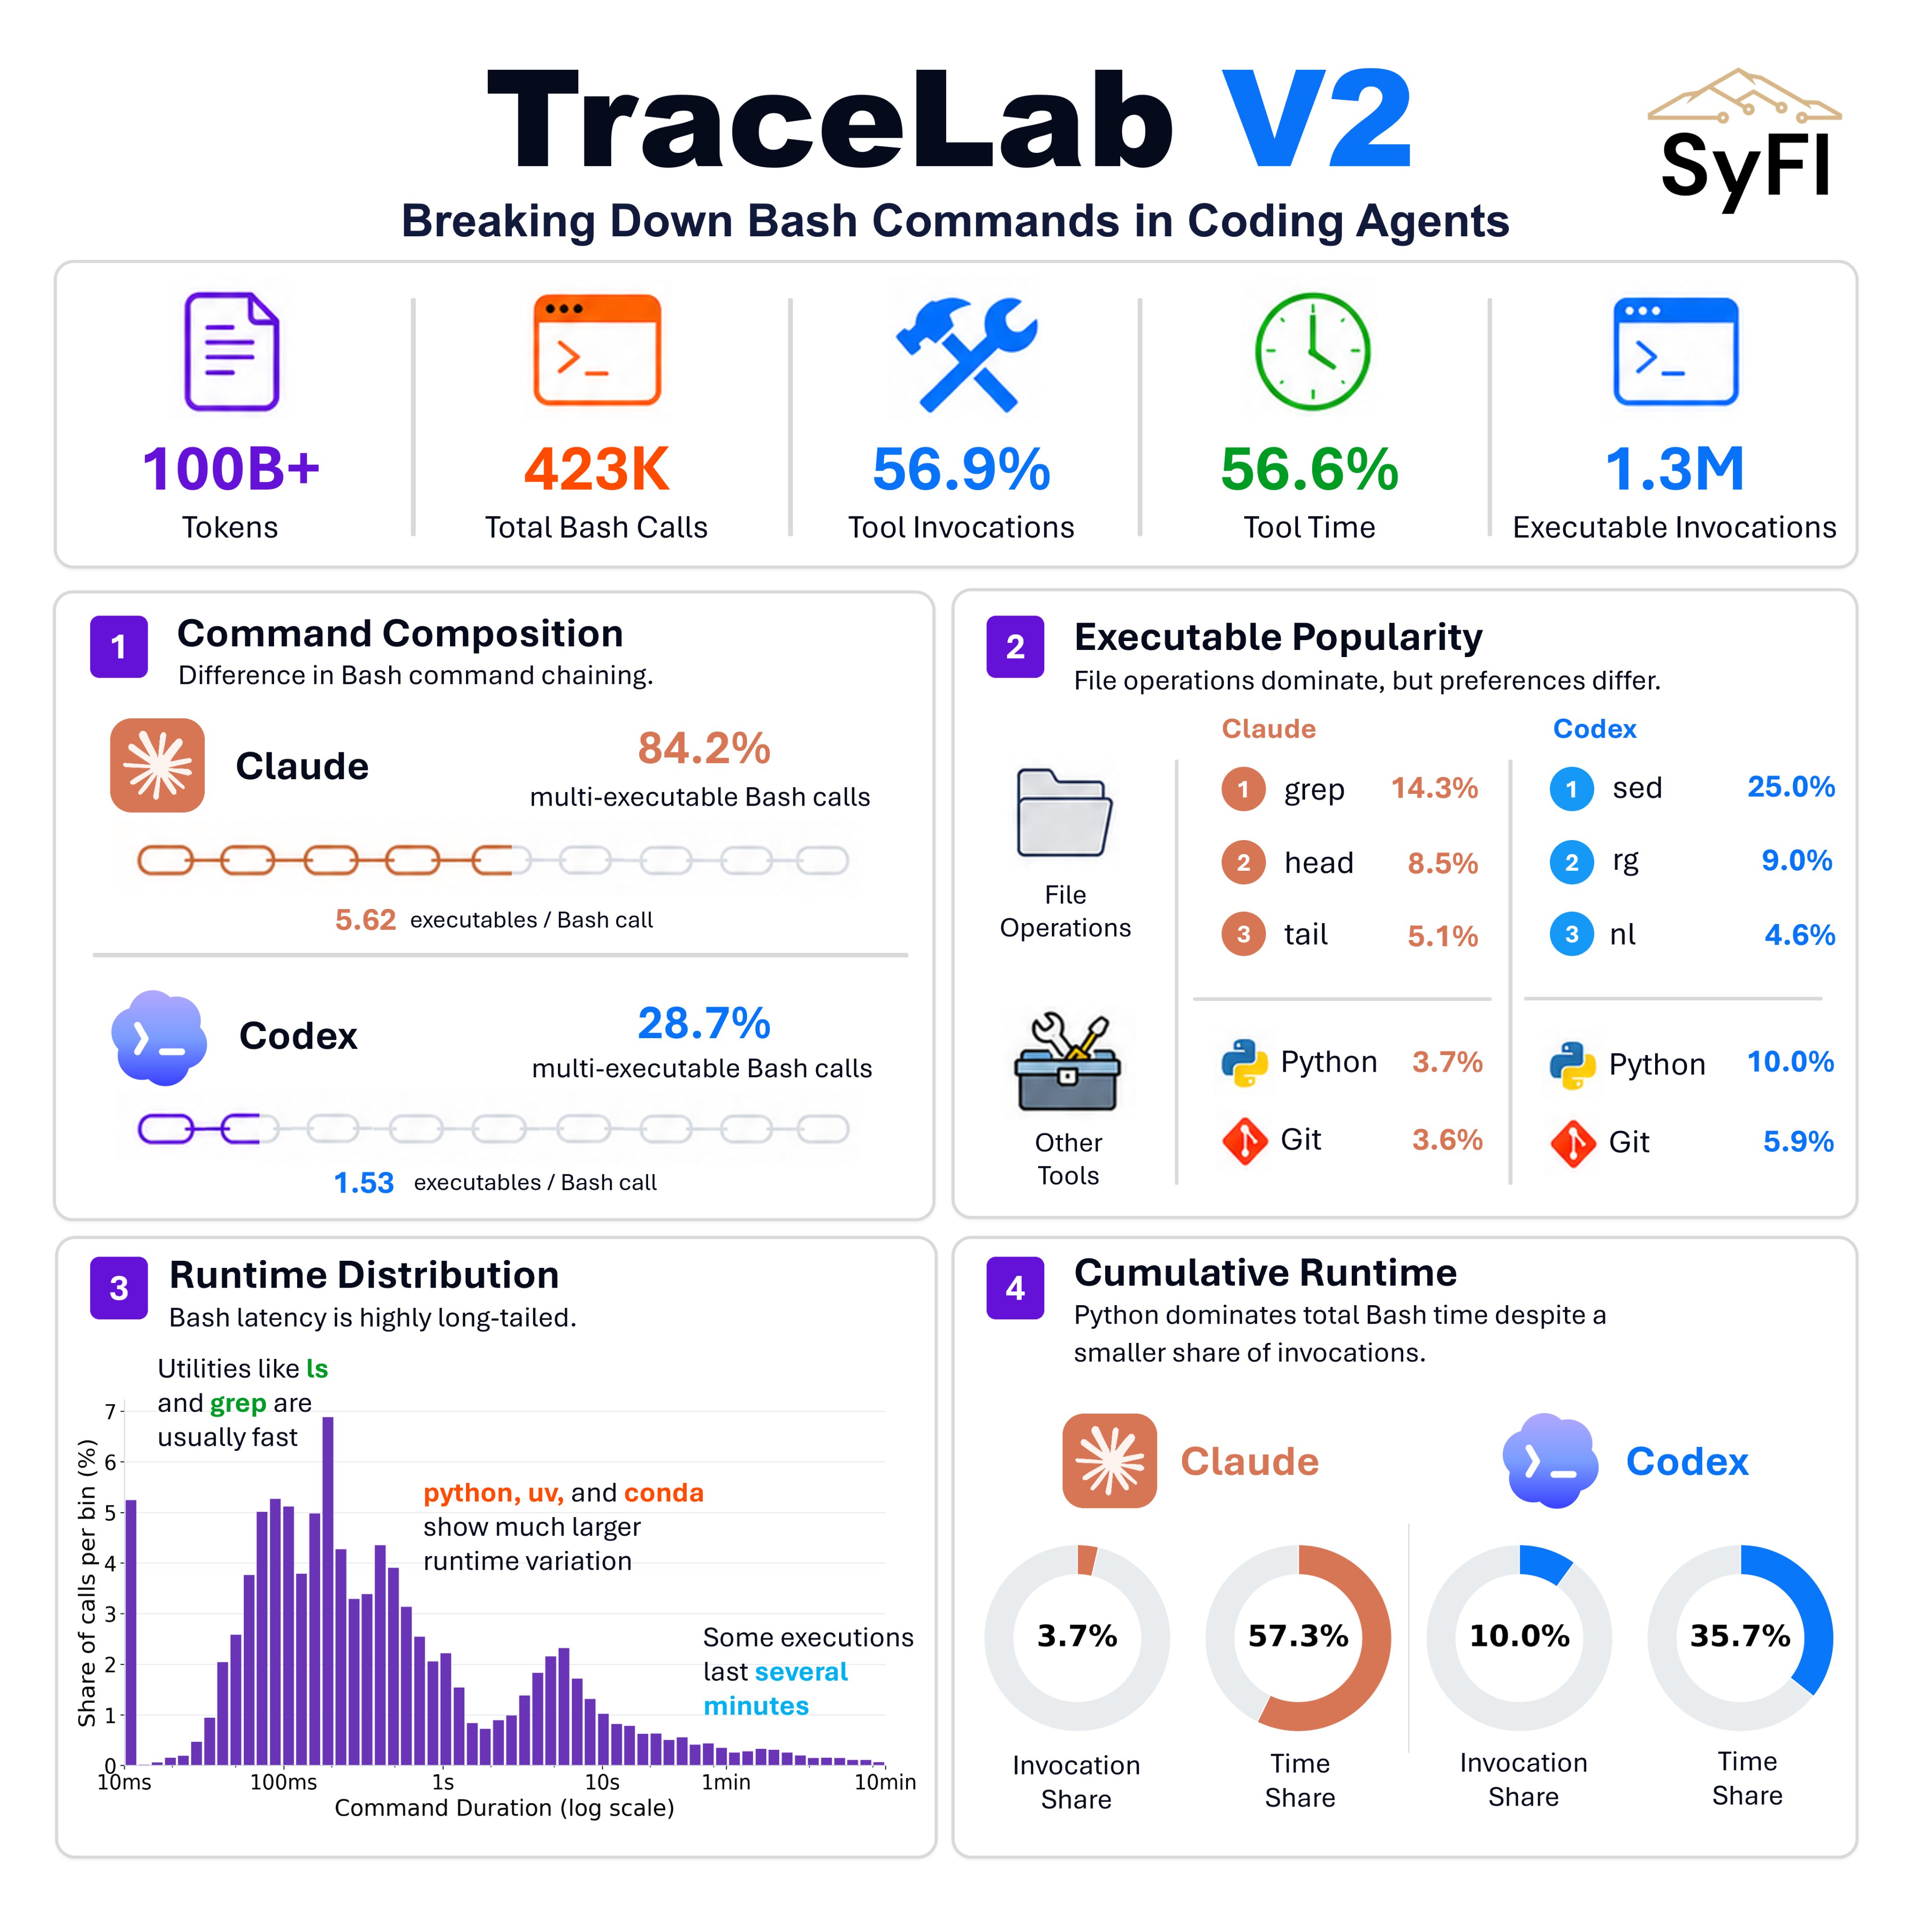
🔧Coding agents spend a surprising amount of time in the Bash.
In our Claude and Codex traces from TraceLab, Bash accounts for ~56.9% of tool invocations and 56.6% of total tool time.
But what are agents actually running?
We analyze 1.3M executable invocations to uncover command patterns, composition, and runtime behavior.
Thread 🧵(1/n)
Yi Pan retweeted
The hardest LLM serving bugs are the ones where it looked like everything worked, but accuracy quietly regressed.
Thrilled to share our latest work, Ekka, at ICML 2026! Ekka is an automated system for diagnosing silent errors in LLM serving frameworks. On real-world silent errors from vLLM/SGLang, Ekka reaches 80% pass@1 / 88% pass@5 diagnosis accuracy, improving over SOTA coding-agent baselines by 24–34%, and diagnosing 4 new bugs confirmed by developers. If you’re at ICML 2026, come say hi at Poster Session 5, Hall A #2405, on Wednesday, July 8, 5:00–6:45 PM KST.
Joint work between @UWSyfi and @awscloud with @MichaelGu341332, Zhen Zhang, Shaowei Zhu, Xinwei Fu, Jun Wu, Yida Wang, and @bariskasikci.
Paper 📗: arxiv.org/abs/2606.04594
ICML Page🌐: icml.cc/virtual/2026/poster/…
Blog: syfi.cs.washington.edu/blog/…

Yi Pan retweeted

Every team shipping a coding agent — Claude Code, Codex, Cursor — is really running a serving-systems problem. The "tech behind the tech" is the LLM-serving stack underneath, and until now nobody had real data on what that workload looks like.
New arXiv (2606.30560) from @bariskasikci's SyFI lab (@UWSyFi, @uwcse) is the first large cross-provider trace of real coding-agent use: ~4,300 sessions, 350K LLM steps, 430K tool calls, 43 developers, 8 months, Claude Code + Codex.
It breaks the intuition that agents mean long generations. The median step replays ~119K context tokens to emit just ~214 output tokens — two orders of magnitude more reading than writing. So the bill is the context, not the answer: prefix tokens are 59.5% of total cost.
Tool calls are brutally long-tailed: 80+ tools, but the top 3 are 80%+ of calls, and the 4% of calls that run >1 min eat 85% of all tool time.
And the prefix cache everyone leans on? 95.7% hit rate — yet misses cluster right after a human pauses to think, amplifying prefill 3.8x. Those human-gap misses alone are ~46% of fresh tokens and ~13% of spend.
For technical leaders: your agent's cost and latency live in the loop, the replayed context, and the idle gaps — not raw token generation. Tune tool-call overhead, append-length-aware prefill, and KV-cache eviction around human gaps before you scale the fleet.

Yi Pan retweeted
To make serving coding agents more efficient, we need better hills to climb than traces from synthetic benchmarks like SWE-Bench. This work led by @KanZhu854772 is critical in curating a realistic workload for the ML Sys community to climb! (plus you can analyze your own usage!)
🔥 Coding agents have become one of the hottest LLM workloads. But serving them looks nothing like serving a chatbot: 294× more input than output, hundreds of thousands of tool calls, and extremely long-tailed latency.
🚀 We are releasing the SyFI Coding Trace: ~4,300 real-world coding-agent sessions from our daily use, plus TraceLab, an open-source pipeline to collect, sanitize, analyze, and replay your own traces.
More in the thread below 🧵👇 (1/n)

Yi Pan retweeted

Checkout this great statistic and analysis on modern agentic inference workloads!
🔥 Coding agents have become one of the hottest LLM workloads. But serving them looks nothing like serving a chatbot: 294× more input than output, hundreds of thousands of tool calls, and extremely long-tailed latency.
🚀 We are releasing the SyFI Coding Trace: ~4,300 real-world coding-agent sessions from our daily use, plus TraceLab, an open-source pipeline to collect, sanitize, analyze, and replay your own traces.
More in the thread below 🧵👇 (1/n)
Yi Pan retweeted

Today's AI agents can diagnose production incidents, but they start from scratch every single time. What if they could remember?
New on @acmsigops: our work on the Self-Defining Operator, a multi-agent system with long-term memory for autonomous ops.

New SIGOPS Blog -- "The Long Game: How Agents That Remember Resolve Operational Issues Faster" by Shihang (Vic) Li, Thomas Anderson, Ratul Mahajan, Simon Peter, Luke Zettlemoyer, and the SDS team.
sigops.org/2026/the-long-gam…

Yi Pan retweeted
How to beat all compression using LLMs?
⚙️ Introducing LLMc — a lossless compressor built with LLMs. LLMc leverages the predictive power of LLMs to beat traditional compressors like Gzip and LZMA on natural language text. (1/4)
🔗 Blog Post: syfi.cs.washington.edu/blog/…
💻 Code: github.com/uw-syfi/LLMc
Yi Pan retweeted
🎙️ Introducing VoxServe — a high-throughput, low-latency serving system built for Speech Language Models (TTS, STS, etc.), natively handling audio detokenization + streaming with performance as the core goal. (1/4)
🔗 blog post: vox-serve.github.io/2025/09/…
💻 code: github.com/vox-serve/vox-ser…

Yi Pan retweeted

A petition to SIGOPS to adopt the USENIX Annual Technical Conference (ATC) and retain its steering committee
docs.google.com/document/d/1…
(not sure whether it can be done by SIGOPS alone, but it's great to let the voice be heard)

Yi Pan retweeted

1/3 Today, an anecdote shared by an invited speaker at #NeurIPS2024 left many Chinese scholars, myself included, feeling uncomfortable. As a community, I believe we should take a moment to reflect on why such remarks in public discourse can be offensive and harmful.


Yi Pan retweeted

今天看到一个项目把我震撼得瞠目结舌
scratch.mit.edu/projects/892…
作者用 Scratch 手打了 RISC-V 指令集,作为模拟器运行 Linux 6.1 内核
这相当于用积木和胶水纯手工建造一艘邮轮,并成功乘坐它完成了环球旅行


