
The Systems for Future Intelligence lab at @uwcse.
Seattle, Washington
Joined February 2026
- Tweets70
- Following16
- Followers131
- Likes39
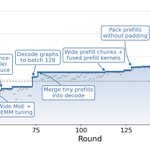






6/ Other optimizations: a fused MXFP4 MoE kernel, a fused all-reduce + RMSNorm, and MTP speculative decoding.
7/ Full write-up: syfi.cs.washington.edu/blog/…
VibeSys: github.com/uw-syfi/vibesys
Agent-built engine: github.com/vibesys-playgroun…
Tuned SGLang: github.com/vibesys-playgroun…
This project was led by @sudopowr, @KeisukeKamahori, Simon Peter, and @bariskasikci
Other optimizations: a fused MXFP4 MoE kernel, a fused all-reduce + RMSNorm, and MTP speculative decoding.
(6/n)
Full write-up: syfi.cs.washington.edu/blog/…
VibeSys: github.com/uw-syfi/vibesys
Agent-built engine: github.com/vibesys-playgroun…
Tuned SGLang: github.com/vibesys-playgroun…
(7/n)
We first used VibeSys to port and tune SGLang (961 tok/s), and compare against that. Stock SGLang does not run this model on MI300A: no MXFP4 MoE kernel for gfx942, memory sizing that assumes discrete GPU memory, and a 60-minute weight load.
(4/n)
The biggest single gain while the agents built their own engine was snapshot eviction: +27% goodput over the previous build.
Qwen3.5 is 45 Gated DeltaNet layers + 15 full-attention layers. Each DeltaNet snapshot is ~47 MiB, and MI300A's HBM is shared with everything else. The prefix cache kept stale interior snapshots, evicting active conversations, whose next turns recomputed the full history.
Evicting stale snapshots first cut prefill tokens by ~40%.
(5/n)
The objective was peak goodput: throughput of responses that meet the latency SLO (p95 TPOT ≤ 250 ms, p95 TTFT ≤ 10 s) on a multi-turn chat workload that ramps from 1 to 192 concurrent sessions.
(2/n)
The agents received the weights, the HF reference implementation, the benchmark, and a description of the hardware. They could use PyTorch, Triton, and AITER kernels, but no serving code from SGLang, vLLM, or TensorRT-LLM.
They wrote the scheduler, caches, parallelism, graph capture, and several kernels themselves (~19.4k lines).
(3/n)
The objective was peak goodput: throughput of responses that meet the latency SLO (p95 TPOT ≤ 250 ms, p95 TTFT ≤ 10 s) on a multi-turn chat workload that ramps from 1 to 192 concurrent sessions.
(2/n)
🔥 Optimizing LLM serving requires repeated experiments, and running them on real hardware is slow and costly.
Performance depends on how models, kernels, hardware, and serving policies interact. As models and workloads change, engineers must revisit their configuration choices.
🚀 Introducing ServingStudio: an integrated workbench for simulating, analyzing, and optimizing LLM serving systems.
🧵 More in the thread below. (1/9)

🔭 We plan to:
- Support newer models, including GLM-5.3 Flash, DeepSeek V4.1 Flash, and Kimi K3.
- Model distributed prefix caches, including cache offloading across GPU memory, host memory, and remote storage.
- Enable remote hardware profiling and release a public kernel-performance database.
(8/9)
Conclusion
ServingStudio Sim helps engineers explore optimization ideas faster in simulation. ServingStudio Agent then implements promising changes and validates their effects on real hardware.
🤝 Explore ServingStudio and try it with your workload.
🌐 Website: syfi-servingstudio.github.io…
🛠️ Code: github.com/SyFI-ServingStudi…
This work was led by
@KanZhu854772, @MichaelGu341332, Sheetal Sriram, @mat_jacob1002, @KeisukeKamahori, @sudopowr, @conlesspan, @DedongX, @thepadawang, @arvind_uw, and @bariskasikci.
(9/9)