

26 🇮🇳, MS CS @RITtigers NY 🇺🇸 | Maintainer - @IntuticAI | Ex- @Broadcom @VMware
New York, USA
Joined May 2017
- Tweets9.4K
- Following3.4K
- Followers1K
- Likes19.5K



Ishan Gupta retweeted

Learn to build evals, folks.
Highly recommended reading on using decision models for evals.
From our internal evals, System One models like Jev are a great fit for LLM Judges.
If you want to go beyond Hamel's great write-up, I've also put together a few resources on applying decision models to LLM judges.
(bookmark it)
1) Jev-as-a-Judge for Agent Evaluations - academy.dair.ai/dashboard/re…
2) Jev-as-a-Judge: Evaluating Agents with a Decision Model - academy.dair.ai/labs/jev-as-…
Bonus paper I would recommend, with a few other ideas that combine System One and System Two models: Jev-as-a-Judge paper - arxiv.org/abs/2609.26550


Ishan Gupta retweeted

This might be the most useful paper on AI agents this year.
A team at Wavestone AI Lab took apart Claude Code, Codex and 9 more and found the 7-part blueprint every good agent is built on.
Their definition: an agent is a model plus a harness. All 11 agents build the harness from the same 7 parts. Only the size changes.
> Loop: Mini-SWE-Agent is a plain while loop. OpenHands logs every event so a run can be replayed
> LLM layer: one prompt template on one side, 29 provider profiles on the other
> Tools: some agents only have bash, the biggest has 43 typed tools loaded on demand
> Memory: from keep-the-whole-history to notes the agent maintains across sessions
> Safety: from a simple step limit to policy rules plus a reviewer model plus an OS sandbox
> Orchestration: Aider skips sub-agents on purpose, others fork them with their own context
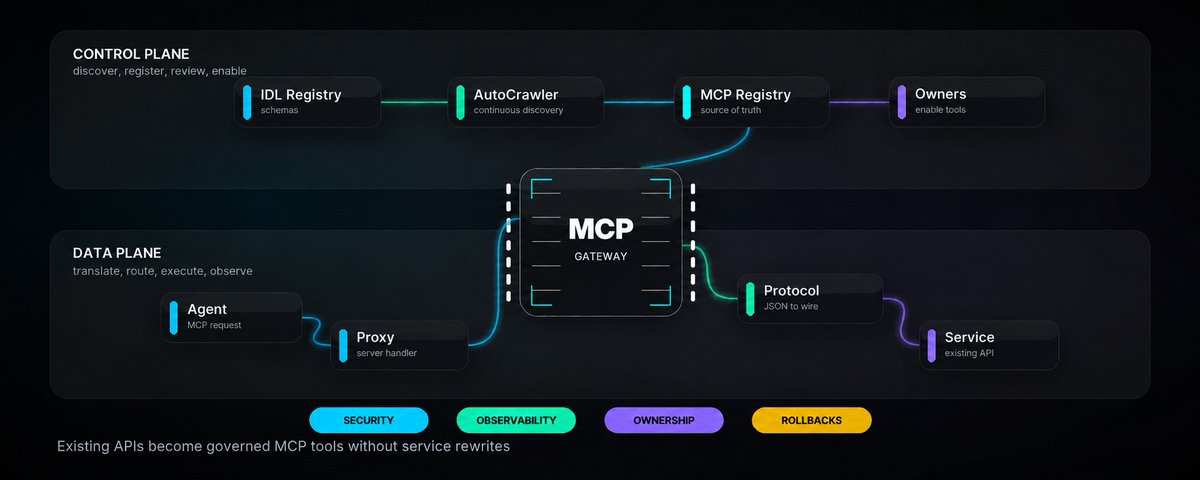
> Extensions: hooks, skills and MCP. SKILL.md is in 9 of 11, MCP in 8
The paper ends with a 90-line harness covering all 7 parts, a solid starting point for your own.
Key pages:
> p.4: the 7-part map
> p.12: the 3 loop types, with Claude Code and Codex as examples
> p.53: why none of them use frameworks or embeddings
> p.67: 18 design recommendations
> p.71: the 90-line harness you can copy


Ishan Gupta retweeted

The idea of an intelligence explosion caused by recursive self improvement has been around for a long time but until very recently it did not seem imminent. Now many leading researchers think it may happen quite soon. You can read our paper about it here:
casp.ac/reports/intelligence…

Ishan Gupta retweeted

Woah, it's a trend now! I love all the infra companies diving deep into the weeds on these things :)

Instinct just got valued at $10 billion, and everybody in sf is building their own
i wrote up a guide on how to not burn money doing it
Ishan Gupta retweeted

Introducing GLiNER2.5-Decide, our new 340M parameter open weight, encoder-based decision model.
GLiNER2.5-Decide is built for fast, deterministic classification. The model evaluates a set of user-defined typed questions and rules, and jointly decodes their answers, returning structured decisions with probability distributions and confidence scores.
We evaluated the model’s performance on Fast Decisions, an unseen, internally generated classification suite based on 17 datasets testing real-world use cases across routing, triage, classification, sentiment, and content understanding.
Measured against similar decision models, GLiNER2.5-Decide leads in 9 of the 17 datasets, achieving the highest average score:
- GLiNER2.5-Decide: 60.1%
- SemIf: 56.4%
- JevK5: 57.5%
- Laya: 46.6%
This performance makes the model a strong fit for use cases like tool calling, model routing, browser and computer use, and LLM-as-a-judge.
GLiNER2.5-Decide’s lightweight encoder architecture makes it easy to fine-tune the model for specific tasks, while being efficient enough to run locally on consumer-grade CPUs or in air-gapped environments, giving users greater control over where their data goes and where the model runs.
To make building and experimenting with GLiNER2.5-Decide as easy as possible, we're also offering hosted inference. You can now use our API to run inference and fine-tune GLiNER models on specialized tasks right inside your own coding agent: agent.fastino.ai
As with previous models, we’re also releasing the model weights on @huggingface under the Apache 2.0 license: huggingface.co/fastino/GLiNE…

Ishan Gupta retweeted

if you're confused about Jev this is 100% worth your time
in fact you should study it


Ishan Gupta retweeted
Build your own harness, folks.
This is absolute banger paper from NVIDIA on self-evolving agent harnesses.
(bookmark it)
They introduce SoL-Pi which cuts token traffic by nearly half.
And it matches its baseline harness on GPT-5.6 Sol and Opus 5.
More details below:
Instead of tuning a harness by hand, they run auto-research loops at the harness layer across many repository-derived and verifier-driven environments, keeping only the mechanisms that survive selection.
Four mechanisms survived:
> Action Fusion changes how actions execute
> Online Context Compact handles compaction during a run
> ObservationPack reshapes observation handling
> Evidence-Preserving Reducer covers delegated reading
On the 51-task EdgeBench evaluation, the savings translate to about a third off API cost. In dollars that is an estimated $8.75 to $13.50 per hour against native Codex and Claude Code harnesses, and $4.36 to $5.71 against the baseline harness.
Because the search runs across many environments rather than one, the retained mechanisms keep working outside the setting that produced them. Code is on GitHub under NVlabs.
Paper: arxiv.org/abs/2609.20519
Chat with Paper: academy.dair.ai/papers/sol-p…

Ishan Gupta retweeted

I put together a handbook on how attention works, from the Q/K/V equation up through how it actually runs in modern LLMs.
Self vs. cross-attention, causal masking, multi-head attention, RoPE, KV caching, MHA/MQA/GQA/MLA, FlashAttention, worked through by hand, with citations back to the original papers.
Made it to be the explanation I wish I'd had.


Ishan Gupta retweeted

A lot of hype around OpenAI's Astra model here on my timeline today. Apparently, this goes back to a new article from The Information, which said Astra is a "recurrent depth or looped transformer".
It's always interesting to read about new or different approaches (including rumors about what the closed labs may be up to), but let's debunk this a bit.
About 2 months ago, I shared the architecture details of Nanbeige, for example, where "Nanbeige4.2-3B is pretrained from scratch on 28T tokens with a Looped Transformer that reuses the layer stack to increase capacity without adding parameters."
Yes, that's it. The looped transformer idea is just reusing layers in the transformer block.
In the case of Nanbeige, the main idea is to reuse the same 22-layer stack (=transformer block) twice instead of once. So, effectively it extends the 22-layer architecture to 44 layers, but without duplicating the weights.
In simple terms, this roughly doubles the size of the model (if we ignore the embedding and output layers for a second). But instead of requiring 2x the storage and RAM to host this model, it stays at the same size since we reuse the components. However, it's almost 2x as expensive in terms of compute, because we run the embedded text through almost 2x as many layers.
Why? In the Nanbeige 4.2 technical report, the researchers found that two passes gave the best trade-off and retained about 75% of the token efficiency of a standard architecture. (More passes gave barely any gains but made the training much slower and much more expensive.)
While, as far as I know, Nanbeige 4.2 is the first notable open-weight model that adopted this approach, the idea goes back to the NeurIPS paper "Mixture-of-recursions: Learning dynamic recursive depths for adaptive token-level computation". Actually, this paper proposes a mechanism that is a bit more sophisticated by adding a learned router that determines whether each token receives one, two, or more passes. So, easy tokens can exit early while harder tokens receive additional computation.
In sum, Astra may be a really good model, but this shouldn't be about this "looped transformer aspect," which is just a tiny architectural tweak.
Also, the statement "the new technique works in a way that obscures some or all of the AI's reasoning, otherwise known as 'chain-of-thought'" is not necessarily true with respect to the looped transformer method. It's possible that The Information journalist refers to some other technique or misunderstood the looped transformer method.
Reusing layers does not by itself suppress visible chain of thought. It adds computation in hidden states before the next token is emitted, just as ordinary transformer layers do.
But based on the information we have, the only plausible interpretation here is that if a model uses more of these recurrent passes, it may need to generate fewer intermediate reasoning tokens. So then more of its computation happens in latent activations that cannot be read as text. But we would get the same effect if we were scaling up the model size, like GPT 5.6 Luna -> GPT 5.6 Sol.

Ishan Gupta retweeted

This is the best site on the internet to learn how LLMs actually work.
Free. Completely.
0xkato.xyz/how-llms-actually…
Bookmark this site.
Then read this ↓


Ishan Gupta retweeted
Why KV cache stores K and V vectors but never Q?
(a popular technical LLM interview question)
LLMs are autoregressive so each token is predicted from every token before it, one at a time.
This autoregressive nature has a direct consequence inside the model.
A forward pass over tokens produces hidden states, but only the last one is projected to logits and is required to generate the next token.
So to understand why KV cache just stores K and V vector, we must back track to see how exactly is the last hidden state produced.
Let's walk through this with a 10-token prompt.
1) Prefill:
All 10 tokens go through the model in one forward pass, in parallel (with causal masking), since the whole prompt is already known.
At every layer, each of the 10 positions produces a query, a key and a value vector, and attention at each position runs against all positions up to it.
This pass is compute-heavy, and it's why the first token takes noticeably longer than the ones after it. TTFT is mostly prefill.
2) The first output token:
To generate the 11th token, only the 10th token's hidden state is needed. So this is projected from the hidden-dim to vocab-dim to generate logits over vocab.
These logits then go through softmax and sampling to generate token 11.
3) Back-track the hidden state:
The last hidden state is the last row of the feedforward block's output. The feedforward block is position-wise (it's applied to each row independently) so that row comes from the last row of the attention output before it.
So now we need to see how the last row of attention is computed.
4) Attention matrix:
QKᵀ for a 10-token prompt will give a 10 × 10 matrix.
Row will have the dot product of query with every key.
Row 10 is therefore Q₁₀·K₁, Q₁₀·K₂, all the way to Q₁₀·K₁₀.
Notice that only Q₁₀ appears in it. Q₁ through Q₉ only belong to their corresponding rows 1-9, and those rows' hidden states we already discarded because they were never needed.
The last row of attention goes through softmax and multiplies the full stack of value vectors, V₁ through V₁₀, to give the last row of the attention output.
So the last hidden state depends on exactly three things: Q₁₀, every key, and every value.
5) Generating token 12:
Token 11 is appended, and this time, we need row 11's hidden state to generate token 12.
Mathematically, attention operation turns out to be Q₁₁ against K₁ through K₁₁, then multiplied by V₁ through V₁₁.
K₁ through K₁₁ and V₁ through V₁₁ are bit-for-bit what prefill + first token produced since under causal masking, a token's key and value depend on that token and the ones before it, never on anything after, so appending token 11 cannot change anything at position 3.
6) The cache state:
Overall, this implies that you just need to retain the keys and values at each decoding step, and compute only the new position's Q, K and V.
Each decode step requires one query vector, which is never used again, so they are never cached across the decoding process.
The visual below explains the entire process.
That said, KV cache is only one of four separate caching layers in an LLM stack.
The other three are prefix caching on the server, prompt caching billed by a provider, and a semantic cache that skips the model entirely.
I wrote a full breakdown of all four caches in LLM serving that you should know as an AI engineer, with code for each.
Read it below.


Ishan Gupta retweeted

当很多公司都在哀嚎 AI 账单贵到用不起,Uber 刚发的这篇技术长文直接把全行业看傻了:
全公司 70% 的代码 PR 全由 Agent 接管,调用量半年狂飙近 10 倍,
但总 AI 账单被死死按在原地一分没涨,单次会话成本硬生生砍掉了 52%,
他们直接把软件工程做成了一座全自动的软件工厂,真的牛逼,
以前是人打开聊天框求 AI 帮一把,
现在 Uber 养了一整支托管 Agent 舰队: 审代码、修挂掉的 CI、分诊报警全是专职 AI 自动上班,
人变成了抽查质检的厂长,每天跑 3 万多次流水线任务
他们最狠的地方,是把 AI 账单拆成了一道极其冷酷的乘法题,
用量可以疯涨,但零价值的废 Token 必须被物理抹杀:
1️⃣ 规划用大脑,干活全用便宜子 Agent:
任务拆解用顶级大模型,具体搬砖的子任务全部默认切给轻量模型,这一招直接成了全厂杠杆最高的开关;
2️⃣ 把 5 分钟缓存改成 1 小时:
工程师去倒杯水开个会回来,上下文缓存依然在,原价 1 折直接续上,40 万 token 强制写摘要压缩,绝不把整本历史无限复印;
3️⃣ 别把一千种工具说明书塞进大脑:
1000 多个内部 MCP 工具统一走网关,模型要用时先搜索再按需挂载,绝不在开局就傻傻灌入 7 万 token 的工具定义;
4️⃣ Code-mode 砍掉话痨轮询:
跑 SQL 和批处理让模型自己写脚本去跑,只交回最终结果,避免一问一答的无效 ping-pong,单项 token 直接暴省 90%;
5️⃣ 2400 万节点知识图谱导航:
给 Agent 发一张包含全公司服务和事故的活地图,以前翻代码盲搜 20 分钟还报错,现在 38 秒精准定位
用量涨不可怕,浪费涨才可怕,
从人机对话迈向托管工厂舰队,大厂把 AI 真正落地的账本,算是彻底算明白了


Ishan Gupta retweeted

Banger paper from Google.
If you maintain a skill library for your agents, you might want to check this out.
(bookmark it)
This work separates three things that skill-evolution systems usually collapse into one. Raw execution traces, a persistent wiki of accumulated knowledge, and the executable skills themselves.
Experience gets consolidated into the wiki, and every later skill update builds on that wiki instead of on a scattered optimization history.
Ablations confirm the wiki is what carries a lot of the gain. Two results stand out in particular. Smaller models with evolved skills beat substantially larger models without them. And skills evolved by one model transfer across families, where skills evolved elsewhere sometimes beat self-evolved ones.
Paper: arxiv.org/abs/2608.27454
Chat with Paper: academy.dair.ai/papers/wikis…

Ishan Gupta retweeted

Everyone's suddenly building company brains.
Nobody agrees on what's inside one. 😵💫
So we opened up 9+ company brains to see how they're actually built.
Every single one does the same four things: getting signals, remembering, dreaming & pruning, speaking & searching.
𝟭. 𝗚𝗕𝗿𝗮𝗶𝗻
Garry Tan's open-source personal brain. Your email and calendar flow into a git repo, and a nightly job re-links everything and flags what's gone stale.
𝟮. 𝗺𝗲𝗺𝟬
A memory library you call from your own code. It only stores what you explicitly tell it to, and ranks fresh facts above idle ones at search time.
𝟯. 𝗟𝗲𝘁𝘁𝗮
For building agents that remember across sessions. The agent decides what's worth keeping, and a second agent tidies up its memory in the background.
𝟰. 𝗭𝗲𝗽 / 𝗚𝗿𝗮𝗽𝗵𝗶𝘁𝗶
A knowledge graph with a clock in it. When a fact changes, the old one gets an end date instead of being overwritten, so you can still ask what was true last March.
𝟱. 𝗦𝘆𝗹𝗽𝗵
A content brain that lives entirely in a git repo. Agents write drafts, humans publish, and afterwards the agent reads your edits to learn what it got wrong.
𝟲. 𝗗𝗜𝗬 (𝗖𝗹𝗮𝘂𝗱𝗲 𝗖𝗼𝗱𝗲 + 𝗴𝗶𝘁)
What most engineering teams actually do. Markdown in the repo, grep instead of search, and pull requests as the only thing keeping it honest.
𝟳. 𝗣𝗹𝗲𝘁𝗼𝗿
A brand brain for marketing teams. Campaigns, assets and performance data in one tree, and the brand rules only move when a human signs off.
𝟴. 𝗚𝗼𝗿𝗴𝗶𝗮𝘀 𝗖𝗼𝗿𝘁𝗲𝘅
Built in-house by an eight-person AI team. 12,000 markdown nodes in GitHub, and every night the questions it got wrong become PRs that fix it.
𝟵. 𝗦𝗹𝗶𝘁𝗲 𝗔𝗴𝗲𝗻𝘁
For teams whose knowledge lives in docs and across sources. It watches ~20 connected tools (Slack, Drive, GitHub, Jira, etc.) for what's gone stale and sends the diff to whoever owns the page. Nothing changes without human approval.
We just launched an interactive ebook with architecture notes from real 149 teams of builders and users, interview insights, and the complete research.
The ebook is free, get it here: slite.com/ebooks/company-bra…
Which brain would you pick? 🧠

Ishan Gupta retweeted

Kubernetes meets LLM inference.
Google, NVIDIA, IBM, and Red Hat are all backing the same open-source project to make it work.
the problem is that LLM inference does not scale the way normal web services do, and the usual Kubernetes answer makes it worse.
let me explain:
run one vLLM or SGLang server and the KV cache is a clean win. the server keeps the attention keys and values for tokens it has already processed, so a prompt that shares a prefix with an earlier one skips past that computation and starts generating.
put a standard Kubernetes Service in front of several replicas and that saving mostly evaporates. the Service hands each request to whichever pod is next in rotation, and that pod usually never saw the prefix, so it recomputes the entire context from scratch.
round-robin assumes every replica serves every request equally well. true for stateless web traffic. false the moment prefill caching exists, because replicas now differ by what they remember.
teaching Kubernetes that difference turns into four problems.
→ knowing which replica holds the prefix. each server streams an event every time it creates or evicts a cache block, and the router keeps a live index of who holds what.
→ knowing when to ignore that index. cache affinity pulls traffic onto warm replicas, so past a load threshold the router drops affinity and picks on load alone. otherwise the warm replica turns into the bottleneck.
→ extending where the cache lives. accelerator memory fills fast, so blocks spill to CPU memory and then disk. on four H100s at 250 concurrent users, that hierarchy delivered 13.9x the throughput of keeping everything on the GPU.
→ separating prefill from decode. prefill is compute-bound, decode is memory-bandwidth-bound, and running both on one replica underuses each. AWS measured up to 70% higher tokens per second after splitting them onto dedicated pools, though the KV cache now has to cross the network before the first token appears.
the KV cache stops being something a single server manages. it becomes cluster state, and the routing layer has to track it.
solve that and you get roughly 3x the output throughput and half the time to first token, on the same hardware, running the same model.
llm-d is the project handling all four on Kubernetes. it sits above vLLM and SGLang rather than replacing them, so you keep whichever engine you already run and it takes over the routing, the cache index, the offloading, and the prefill/decode split. Apache 2.0, CNCF sandbox, with Tesla, Snowflake, Cohere and DigitalOcean running it.
check it out on GitHub: github.com/llm-d/llm-d
i wrote the full breakdown of how inference works underneath all of this. the article is quoted below.


