

26 🇮🇳, MS CS @RITtigers NY 🇺🇸 | Maintainer - @IntuticAI | Ex- @Broadcom @VMware
New York, USA
Joined May 2017
- Tweets9.4K
- Following3.4K
- Followers1K
- Likes19.5K




Ishan Gupta retweeted

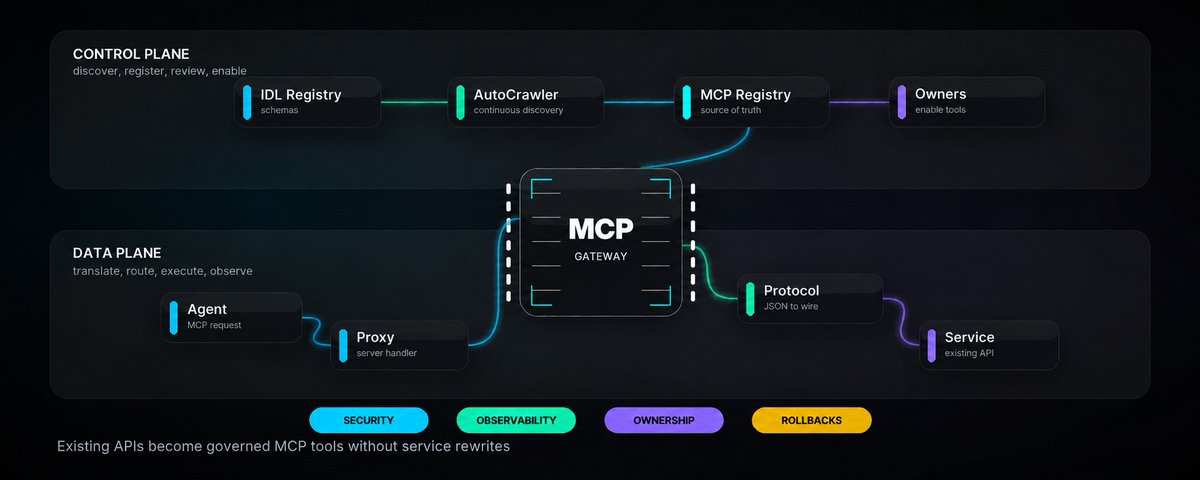
This might be the most useful paper on AI agents this year.
A team at Wavestone AI Lab took apart Claude Code, Codex and 9 more and found the 7-part blueprint every good agent is built on.
Their definition: an agent is a model plus a harness. All 11 agents build the harness from the same 7 parts. Only the size changes.
> Loop: Mini-SWE-Agent is a plain while loop. OpenHands logs every event so a run can be replayed
> LLM layer: one prompt template on one side, 29 provider profiles on the other
> Tools: some agents only have bash, the biggest has 43 typed tools loaded on demand
> Memory: from keep-the-whole-history to notes the agent maintains across sessions
> Safety: from a simple step limit to policy rules plus a reviewer model plus an OS sandbox
> Orchestration: Aider skips sub-agents on purpose, others fork them with their own context
> Extensions: hooks, skills and MCP. SKILL.md is in 9 of 11, MCP in 8
The paper ends with a 90-line harness covering all 7 parts, a solid starting point for your own.
Key pages:
> p.4: the 7-part map
> p.12: the 3 loop types, with Claude Code and Codex as examples
> p.53: why none of them use frameworks or embeddings
> p.67: 18 design recommendations
> p.71: the 90-line harness you can copy


Ishan Gupta retweeted

The idea of an intelligence explosion caused by recursive self improvement has been around for a long time but until very recently it did not seem imminent. Now many leading researchers think it may happen quite soon. You can read our paper about it here:
casp.ac/reports/intelligence…

Ishan Gupta retweeted

Woah, it's a trend now! I love all the infra companies diving deep into the weeds on these things :)

Instinct just got valued at $10 billion, and everybody in sf is building their own
i wrote up a guide on how to not burn money doing it
Ishan Gupta retweeted

Ontology Pipeline — Framework for Knowledge Engineering and Building Knowledge Infrastructures: link.amazon/B06B2xJy5
Amazon description: “One of the biggest shifts happening in our industry is that enterprise data management is expanding into enterprise knowledge management. AI is accelerating that transition because it depends on more than well-managed data. It depends upon context, shared meaning, trusted relationships, and the ability to organize the vast stores of unstructured knowledge that exist across every large enterprise. As AI becomes the primary interface to enterprise information, knowledge management will become the foundation that unlocks trustworthy AI at scale.”


Ishan Gupta retweeted
Top 12 agentic use cases for Jev:
(bookmark this)
Jev handles semantic decisions that ordinary code cannot express reliably. It returns typed answers and probabilities, while code continues to cover the workflow.
Here are 12 practical use cases for Jev:
1. Browser next action
> Convert the current DOM state into a bounded action such as click, type, or stop. Code executes only valid operation-target pairs. There are already several open-source Jev web agents.
2. Context compaction
> Decide which events from a long agent trace should remain. The selected text stays verbatim instead of being replaced with a generated summary.
3. Skill and context loading
> Compare the current user turn against the available skills. Load only the instructions needed for that turn instead of filling the context window with every skill.
4. Typed tool-call compilation
> Map a natural-language request to a function and fill its typed arguments. Each argument is evaluated separately before code allows execution.
5. Citation verification
> Check whether a quoted passage exists and whether the surrounding evidence supports the claim. The output can be supported, unsupported, or contradicted.
6. Extraction verification
> Run a cheap extractor first, then use Jev to verify questionable fields. Clean records stay on the fast path while uncertain ones reach a reasoning model.
7. Agent trace evaluation
> Turn raw trajectories into queryable labels such as progress and repetition. This avoids asking another LLM to write a full review of every run.
8. Semantic regression tests
> Replay a trace suite against a new agent build. Semantic checks can then pass or block prompt, model, tool, and policy changes in CI.
9. Jevgrep code search
> Search a codebase by what the code does rather than its exact words. Jev scores candidate snippets and returns the most relevant code first.
10. Entity alignment
> Compare two candidate records and decide whether to merge, review, or keep them separate. Candidate generation remains deterministic while Jev handles semantic identity.
11. Retrieval reranking
> Let embeddings retrieve a broad candidate set, then use Jev to reorder passages by relevance. The generation model receives the most useful evidence first.
12. Memory promotion gate
> Capture a completed agent trace, then judge whether its corrections contain a reusable lesson. Trace-backed lessons can be promoted while task-specific noise is discarded.
If you want to see the final pattern in practice, it is already implemented in the Beacon open-source project.
Beacon captures full sessions across Claude Code, Codex, Cursor, OpenCode, and 20+ agent harnesses, and then Jev identifies which workflows and corrections are worth learning from, so that a lesson discovered by one agent can become available to the others.
GitHub repo: github.com/Asymptote-Labs/ag…
(don’t forget to star it ⭐)
If you want to dive deeper, I also wrote about a similar mechanism in a hands-on guide. It covers building a Jev-style decision path with open models, entirely locally.
Read it below.

Ishan Gupta retweeted

Harvard has put one of the best AI systems curriculums I’ve seen online for free.
CS249r goes well beyond model architecture. It gets into the engineering that decides whether a model can actually be trained and served efficiently: processors, memory hierarchy, data movement, accelerators, distributed computation, inference, quantization, serving, reliability and deployment.
And there is much more than a textbook.
The material includes two open-access ML Systems volumes, TinyTorch for building an ML framework from scratch, interactive browser labs, MLSys·im for experimenting with hardware and infrastructure bottlenecks, StaffML for systems practice, and the lecture slides used for teaching the course.
TinyTorch alone has 20 progressive modules. The labs let you change system parameters and see what becomes the bottleneck instead of only reading about it.
This is the material I’d study after getting comfortable with neural networks and Transformers.
Knowing how attention works is useful. Knowing why KV cache consumes memory, when inference becomes bandwidth-bound, why batching changes throughput, and why adding more GPUs eventually stops scaling is a different skill.
Everything is here: mlsysbook.ai/
GitHub: github.com/harvard-edge/cs24…

Ishan Gupta retweeted

AI memory is getting f...cking illegal
10 open-source GitHub projects that stop agents from starting from zero EVERY new session
01 Mem0
▸ github.com/mem0ai/mem0
→ 66K+ stars
02 Hindsight
▸ github.com/vectorize-io/hind…
→ retain → recall → reflect
03 memU
▸ github.com/NevaMind-AI/memU
TURN MEMORY INTO KNOWLEDGE
04 Cognee
▸ github.com/topoteretes/cogne…
→ documents + code + conversations → knowledge graph
05 Graphiti
▸ github.com/getzep/graphiti
→ remembers how facts change over time
06 OpenViking
▸ github.com/volcengine/OpenVi…
MAKE THE AGENT STATEFUL
07 Letta
▸ github.com/letta-ai/letta
→ memory + identity across sessions
08 Letta Code
▸ github.com/letta-ai/letta-co…
REMEMBER ACROSS THE STACK
09 OpenMemory
▸ github.com/mem0ai/openmemory
10 Agent Memory Benchmark
▸ github.com/vectorize-io/agen…
the loop:
experience → remember → connect → retrieve → act → update
3 builds I'd actually test:
coding:
Hindsight → Cognee → Letta Code
personal agent:
Mem0 → Graphiti → Letta
company brain:
Cognee → Graphiti → Hindsight
and this is where the sh...t gets interesting:
bigger context isn't the same as memory
a model can hold 1M tokens and still meet you for the first time every morning
these projects change that
save this before your agent forgets it ⭣


Ishan Gupta retweeted
retrieval is a decision problem, not just a similarity problem
cool experiment from @assaf_elovic swapping embeddings for Jev in GPT Researcher - 73% vs 46% relevant context
decision models will show up all over the harness
xitter.cf/assaf_elovic/status/21…

Didn't expect this 🤯
We replaced embeddings with Jev in GPT Researcher's RAG pipeline and tested both on 28 research tasks from SimpleQA and open ended research.
Jev beat embeddings on every quality measure we ran:
- 59% more relevant context (73% vs 46%)
- Reports preferred 15 to 3 in blind comparisons
- Same cost per report
GPT Researcher now runs on Jev by default, and no longer needs embeddings at all.
All you need is @LangChain + @tavilyai +Jev for the perfect RAG system.
Check out the repo here: github.com/assafelovic/gpt-r…
Research: docs.gptr.dev/docs/gpt-resea…


Ishan Gupta retweeted

Brilliant paper from CMU.
If you use Jev/LLM-as-judge, this one is for you.
(bookmark it)
We use LLMs to generate answers, then use another LLM to judge them.
But many evaluations only need a bounded decision.
- Was the answer grounded?
- Did it follow the instruction?
- Which response was better?
This Carnegie Mellon University paper tests whether Jev can make these decisions cheaply, then identifies the cases that need a stronger judge.
The results reveal Jev’s real edge.
→ Jev works well on focused judgments
On ordinary response preferences, evidence-grounded factuality, and final-answer checks, Jev remained within three percentage points of the strongest judge tested.
→ The cost difference is substantial
On the paper’s matched workload, Jev cost only 0.36 percent of the strongest comparator’s fee.
This makes it practical to evaluate more agent responses, across more criteria, without scaling the evaluation bill at the same rate.
→ Confidence becomes a routing mechanism
Jev returns a decision and label probabilities.
When confidence is high, accept its decision. When confidence is low, escalate the case to a stronger LLM.
A frozen version of this cascade retained about 99 percent of GPT-6’s accuracy while using roughly 57 percent of its fee.
→ Jev still has a clear boundary
It fell behind when evaluation required checking complex derivations or resisting an elaborately written wrong answer.
It also struggled with factuality judgments when no reference evidence was provided. In those cases, confidence did not reliably expose the errors.
So the paper is not arguing that Jev should replace every LLM judge.
It presents a more useful architecture.
Code handles exact rules. Jev handles focused semantic judgments. Stronger models or humans handle uncertain and reasoning-heavy cases.
That is also the idea behind the workflow I built.
The agent generates an answer. Jev judges bounded claims against the supplied evidence. Uncertain cases move to review. Opik records the traces, scores, and experiment results.
The paper explains why this architecture works.
My article shows how to build it.
The full implementation breakdown is quoted below.


Ishan Gupta retweeted

斯坦福大学课程 CS329A: Self-Improving AI Agents
斯坦福大学 @achowdhery @Azaliamirh 两位老师主讲,他们在 Google Brain / Deepmind 有过合作经历,现在合作连续两年讲授 AI Agents 课程。
分享这门课程后,类似获得了超过 5K+ 点赞和收藏,看到很多朋友喜欢,我也把 9 个视频做了一个预告视频,让大家对课程可以更快有更直观的感受。
虽然 AI Agent 已经强大到很多人觉得不需要再学习,什么问题都可以直接问,到顶级大学的基础课程,系统学习下来,还是会很有收获,全局认知的提升。 马上长假了,收藏学起来!
课程主页: cs329a.stanford.edu
视频列表: youtube.com/playlist?list=PL…

斯坦福大学课程 CS329A: Self-Improving AI Agents
课程 9 讲视频都已发布在 Youtube,第 1 讲 52 万观看,第 9 讲 1.5 万。趁假期坚持看完 9 讲视频,你就超过了中间的 50 多万人,和连第 1 讲都没看过的无数人 😂
开玩笑,虽然 AI Agent 已经强大到很多人觉得不需要再学习,什么问题都可以直接问,到顶级大学的基础课程,系统学习下来,还是会很有收获,全局认知的提升。
课程主页:
cs329a.stanford.edu/
视频列表:
youtube.com/playlist?list=PL…

Ishan Gupta retweeted

The entire RAG industry is about to get cooked.
Researchers developed a new RAG approach that bypasses almost everything traditional RAG depends on.
- No vector DB
- No data embeddings
- No chunking
- No similarity search
It's called PageIndex.
Instead of splitting your documents into chunks and loading them into Pinecone, it creates a tree index that lets the LLM reason through them like a human reading a book.
98.7% on FinanceBench. Outperforms every vector RAG on the leaderboard.
100% free. Open source.

Ishan Gupta retweeted

Introducing GLiNER2.5-Decide, our new 340M parameter open weight, encoder-based decision model.
GLiNER2.5-Decide is built for fast, deterministic classification. The model evaluates a set of user-defined typed questions and rules, and jointly decodes their answers, returning structured decisions with probability distributions and confidence scores.
We evaluated the model’s performance on Fast Decisions, an unseen, internally generated classification suite based on 17 datasets testing real-world use cases across routing, triage, classification, sentiment, and content understanding.
Measured against similar decision models, GLiNER2.5-Decide leads in 9 of the 17 datasets, achieving the highest average score:
- GLiNER2.5-Decide: 60.1%
- SemIf: 56.4%
- JevK5: 57.5%
- Laya: 46.6%
This performance makes the model a strong fit for use cases like tool calling, model routing, browser and computer use, and LLM-as-a-judge.
GLiNER2.5-Decide’s lightweight encoder architecture makes it easy to fine-tune the model for specific tasks, while being efficient enough to run locally on consumer-grade CPUs or in air-gapped environments, giving users greater control over where their data goes and where the model runs.
To make building and experimenting with GLiNER2.5-Decide as easy as possible, we're also offering hosted inference. You can now use our API to run inference and fine-tune GLiNER models on specialized tasks right inside your own coding agent: agent.fastino.ai
As with previous models, we’re also releasing the model weights on @huggingface under the Apache 2.0 license: huggingface.co/fastino/GLiNE…

Ishan Gupta retweeted

if you're confused about Jev this is 100% worth your time
in fact you should study it


Ishan Gupta retweeted

Build your own harness, folks.
This is absolute banger paper from NVIDIA on self-evolving agent harnesses.
(bookmark it)
They introduce SoL-Pi which cuts token traffic by nearly half.
And it matches its baseline harness on GPT-5.6 Sol and Opus 5.
More details below:
Instead of tuning a harness by hand, they run auto-research loops at the harness layer across many repository-derived and verifier-driven environments, keeping only the mechanisms that survive selection.
Four mechanisms survived:
> Action Fusion changes how actions execute
> Online Context Compact handles compaction during a run
> ObservationPack reshapes observation handling
> Evidence-Preserving Reducer covers delegated reading
On the 51-task EdgeBench evaluation, the savings translate to about a third off API cost. In dollars that is an estimated $8.75 to $13.50 per hour against native Codex and Claude Code harnesses, and $4.36 to $5.71 against the baseline harness.
Because the search runs across many environments rather than one, the retained mechanisms keep working outside the setting that produced them. Code is on GitHub under NVlabs.
Paper: arxiv.org/abs/2609.20519
Chat with Paper: academy.dair.ai/papers/sol-p…

Ishan Gupta retweeted
I put together a handbook on how attention works, from the Q/K/V equation up through how it actually runs in modern LLMs.
Self vs. cross-attention, causal masking, multi-head attention, RoPE, KV caching, MHA/MQA/GQA/MLA, FlashAttention, worked through by hand, with citations back to the original papers.
Made it to be the explanation I wish I'd had.
