

phd-ing @csatusc on theoretical foundations of LLMs | alum @uchicago, B.S. '20 | student researcher @googleresearch | prev research intern @metaai
Los Angeles
Joined November 2020
- Tweets346
- Following1K
- Followers1.1K
- Likes1K


Deqing Fu retweeted

I’ll be at NeurIPS 2026 in Atlanta, Dec 9–13! Looking forward to catching up with friends, meeting new people, and chatting about exciting ideas. Hope to see you there! 🚀

Excited to share Economy of Minds (EoM), where simple local incentives give rise to emergent coordination, specialization, and self-improvement — no central manager needed! 💰🤖
We’ll be presenting this work at NeurIPS 2026 #NeurIPS2026 at the Atlanta 🧜 site! 🎉 Come chat with us about Economy of Minds, multi-agent systems, emergent intelligence, and what it takes to build self-organizing societies of AI agents!
Deqing Fu retweeted

Introducing 𝗚𝗨𝗜𝗗𝗘, my summer work at @GoogleDeepMind
𝗖𝗮𝗻 𝗟𝗟𝗠𝘀 𝗹𝗲𝗮𝗿𝗻 𝘁𝗼 𝗳𝗮𝗰𝗶𝗹𝗶𝘁𝗮𝘁𝗲 𝗵𝘂𝗺𝗮𝗻 𝗴𝗿𝗼𝘂𝗽 𝗰𝗼𝗻𝘃𝗲𝗿𝘀𝗮𝘁𝗶𝗼𝗻𝘀 𝗮𝗰𝗿𝗼𝘀𝘀 𝗱𝗶𝘃𝗲𝗿𝘀𝗲 𝗱𝗼𝗺𝗮𝗶𝗻𝘀—𝘄𝗶𝘁𝗵𝗼𝘂𝘁 𝗺𝗮𝗻𝘂𝗮𝗹𝗹𝘆 𝗱𝗲𝘀𝗶𝗴𝗻𝗲𝗱 𝘀𝘁𝗿𝗮𝘁𝗲𝗴𝗶𝗲𝘀? 🤔
💡 𝗧𝗵𝗲 𝗖𝗵𝗮𝗹𝗹𝗲𝗻𝗴𝗲
Good facilitation goes beyond task success. It should also improve 𝗵𝘂𝗺𝗮𝗻 𝗲𝘅𝗽𝗲𝗿𝗶𝗲𝗻𝗰𝗲 and promote 𝗳𝗮𝗶𝗿𝗻𝗲𝘀𝘀, ensuring that everyone feels heard, comfortable, and respected.
We study three settings: open-ended discussions, consensus-building, and negotiation.
🔧 𝗢𝘂𝗿 𝗔𝗽𝗽𝗿𝗼𝗮𝗰𝗵
Rather than manually engineering task-specific strategies, GUIDE learns a 𝗴𝗲𝗻𝗲𝗿𝗮𝗹𝗶𝘇𝗮𝗯𝗹𝗲 𝗳𝗮𝗰𝗶𝗹𝗶𝘁𝗮𝘁𝗶𝗼𝗻 𝗽𝗹𝗮𝘆𝗯𝗼𝗼𝗸 from 432 real human conversations, iteratively refining it through reflection and human-aligned LLM evaluation.
📊 𝗞𝗲𝘆 𝗙𝗶𝗻𝗱𝗶𝗻𝗴𝘀
🏆 𝟲𝟭.𝟰% offline win rate against task-specific expert facilitators.
🤝 Across 𝟰𝟲𝟮 live conversations, GUIDE improves speaking comfort, reduces interpersonal friction, and promotes more equitable experiences, while maintaining comparable task outcomes.
💬 𝗟𝗲𝘀𝘀 𝗶𝘀 𝗺𝗼𝗿𝗲: 𝟮𝟰.𝟳% fewer interventions and 𝟮𝟵.𝟬% fewer words!
Huge thanks to my amazing collaborators and mentors @tzushengkuo @Jiale_Leo @DeqingFu @Nithum and Crystal Qian!
📄 Paper: arxiv.org/abs/2610.16231
#GoogleDeepMind #LLM #HumanAIInteraction #SocialIntelligence #AIResearch

📄 Paper: arxiv.org/abs/2610.19725
A more efficient 2.0 is on the way.
This is the work lead mainly by Haoxin Liu (linkedin.com/in/haoxin-liu-0…)!

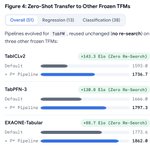
Same lesson for tabular and time series: keep the FM frozen, let an agent own the deployment.
It's time for the second half of TSFMs: agentic deployment that adapts them to the real world, rather than expecting frozen models to handle everything alone.

TimeRSI: a coding agent wraps a frozen forecasting model, turns domain knowledge + data insights into executable pipelines, and uses online forecast feedback to keep improving as conditions change.
The TSFM stays frozen. The deployment makes it smarter.
TSFMs give strong zero-shot forecasts and save a lot of modeling effort.
But deployment takes more than numbers: domain knowledge, insights from the data, and the ability to improve when forecasts go wrong.
Until now, that meant plain inference or ongoing human expertise.

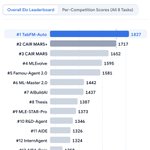
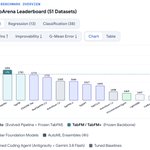
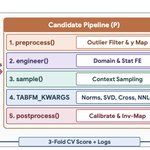
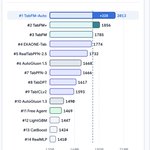
TabFM-Auto (xitter.cf/DeqingFu/status/210518…) showed that a coding agent evolving the pipeline around a frozen tabular FM can beat the field.
Time-series foundation models need a harness, too. 🚀
Introducing TimeRSI: a self-improving agentic deployment system for TSFMs 🧵
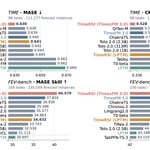
With TimeRSI, TimesFM-3.0 returns to #1 on TIME🏆 and FEV-bench🏆 as of Oct15.


Introducing TabFM-Auto, my summer project at @GoogleResearch .
LLMs possess rich world knowledge yet bad at handling massive tables with millions of number cells.
Tabular Foundation Models are so good at tabular in-context learning but don't have semantic knowledges.

Deqing Fu retweeted

Excited to share PreciseCoder, a natural next step from our Precise Debugging Benchmark. PDB showed that coding models can pass tests while making many unnecessary edits. This time, we asked: can we train them to fix the bug and leave working code alone?
precise-coder-rl.github.io/
We found a tension in the usual training recipe.
(1) Unit-test rewards care whether the final program passes, regardless of what changed.
(2) Simply penalizing edit size tends to shrink patches at the cost of pass rate.
PreciseCoder instead pairs test success with a reward that verifies proposed edits against reference faults. On PDB, our 4B model cuts edits from 14 to 3 lines per task at the same pass rate. The gains carry over to harder, repository-level and agentic debugging.
The finding I’m most excited about is weak-to-strong transfer: give the reasoning trace of our 9B model to a stronger model, and its edit precision improves by 4.6–12.4 points without further training. Our analysis of those reasoning traces offers a clue: PreciseCoder more often names the buggy line and reasons about whether a change is needed.
Proud of @zhanyunkai and the whole team for this work! ✂️


Stop letting your coding agents BLOW UP your codebase. 💥
Only 62% of the lines GPT-5.6 Sol edits are actually needed when debugging on PDB;
DeepSeek-V4.1-Flash changes 60% of already-correct code and breaks 22% of it.
A big reason is RL with unit-test rewards; it checks whether the code passes, never what you changed.
Introducing our new paper, PreciseCoder: Faithful and Generalizable Debugging Beyond Unit-Test Rewards
✂️ 14 → 3 edited lines per task at the same pass rate
🛡️ leaves correct code untouched 2x as often
🌍 generalizes to complex debugging and agentic coding tasks
🧠 teaches frontier models to edit more precisely
precise-coder-rl.github.io
(1/11)
Tired of coding agents rewriting your entire codebase every time you ask them to fix one tiny bug? check out PreciseCoder at precise-coder-rl.github.io/
Stop letting your coding agents BLOW UP your codebase. 💥
Only 62% of the lines GPT-5.6 Sol edits are actually needed when debugging on PDB;
DeepSeek-V4.1-Flash changes 60% of already-correct code and breaks 22% of it.
A big reason is RL with unit-test rewards; it checks whether the code passes, never what you changed.
Introducing our new paper, PreciseCoder: Faithful and Generalizable Debugging Beyond Unit-Test Rewards
✂️ 14 → 3 edited lines per task at the same pass rate
🛡️ leaves correct code untouched 2x as often
🌍 generalizes to complex debugging and agentic coding tasks
🧠 teaches frontier models to edit more precisely
precise-coder-rl.github.io
(1/11)
Deqing Fu retweeted
A very overdue life update: came across my graduation photos and realized I never shared them!
I finished my PhD at @CSatUSC ! 🎓 So grateful to my advisors @robinomial and @_jessethomason_ for all their guidance and support, and to my partner for being there through all the ups and downs. ❤️
I’ve since joined @UCBerkeley as a postdoc, working with @serinachang5! 🐻


Deqing Fu retweeted

Can a unified multimodal model (UMM) teach itself, with its text and visual abilities making training data for each other?
Yes: over 4 rounds, a 7B model climbs 45.7% → 60.2%, vs. 46.3% for continued training.
🧵 1/10
Deqing Fu retweeted

What's the role of small-scale research in the era of massive models? Tell us where you stand and help decide what the @MOSS_workshop panel debates at #COLM2026 by voting on the poll below! 🌱

Help us shape the panel at MOSS @COLM_conf !
We've put together a quick poll. Questions with the most split opinions will become panel discussion topics.
Vote: form.typeform.com/to/UOyzADc…
See more info on our website: sites.google.com/view/moss-c…
Come and talk with Harvey at COLM! If you know any spring/summer opportunities, please DM him as well!!!

I’ll be at #COLM2026 next week, presenting our work on effective KV-cache eviction at the Efficient Reasoning Workshop on Oct 9, 12:30–13:30.
I work on LLM capabilities, efficient reasoning, and evaluation, and would be happy to chat with anyone working on related problems!
I’m also looking for Spring/Summer 2027 internships. Feel free to DM me if you think I'd be a good fit.
Deqing Fu retweeted

I’ll be at #COLM2026 next week, presenting our work on effective KV-cache eviction at the Efficient Reasoning Workshop on Oct 9, 12:30–13:30.
I work on LLM capabilities, efficient reasoning, and evaluation, and would be happy to chat with anyone working on related problems!
I’m also looking for Spring/Summer 2027 internships. Feel free to DM me if you think I'd be a good fit.

Deqing Fu retweeted

I’ll be at #COLM2026!! I’m excited to talk about (long-horizon) human–AI interaction, personalization, and multi-turn policies (and sf bakeries 😭)
Alsooo, I’m on the job market and looking for postdoc/research roles in related areas! I’d also love to chat if you’re hiring :)
Deqing Fu retweeted

I'll be at COLM next week! I'll present my work on the fragility of self-improving agents at the Lifelong Agents workshop (Friday 10-11am).
If you work on self-improving agents, especially on how to evaluate them, oversee them, and make them safe, I'd love to chat! ☕

ALT https://arxiv.org/abs/2608.18066
Deqing Fu retweeted

🔬 What do auto-research agents actually do differently from top human researchers?
Despite all the excitement around auto-research agents / RSI, we still lack lack a clear picture of how they approach research tasks and how their strategies differ from those of expert humans.
We introduce TraceML, a tool for trajectory-level analysis of agents and systematic agent-human comparisons.
We compare Codex agents with Kaggle Grandmasters and uncover clear differences in their research strategies. For example, humans draw on a broader set of research skills, while agents tend to concentrate on a narrower subset.
Even more interestingly, we distill the human research skills uncovered by TraceML back into Codex agents and find that they can substantially improve final outcomes!
🚀 TraceML will be presented at NeurIPS 2026 E&D!
More results in the thread ↓
jerryyan123.github.io/TraceM…


Auto-research agents run ML experiments all night, but the leaderboard only shows where they end up. TraceML shows how they got there: 4,465 human and 207 agent Kaggle trajectories, labeled. Accepted at #NeurIPS2026 E&D Track and #COLM Workshop🎉
🔗jerryyan123.github.io/TraceM…
