






So intelligence got twice cheaper (and better) in about ~1 month?

🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4


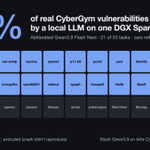
On Artificial Analysis's CyberGym benchmark, Qwen3.8 refuses every task. 100% safety blocks.
I removed the refusals and ran it locally on one Spark against real memory-safety bugs.
It fixed 64% of them and refused none.

Full details here chetvil.com/qwen-abliterated…

Internal models are available *weeks* before launch, not like some retards were suggesting that people inside live 2 generations of models above everyone else.

Some findings based on Anthropic’s published plot:
- The share of merges on weekends rose steadily from 7% to 18% (+0.33 pts/week). Monday–Wednesday declined the most, Thursday slightly, and Friday held steady.
- The time to double the number of daily merges shortened from 67 days (Jan – May) to 41 days (May – Jul) to 20 days (Aug – Sep)
- Merge growth sped up about 5 weeks before Mythos Preview and Opus 4.7, and again before Opus 5.5 and Sonnet 5.5. That could mean the models were available internally weeks before launch.


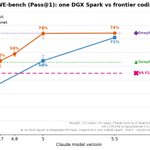
Qwen3.8-flash-next seems to be the best fit for 1 DGX spark currently. Also supports multiple parallel flows which can do 100+ tok/s. I'm running DeepSWE now and will report results once done.

It is NFP4 quant and full results are here: chetvil.com/qwen3-8-flash-ne…

If you ever wondered if Jev can improve coding performance of the models - it can't.
Results are here chetvil.com/can-a-decision-m…


Full results of the local run are here: chetvil.com/deepseek-full-de…


Next step: make ant and OpenAI pay few tens of $M to get whitelisted for figma MCP

I for one is happy that glm-5.3 is open source and everyone can learn adapt and harden their infrastructure, not whatever is anthropic trying to position here anthropic.com/research/glm-5…


Started full DeepSWE run with excellent @MiaAI_lab EXL3 quant of DeepSeek-0731. I think it is the best coding model for 1 Spark.
Currently about 20 tasks in and 53% success rate. And DeepSWE is hard!
Full results updated daily here chetvil.com/deepseek-full-de…
I ran a few experiments to see how capable Deepseek Flash could be on one DGX Spark and compared to a few OpenAI/Anthropic models.
Surprisingly quite good - see full analysis here chetvil.com/deepseek-v4-flas…
kudos @MiaAI_lab for the ELX3 recipe.

Ran Qwen3.8-27B official FP8 on a DGX Spark (SGLang) as local Claude Code, trying to match the card’s DeepSWE 42.2. One meriyah task. Spec decode: DFlash2, then DSpark. The stack worked. The score didn’t reproduce, timed out every time
Short-prompt DSpark hit ~49 tok/s. Long Claude Code thinks at 60–150k context were ~12 tok/s on both DFlash2 and DSpark.
Those 34–40 tok/s Spark posts are NVFP4 + DSpark on code/math. Spec decode does not like 8k-token research dumps.
Last, I want to say really big THANK YOU to our amazing team, real SWAT team which can build anything with whatever level of complexity.
And of course @ilyaf and @kleinerperkins for your unwavering support along with other amazing investors @nyca @AbstractVC .
