NLP research - PhD student @uwcse

Joined June 2017
🤖➡️📉 Post-training made LLMs better at chat and reasoning—but worse at distributional alignment, diversity, and sometimes even steering(!) We measure this with our new resource (Spectrum Suite) and introduce Spectrum Tuning (method) to bring them back into our models! 🌈 1/🧵
5
49
3
194
69,675
✨EMNLP Paper! ✨ Have you ever constructed a table to organize your lit review process? Can we use LMs to generate these automatically? We are excited to present ArxivDIGESTables 🍽️ a study of collecting, generating, and evaluating 🎓 scientific literature review tables 📃!
1
16
3
77
17,790
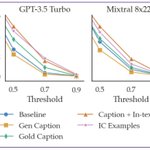
We also find that providing more table context (captions, in-text references) to models leads to higher recall when generating columns but does not help when generating values.
1
1
1
294
I've started thinking about what I want to do after my postdoc at AI2 💫 If you know of an academic department or industry team where I might be a good fit, please reach out! 👩‍💻 NLP, cultural analytics, healthcare, narratives, online communities 🌎 maria-antoniak.github.io/
51
6
195
38,795
I'm on the faculty market! My goal is to build language systems that we understand deeply through discovery and by design, so we can precisely control them and treat their failures. Let's tackle this grand challenge of science and engineering together. nlp.stanford.edu/~johnhew/
6
72
3
404
97,037
If you missed our demo at #emnlp2023 this week, you can now play with PaperMage yourself and explore how you can easily access PDF documents using Python for your future projects: (1/5)
1
9
1
28
6,489
Ben Newman retweeted
so happy to have our work recognized at #emnlp2023 🥳 big thanks to @shannonzshen @blnewm @josephcc @soldni and collaborators at @SemanticScholar @allen_ai @UCBerkeley @MIT two of my favorite aspects of this work:
7
15
1
104
20,324
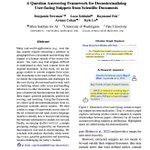
Hello! We will be presenting our poster on 📃 scientific decontextualization🎓 at #EMNLP2023 TODAY (12/9) at 11am in the east foyer! This is work with @soldni, @rayrayfok @armancohan, and @kylelostat, conducted at @SemanticScholar/@allen_ai
1
5
2
36
8,088
We propose a QA-based decontextualization framework with three stages: 1️⃣ Question Generation: identify clarifying questions 2️⃣ Question Answering: find evidence from the paper and cited papers. 3️⃣ Rewriting: Incorporate the answers in the snippets, which are now decontextualized
1
2
139
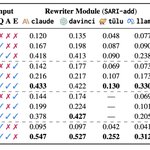
We find our framework helps annotators when collecting data. ✅ And it leads to LLM pipelines based that improve over end-to-end baselines. ✅ Findings: open models underperform closed ones, and that QG and QA are the most challenging. Link: arxiv.org/abs/2305.14772
1
121
multimodal PDF processing is painful but doesn’t have to! come to our demo at #EMNLP2023 of Papermage, a library for fast manipulation of PDFs (Friday 9/12 @ 9am) we have used it for LLM data cleanup, paper QA, HCI prototypes github.com/allenai/papermage aclanthology.org/2023.emnlp-…
7
45
4
304
33,310