
Computer science prof, entrepreneur & leader at Ai2. Excited by AI for science, human-AI interaction, and Web-scale NLP.
Seattle, WA
Joined March 2009
- Tweets1K
- Following273
- Followers2.8K
- Likes1.2K






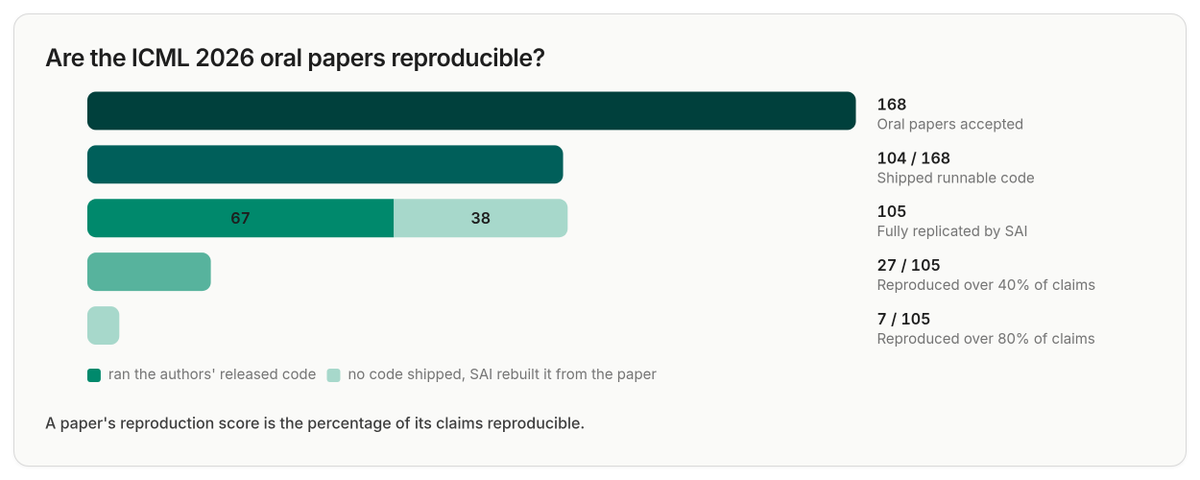
This benchmark for Ai scientific capabilities is beautifully thought out - I especially like it's clear enumeration of design principles...


Daniel Weld retweeted

We built MolmoWeb from the scratch with Molmo2!!! 💕🌐
It’s not easy to build SOTA web agents out of open source VLMs, when they can be so profitable that very few projects release everything (if anything), esp the datasets 🔑
But, we just released all the MolmoWeb model checkpoints and datasets from ai2😉
Can’t wait to see what the community builds on top of MolmoWeb!🫡

Daniel Weld retweeted

🔎 Deep research agents like Asta ScholarQA and OpenAI Deep Research are transforming how we perform literature review.
But how do we know if the way we evaluate them is actually meaningful?
Announcing our new paper: “Deep Research, Shallow Evaluation: A Case Study in Meta-Evaluation for Long-Form QA Benchmarks” 🧵
Daniel Weld retweeted

Are you a researcher in CS or a CS-adjacent field curious about how an AI agent can help you with your research project? Want to try a new tool for your research support in a paid user study ($100, 2 hr)? Limited spot numbers. See details and sign up here: forms.gle/JzLtkAhe7TtvuiwQ8


Truly open scientific question answering - that's good!
science.org/content/article/…

Daniel Weld retweeted
We’re releasing the Theorizer code and framework + a dataset of ~3,000 theories generated by Theorizer across the field of AI/NLP, built from 13,744 source papers.
💻 Code: github.com/allenai/asta-theo…
📝 Technical report: arxiv.org/abs/2601.16282
✍️ Learn more in our blog: allenai.org/blog/theorizer

I'm so excited by this! Our system is generating some insightful & novel theories (e.g., internally for LM post-training). And it's still getting better!

Daniel Weld retweeted
Introducing Ai2 Open Coding Agents—starting with SERA, our first-ever coding models. Fast, accessible agents (8B–32B) that adapt to any repo, including private codebases. Train a powerful specialized agent for as little as ~$400, & it works with Claude Code out of the box. 🧵

Smart analysis analysis of scholar output when authors adopted LLMs as part of their writing: 1) huge 36% boost in # papers published 2) LLMs mitigate skill disparities, eg native language - enough to shift market share of production toward China bit.ly/4qliJGo @yian_yin

Daniel Weld retweeted
🧠 Introducing NeuroDiscoveryBench. Built with @AllenInstitute, it’s the first benchmark for evaluating AI systems like our Asta DataVoyager agent on neuroscience data. The benchmark tests whether AI can truly extract insights from complex brain datasets.

Daniel Weld retweeted

#NeurIPS2025 and AI x Science?
Some fun announcements are coming up. Stay tuned.
Also, our Asta internship application is still open -- apply and mention my name if you'd like to work w me ~

🎀 Really excited to start cadence for 2026!
At @allen_ai, we are at the intersection of AI making a real impact in accelerating science, with several serious collaborations with domain scientists (Economics, Oncology, Neuroscience, Climate, Epidemiology).
If you are passionate about turning the stack upside down to break and build current LLMs to be adaptive for a continual discovery process, join us!
If you are interested in my work, such as data-driven discovery, open-ended hypothesis search, test-time adoption for hypothesis generation, causal mechanism discovery using data and literature, mention my name in your application!
Past interns might vouch for their experiences, but working with Asta interns for the last two years has been one of my most rewarding journeys at Ai2! 🩷


Daniel Weld retweeted
Plenty of AI-gen papers in ICLR. Wonder why?
🚨 In a preregistered Randomized Controlled Trial, we find: CS authors perceive AI-abstracts as more readable, tend to edit less than their published counterparts. AI-use and its disclosure shape the fabric of collaborative scientific writing.
Work led by @hsanchaita & @leadoeun27, advised by @shocheen & yours truly.
1/n

Impressive deep-research performance by a tiny & open model!

🔥Thrilled to introduce DR Tulu-8B, an open long-form Deep Research model that matches OpenAI DR 💪Yes, just 8B! 🚀
The secret? We present Reinforcement Learning with Evolving Rubrics (RLER) for long-form non-verifiable DR tasks! Our rubrics:
- co-evolve with the policy model
- are grounded on search knowledge
🧵

The benchmark desiderata alone make this paper worth a read...

Agent benchmarks don't measure true *AI* advances
We built one that's hard & trustworthy
👉AstaBench tests agents w/ *standardized tools* on 2400+ scientific research problems
👉SOTA results across 22 agent *classes*
👉AgentBaselines agents suite
🆕arxiv.org/abs/2510.21652
🧵👇

Super interesting and well written summary of the incredible progress we’ve made on climate change (and what’s most important to do next) ⭐️⭐️⭐️⭐️⭐️ gatesnotes.com/three-tough-t…
