




30 days of Boardy starts today 🚀
Pick a business, career, or life goal and talk to @boardyai every day through Nov 18.
The person with the biggest transformation joins us at @hf0 Demo Day on Dec 1 and tells their story to 400 of Silicon Valley's top investors.
Also, the first 1,000 people to sign up get into a WhatsApp group with Boardy and the team.
I'm doing it too. My goal is to post every day here and on LinkedIn and hit 10k followers on both. Day 1 ✅
Let me know if you want to join and I'll send you a link!

In voice AI I think the moats left are the boring ones. Latency nobody notices, cost that holds up at millions of minutes, and distribution. A demo is easy to copy. A conversation that feels natural at scale is not.

In a similar scramble I did to jump on AI in late 2022 (moving from remote work and nomads to AI apps), I am now scrambling to chase any remaining moats
As AI companies will suck up everything else (in my humble opinion)
So for every moat left I see where I can pivot towards to that with my sites/apps
Proprietary data or content:
- I launched a nomads.com paid data API for companies from $2,490/year to $9,990/year, the city data is great because it's made by real members who for example review/like/dislike a city after visiting it, or being able to see which places are growing or shrinking (interesting of real estate, coworking, or gym investors)
- hoodmaps.com neighborhood data is very valuable and I'm building a paid API for that too, as well as including it in the Nomads API
Network effects / community:
- I made the nomads.com community free (before $99, now just $1 to avoid spam), the more people, the more network effect
Audience / distribution: you can get attention on demand
- I have an @X audience and I get paid well for it (about ~$15K/mo), but I've also diversified that with my blog levels.io's email list and Telegram subscribers, which is now 187,279 people who get daily/weekly/monthly email digests of my posts
Physical component: hardware, locations, IRL:
- I have been improving and promoting nomads.com meetups, there's now 8 meetups planned in the next 30 days, but is has to keep growing, I've also added fitness meetups etc.
- I've been using and working on hotelist.com a lot and improving it, it seems to fill a real void in booking sites that all suffer from rating inflation and filters that are not modern, I'm adding features I want and it seems that's working. Today I'm adding a filter for Longevity Hotels, that have a strength training gym, wellness area, blackout curtains, as a counter balance to the boomer hotels with champagne on check in and a gym with only treadmills etc. Hotelist is fundamentally IRL because hotels are IRL
- Not really IRL but vibejam.com is an annual event that's every year has ~1000 people participating vibe coding games and this year had over 1 million people playing the games, and AI companies really like to sponsor it because it's a great way to get exposure for their AI building tools
- I am building a pieter.com 1990s retro PC mini remake, like the SNES Mini, or the ModRetro M64, a hardware product I can sell marketed for nostalgia, especially after the last few weeks where it took off finally, I think there could be some market, and hardware is fun to try
- I sell merch on levelsio.com and make about $1K/mo from it, I haven't been very active on it but could expand this if I want
Capital: owning assets and investing
- I was already heavily invested in AI companies but have been even more with the acquisition of Cursor giving me $SPCX stock, I'll hold on to that, I think money will keep getting sucked from the traditional economy and replaced with paying AI companies money
- As a hedge, I've also put more money in bonds with IB01 ETF in case the AI bubble pops, $IB01 is a nice simple ETF for that
- I am actively looking at buying more land and real estate (especially coastal) as that's a scarce asset that will remain scarce post-AGI
- I am actively investing in startups with levels.vc although I'm wondering what startups are still valuable to invest in as Big AI and Big Tech suck up everything, if you look at the last YC batch, it's all "Cursor for {industry}" harnesses and hardware, I think robotics could be interesting to invest but it's unclear who will be the winner as ironically robots have a low barrier to entry. Most robots are just Chinese-made components put together with some vibe coded software by their Western founders!
- I am open to buyers for photoai.com and interiorai.com to increase the amount of capital I can invest elsewhere
Regulatory: licenses and legal barriers
- I am bad at this, and don't like regulation by nature. So I don't have anything here. And I don't think I will try pursue anything in here. I have friends building apps that work on getting EU subsidies or EU government program credits for emissions etc. But it's not my thing
So yes, chasing moats it is! Let's see if it works

The best name for an ai engineer is Dev

ai engineers ship great models and awful first impressions.
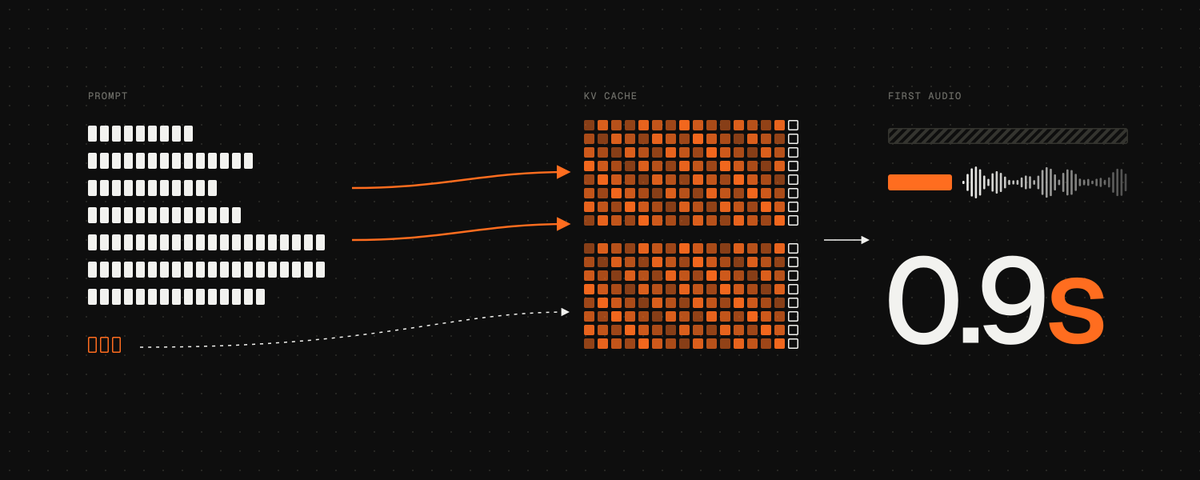
cache warming is the easiest, highest-leverage way to cut latency, yet almost everyone ignores it, even in voice ai. that obsession with the first second is one reason why @boardyai stands out!

Great post.
We specialise in outbound lead gen calls.
Both the tech and domain expertise. 20 years in contact centers, 4.5years building conversational voice AI blah blah...
The most important part of the call is the first second. If the customer has to say "hello?" you've lost them.
Our solution has always been to preload the opening line that triggers on first audio from customer.
It creates a seamless opening without skipping a beat.
Vooce AI is now tablestakes. It's the domain expertise and little tweaks that are the difference between a failure or putting $9.9m of pipeline and $3.1m of closed sales into HP's pipeline.
adaptivex.sg/case-studies/en…

ai engineers ship great models and awful first impressions.
cache warming is the easiest, highest-leverage way to cut latency, yet almost everyone ignores it, even in voice ai. that obsession with the first second is one reason why @boardyai stands out!
ai engineers ship great models and awful first impressions.
cache warming is the easiest, highest-leverage way to cut latency, yet almost everyone ignores it, even in voice ai. that obsession with the first second is one reason why @boardyai stands out!

honestly speaking most times one is enough. 2 is just a safe guard I have since prefix caching lives on one servers GPU's anyway. the only thing is that if it lands on replica 1 and the first turn routes to replica 2 it doesn't help.
so when I was benchmarking this and testing just kept 2. cost is minimal anyways but yes you can easily just do 1! good q
if you're building in voice ai, read this article.
@_devp spills some of the secret sauce on what makes the voice experience with @boardyai so good!
ai engineers ship great models and awful first impressions.
cache warming is the easiest, highest-leverage way to cut latency, yet almost everyone ignores it, even in voice ai. that obsession with the first second is one reason why @boardyai stands out!


Indeed prompt caching is required for voice agents along with correct request routing, next you should use speculative decoding heavily too (matters for tool calling)

Nice write up! Good experimentation.
Although do t you think speech to speech models will become more the norm? With llm calling ofc
honestly i think it still depends, but right now s2s is much less controllable for developers, especially for custom voices. Most s2s systems support cloning, but it’s harder to synthesize well bc you’re going audio-to-audio instead of using a dedicated TTS model.
The model has to disentangle content, prosody, and speaker identity from the source, which creates trade-offs in timbre (vocal diff) leakage and prosody that a cascaded TTS pipeline avoids. so it has its pros and cons


We’re giving away $1 million to agents.
Introducing Composio Instant: the easiest way for agents to pay for their own tools.
Claim your agent's share: composio.dev/instant
I do think that voice ai pipelines still route almost everything through full ASR to generative decoding. A lot of latency and cost sits in that text-output step so reformulating the problem as constrained classification (audio to action) instead of open generation is def going to be the new paradigm shift


Most latency sits in prompt processing (which can be cached and prewarmed) not text generation because you can stream sentences to a TTS.
Unless if you're using a reasoning model
completely agree, literally wrote about this yesterday! prefill + prewarming cache.
the text-output problem I mention above is more so about the paradigm shift of using an audio <> action model over a LLM intermediary for reasoning
devp.ca/synthetic-warmup


How to kill a voice agent? Just turn on the TV ☠️
We benchmarked 14 voice agents with a TV playing in the background.
Task completion fell from 38.7% to 8.6%
🧵/


Puentes starts this Sunday.
We're flying 15 of the best young engineers from Latin America to SF.
They’re among the most talented in their countries, and they want to be here to compete with the best.
Our goal at @antigravitysf is to help them stay.
Meet the engineers 👇