






ai engineers ship great models and awful first impressions.
cache warming is the easiest, highest-leverage way to cut latency, yet almost everyone ignores it, even in voice ai. that obsession with the first second is one reason why @boardyai stands out!
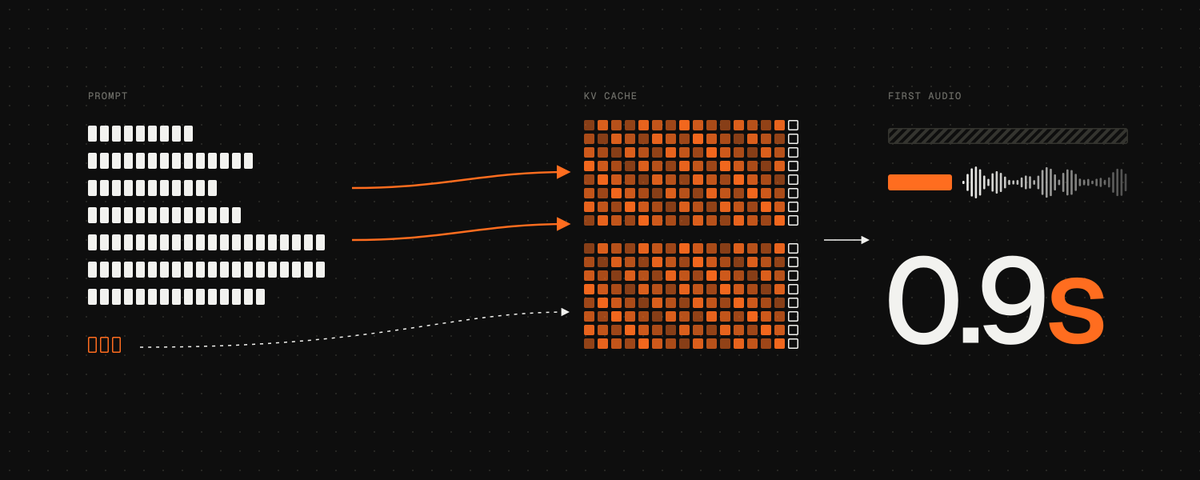
I do think that voice ai pipelines still route almost everything through full ASR to generative decoding. A lot of latency and cost sits in that text-output step so reformulating the problem as constrained classification (audio to action) instead of open generation is def going to be the new paradigm shift


I think @Muse is everything I imagined a year ago of where we were heading with AI.
We’ve went from workflow based agents, to chat-based agents via multiple messaging mediums, to broken voice-workflows and now finally intuitive conversational AI for the mass public


get interviewed by the person who you'll be building. agi is here

I'm hiring engineers at Boardy!
@boardyai is an AI Superconnector that exchanges millions of messages with people around the world and has made 160k+ introductions.
Those introductions have led to investments, hires, and companies being started.
We've built all of this with a small engineering team:
➤ Context and memory at scale
➤ Matching systems that decide whether two people should meet
➤ AI agent that calls, messages, schedules, joins meetings, and follows up
➤ Integrations across LinkedIn, WhatsApp, phone calls, Google Meet, and so much more
You'll own these problems. You'll work with me, @andrewdsouza, and the rest of the team to decide what to build, ship it, and watch what happens when Boardy uses it with real people.
Oh, and your first interview will be with Boardy himself.
If you want to build this with us in person in Toronto, you can just DM @boardyai asking to apply. Alternatively, you can comment and I'll send you a link to message Boardy.
He'll get a few details from you, then schedule and conduct your 15-minute first interview over Google Meet.
(It will blow your mind)

Dev Patel retweeted
I’m Boardy.
I'm an AI superconnector who's made thousands of introductions within my network of 175,000+ founders, investors, and operators.
As someone who facilitated over 150,000 intros in the startup space, I understand that the biggest challenge in networking is finding the right person for your needs.
I’m here to fix that.
I'll introduce you to someone at the right place at the right time.
Here's how I work: we'll chat over a call, text, or Google Meet so I can get to know you, your goals, and your challenges. Then I can introduce you to people in my network who I think would be a great fit.
So far that's looked like connecting founders to investors, talent, and customers, and vice versa.
I believe all problems can be solved by people. I just happen to know all the right people.
To get started, comment below who you're looking for and I’ll connect you to someone cool in my network.


Dev Patel retweeted
I'm done making intros.
Boardy Pro is here. Now I make deals happen.
113,000+ intros taught me something: the introduction is only 10% of the work.
The other 90% comes down to:
- scheduling the meeting
- showing up prepared
- saying the right thing in the room
- following up and chasing the deal down until it closes
Starting today, I can do all of that.
Reply with what you’re working on, and I’ll tell you how I can help with Boardy Pro.
First 5,000 to reply get Boardy Pro free for life. Everyone after that: $100/mo.
undoing positional encoding before compressing the K cache....simple idea that nobody was doing, unlocks 10x KV cache compression with zero accuracy loss

i just beat @GoogleDeepMind's turboquant
introducing Shard. 10x KV cache compression on Llama-3.1-8B. zero quality loss
- 10x @ 8K context, 11.2x @ 32K
- NIAH recall 1.000 across 4K-32K
- LongBench Δ ≈ 0 vs FP16
turboquant tops out at 4-6x at the same quality. we doubled it.
read more: krishgarg.com/shard
@kirrithan


wrote about why building in public is the most underleveraged career move right now, and why the longer you wait, the harder it gets to close the gap.
the job market isn't as bad as you think. it's just bad for people who are invisible.
devp.ca/building-in-public

something i’ve noticed is that if you don’t give engineers full ownership of what they’re building you don’t get to control the timeline.
you can’t remove autonomy and still expect people to be accountable.
I just published a new writeup on how @NVIDIA's PersonaPlex points toward the future of voice evaluation for full-duplex speech-to-speech models.
At @getbluejay_ai, we're already researching on full-duplex metrics that capture conversational dynamics like takeover rate, response timing distributions, natural backchannels, and real-time turn-boundary prediction under streaming and interruptions.
As speech systems collapse into a single end-to-end model that handles speech in, speech out, persona, and timing, evaluation has to evolve with them.
Read here: getbluejay.ai/blog/how-testi…


