
Corso is a Professor at U Michigan and Co-Founder of Voxel51 who makes the category-defining data+model codevelopment ML Tool: FiftyOne
Ann Arbor, MI
Joined June 2011
- Tweets1.3K
- Following228
- Followers1.6K
- Likes1.6K




VOXEL51 IS REBORN TODAY!!!!
Starting today, anyone can try Voxel51's paid features for FREE with just an email.
For anyone who hasn’t tried our product yet, here are three things I’d try first:
→ Voxel51 Search: Hybrid search across embeddings and structured metadata. All data uploaded to Voxel51 is automatically indexed, so you can search by semantic similarity alongside exact conditions, metadata, and multimodal events out of the box.
→ Agentic Labeling: Powered by VLMs, generate labels from natural-language instructions and visual examples, then review and refine the prompts before applying them more broadly.
→ Voxel51 Agent: Everything you can do with Voxel51 can now be initiated with a prompt. Ask and answer questions about your data and models, and turn those actions into repeatable workflows.
Try it on your own data and tell me in the comments what works and what doesn’t: lnkd.in/gx4_kV_C

Farewell ECCV 2026! 🇸🇪🇸🇪🇸🇪🇸🇪
Among the conferences I've been to in the last few years, this ECCV in Malmö was among the most enjoyable. The setting was grand. The size was just right (for these days). Many solid papers....world models and Physical AI ahoy folks! The keynotes by Kristen Grauman, @ylecun Yann LeCun, and @Jamie_Shotton were seriously enjoyable.
Enjoyed presented a handful of papers from @Voxel51 and @UMich
I left feeling rejuvenated. In a field where it is easy to confuse "paper progress" with real progress, this is just what I needed.


From HOMES to SHAME—a lesson in signal vs. noise.
For generations, students have learned the Great Lakes acronym: Huron, Ontario, Michigan, Erie, Superior. Now, amidst genuine economic headwinds, shifting immigration policies, and critical challenges facing our workforce and technology sectors, time is being spent trying to rename Lake Ontario to "Lake America."
That turns HOMES into SHAME (Superior, Huron, America, Michigan, Erie).
As an engineer and founder, my core job is filtering out noise to focus on real-world systems, actionable data, and meaningful human impact. Superficial rebranding doesn't spur innovation, lower mortgage rates, or train the next generation of engineers. It’s pure distraction.
Let’s save the energy for problems that actually need solving.

As the fall terms start in colleges around the US, AI is on the mind….
time.com/article/2026/08/26/…
Curious what y’all think.

Jason Corso retweeted

FiftyOne now supports multimodal time-series data—visualize, query, and curate synchronized sensor episodes from one platform - hubs.ly/Q04qJrwN0
End-to-end and VLA models generalize better but act as black boxes. When they fail, data is your only window in. Yet most teams still stitch together playback tools, custom scripts, and annotation platforms just to answer one question: is this a one-off, or a pattern?
New in FiftyOne:
* Native MCAP ingestion—camera, LiDAR, and numeric sensor streams play back in sync, no lossy pre-extraction
* Fully searchable time-series—query by metadata, events, labels, or embedding-based similarity
* Labels persist as tracks across entire episodes
* Temporal tags on any interval, turned into queryable, metadata-rich assets
This means root-cause analysis in minutes instead of days.
#PhysicalAI #Robotics #AutonomousVehicles #ComputerVision #MLOps
Jason Corso retweeted
"Pick the small one, not the big one." Simple instruction. But if the model underneath can't ground it, your robot grabs the wrong item - voxel51.com/blog/kubricount-…
We ran NVIDIA's LocateAnything-3B through KubriCount — a synthetic benchmark built to break grounding models — using a curate → annotate → generate → evaluate loop in FiftyOne.
* The results on the hardest split: precision 0.33, recall 0.28
* The model finds fewer than a third of the objects it's asked for
* 94 scenes, it counted the distractor instead of the target. Prompted for "boat" (6 in frame), it returned 34 — silently counting the vessels next to them
Aggregate metrics hide this. You only catch it by looking at the actual boxes.
Check out @datascienceharp 's blog
#SyntheticData #Robotics #FoundationModels #ComputerVision
Jason Corso retweeted
Raw, multi-sensor robotics data is notoriously messy to work with - docs.voxel51.com/user_guide/… - FiftyOne solves that:
* Unified Visuals: Combining multi-camera feeds, depth maps, and point clouds straight from standard MCAP files.
* Temporal Tagging: Easily curating time-series data on the fly (like tagging exact gripper states).
* Instant Organization: Turn complex sensor logs into clear, actionable datasets in seconds.
Clean data curation is the backbone of great AI and robotics models.
#Robotics #DataScience #AITraining #Tech #DataVisualization
𝗣𝗵𝘆𝘀𝗶𝗰𝗮𝗹 𝗔𝗜 𝗶𝘀 𝗺𝗲𝘀𝘀𝘆.
Anyone who has worked with robotics data knows the headache: cameras, LiDAR, GPS, and IMUs all streaming on separate channels, ticking on their own completely independent clocks. Historically, just looking at what your robot saw meant breaking your workflow to spin up dedicated tools like ROS, Foxglove, or rviz.
My guy @DataScienceHarp at @Voxel51 just blew me away with a breakthrough integration that brings this directly into the modern AI ecosystem.
With the release of 𝗙𝗶𝗳𝘁𝘆𝗢𝗻𝗲 𝟭.𝟭𝟵, we now support 𝗠𝗖𝗔𝗣 𝗳𝗶𝗹𝗲𝘀 𝗻𝗮𝘁𝗶𝘃𝗲𝗹𝘆. You can point a sample at a .𝚖𝚌𝚊𝚙 file and watch every decodable channel sync perfectly onto a single playback clock---with 𝘇𝗲𝗿𝗼 𝗥𝗢𝗦 𝗶𝗻𝘀𝘁𝗮𝗹𝗹𝗮𝘁𝗶𝗼𝗻 𝗿𝗲𝗾𝘂𝗶𝗿𝗲𝗱.
But Harpreet took it a step further: he has FiftyOne running natively inside a 𝗛𝘂𝗴𝗴𝗶𝗻𝗴 𝗙𝗮𝗰𝗲 𝗦𝗽𝗮𝗰𝗲.
You can play with it right now in your browser. He's hosted a dataset of 10 autonomous UAV flights through a Virginia forest. We're talking 31 parallel channels of dense data---stereo cameras, 3D LiDAR point clouds, and live GPS tracks---all perfectly synchronized and scrubbable directly in a web app.
This narrows the gap between raw robotic memory and curated AI datasets. It's a massive win for reproducibility and accessibility in Physical AI.
Take a look; WDYT?
👉 Try the Hugging Face Space: huggingface.co/spaces/harpre…
📖 Read his full technical walkthrough: voxel51.com/blog/view-mcap-f…
@julien_c @huggingface
Jason Corso retweeted
Farm fields don't look like ImageNet. The lighting shifts hour to hour. A crop and the weed stealing its water are the same shade of green. And the "object" you're detecting today is a two-leaf seedling that'll be shoulder-high in six weeks - hubs.ly/Q04pxll60
That's why agriculture needs its own computer vision datasets — and this new field guide from Voxel51 just made them radically easier to actually use.
14 open datasets. All mirrored in FiftyOne format on Hugging Face. Every one broken down by exactly what's inside before you download a single byte:
* Crop & weed segmentation (RGB, RGB-D, 5-band multispectral)
* Orchard phenotyping & BBCH growth-stage tracking
* In-the-wild plant disease classification
* 3D point clouds — raw plant geometry, not pixels
* Sentinel-2 field boundaries across 25 countries
* A dataset captured by an actual farm robot that has to re-identify a lettuce it saw 5 minutes ago
This is agricultural computer vision quietly becoming physical AI training data — perception stacks built to end up on machines that move through the world they're imaging. 🚜
Check out @DataScienceHarp 's post if you work anywhere near ag, robotics, or remote sensing.
#computervision #ai #artificialintelligence #machinevision
#machinelearning #datascience #physicalai #mcp #agents
Jason Corso retweeted
1 in 3 teams pay to annotate data that never makes it to production. That's not a labeling problem. That's a strategy problem - hubs.ly/Q04pvP2r0
FiftyOne Annotation treats annotation as a data flywheel — not a one-time chore.
* Label the right data first. Smart Data Selection surfaces the rare, high-signal samples that actually move model performance — teams ship with 60–80% less annotated data.
* Agentic labeling. VLMs handle the first pass, so humans review and correct instead of drawing every box from scratch.
* 2D, 3D & video in one place. Bounding boxes, SAM2 click-to-segment, lidar cuboids, temporal events — all native.
* Intelligent Review. Embeddings + model comparison catch systematic label errors before they poison training.
* Close the loop. Model eval failures feed straight back into the next annotation round. Every iteration compounds.
The magic isn't any single feature — it's that curation, annotation, and evaluation finally live in ONE platform. No handoffs. No lost context. Just faster models, less waste. Stop labeling everything. Start labeling what matters.
#computervision #ai #artificialintelligence #machinevision
#machinelearning #datascience #physicalai #mcp #agents
The era of throwing millions of random samples into the GPU woodchipper is over. We’re drowning in mediocre bits while starving the critical "tails" of our data distributions.
My take: More data isn't better data. Relying on sterile simulation mirages or unchecked "AI agents" to clean up our datasets is just a pedagogical hack that risks model collapse. Responsible AI requires active data stewardship, human-in-the-loop verification, and strict dataset provenance.
Read the full essay on why it's time to move past the Great Data Delusion: medium.com/@jasoncorso/the-g…
🤖 Made with AI

Silicon Valley pundits love to preach the 80-hour work week; or what is it in China now, the 9-9-6 schedule. They tell you that building the future of AI, robotics, or a venture-backed startup requires constant, grinding hustle.
They’re wrong.
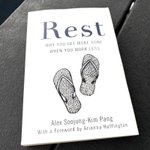
For a weekend read, I'm staring at "Rest: Why you get more done when you work less" by @AlexSoojun8374 Alex Soojung-Kim Pang. I had bought it last year and it finally rose to the top of the queue. Yet, it seems to be giving words to practices I've long espoused. I'm a "work hard everyday" kind of person, but I'm also a rest, create, expand type of person.
One thing really from the beginning of the book jumped out at me. In the foreword, @ariannahuff Arianna Huffington points to a concept that completely refutes the tech-bro narrative: "Layer Work and Rest." The premise is simple but profound: supercreative people alternate periods of intensive work with periods of deliberate rest.
She writes, and I'm paraphrasing hre: When you intentionally step away from a grueling technical problem, you aren't quitting. You are actually encouraging your subconscious mind into taking over. By giving yourself time and space immediately after focused effort, you allow your brain to discover the elegant solutions that eluded your conscious grasp.
And I think that is actually layered into different temporal hierarchies: a given day, a given week, a given season.
In STEM, we often treat humans like silicon processors that just need to be overclocked. But building responsible, impactful technology requires depth and clarity, not just raw compute.
Deliberate rest isn't laziness. It’s the ultimate cheat code for bringing real value.


Jason Corso retweeted

World models don't run on scraped text. They need continuous, multimodal observation of the physical world: labeled, time-stamped, geo-grounded.
Voxel51's @_JasonCorso_ writes for @FortuneMagazine, "AI models are choking on junk data."
The 15-minute high-level board update is a trap. Without the details, advisors just pattern-match onto other companies and give generic, parrot-like advice.
My take: Boardrooms need to operate like university labs. Block out 90+ mins for 1 hard topic. Detail matters.
TAF Series #18: medium.com/@jasoncorso/deep-…

"Disagree and Commit" is the hardest shift for technical founders who are used to being "right." If you're still second-guessing a team decision 2 weeks later, you're the friction.
My take: Conviction > Certainty.
Read the full essay on navigating constructive confrontation: medium.com/@jasoncorso/const…
