

hacker-in-residence/ principal devrel engineer. data curation for physical and visual ai systems. in my physical ai era
I ship daily
Joined April 2020
- Tweets7.1K
- Following1.6K
- Followers8.1K
- Likes33K




Pinned Tweet
a robot can recognize every object in a room and still not know how to open a single drawer
knowing there's a cabinet is scene understanding. knowing which handle to grab, which direction to pull, and that it's a drawer not a door is affordance understanding
almost no dataset has it in 3D
SceneFun3D: 14,800+ functional elements across 710 laser-scanned indoor scenes. every handle, knob, button, and switch labeled with its affordance, motion axis, motion type, and a natural language task description
each scene's 3D point cloud with its iPad video recordings in fiftyone. the affordance annotations live in 3D and project into the video frames
check it out here huggingface.co/datasets/Voxe…
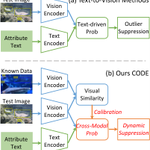
a hard outlier penalty can hide objects the label list never had.
CODE adjusts open-world detection at inference time. visual prototypes calibrate text-to-vision matching, and margin-aware suppression replaces a fixed outlier penalty. gains on OWL-ViT are +2.6 U-mAP and +2.3 K-mAP over SOTA.
arxiv.org/abs/2608.27214
#PhysicalAI #ComputerVision

no mcp server or agent in the loop but still looks useful

Must-have kitchen gadget! Keeps hot lids & greasy spoons off counters.
Shop Now: kannuz.com/steel
dense disparity from a stereo pair, including pairs the model never trained on.
C-Fast-FoundationStereo is NVIDIA's real-time zero-shot binocular stereo model. it computes dense disparity from rectified stereo pairs.
huggingface.co/nvidia/c-fast…
#PhysicalAI #ComputerVision

wow so the model tracks uncalibrated video so accurately that it cuts 3d mapping errors in half, with less gpu memory, in both shaky indoor rooms and massive outdoor driving scenes

📊 Results on TUM RGB-D, 7-Scenes, Replica and KITTI
🔹 Best average ATE in the uncalibrated setting on TUM RGB-D (0.027 m) and Replica (0.002 m)
🔹 On KITTI, well ahead of the uncalibrated foundation-model-based baselines
🔹 7-Scenes reconstruction vs SLAM-Former: completion 0.030 → 0.015 m, Chamfer 0.027 → 0.019 m
🔹 About 7.4 FPS on one A100, with less peak GPU memory than SLAM-Former (15.4 vs 27.7 GB)
4/5


ok time to get hands on with nemotron vl

New on @FireworksAI_HQ Training:
• Muse Spark Open → Serverless Training API
• DeepSeek V4.1 Flash 1017 → Serverless (replaces prior version)
• Nemotron 3.5 Super VL → Serverless, Dedicated & Managed Training, incl. full-parameter runs
Get started: docs.fireworks.ai/fine-tunin…

a radar image should obey the radar equation and stay differentiable.
3DPS-Radar is a differentiable 3D point renderer derived from the radar equation, with ITU-R P.2040 material modeling, for complex-valued mmWave novel view synthesis.
arxiv.org/abs/2609.11894
#PhysicalAI #ComputerVision

your SLAM trajectory is only as good as what you grade it against. this benchmark's ground truth is an eight-camera mocap system at 100 Hz
TUM RGB-D: a Kinect recording color and depth at 30 Hz, handheld and on a Pioneer robot, across scenes built to test structure, texture and moving people
all 47 sequences are in fiftyone, 48 minutes, so you can play color, depth and the ground-truth pose together
start here, read the dataset card: huggingface.co/datasets/Voxe…
a text query, then a 3D box, from camera, LiDAR, and radar together.
Talk2Sensors does language-conditioned 3D visual grounding on camera, LiDAR, and radar, and returns detections with labels and 3D boxes.
arxiv.org/abs/2608.04568
#PhysicalAI #ComputerVision

if you have a wrist camera you've never watched frame by frame and a policy that hesitates at the first grasp
welcome, this account is for you
i check robot datasets before anyone trains on them. last one i scored had an episode where the video ran 0.4 seconds behind the actions. every file intact, every duration matched, and it would have trained a policy on stale frames
no leaderboards. no hot takes on the new model
reply with the lerobot dataset you want scored first
your rig writes 23 channels on 23 clocks
cameras, lidar, gps, imu, diagnostics: robotics recordings were unexplorable without a dedicated tool per format. mcap fixed the container problem, and fiftyone now plays every decodable channel on one shared timeline, natively
point a sample at a .mcap file. that's the whole integration
the fiftyone app is running in a hugging face space for the first time (its a bit hacky atm, but working on polishing it up)
space: huggingface.co/spaces/harpre…
full walkthrough: voxel51.com/blog/view-mcap-f…
#mcap #skills #computervision #ai #artificialintelligence #machinevision #machinelearning #physicalai
wow the results look super impressive
i'll be keeping an eye out on this repo for updates: github.com/Evergreen0929/S4V…
great work from @jdzhang0929 @nvidiaresearch


most benchmarks in this domain test against synthetic assumptions.
real-world deployment breaks on edge cases nobody captures.
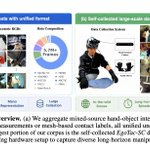
EgoTac captures the ground truth:
predicts tactile signals from egocentric video.
arxiv.org/abs/2608.15060

VLM prose is useless to a labeling pipeline
'the image shows a red car near a building' is a chatbot answer. a pipeline needs boxes, classes, and confidences in a schema
my fiftyone plugin points minimax-m3 at your dataset and gets structured labels back:
bounding boxes, keypoints, temporal events, classifications
not text you have to parse, actual label objects written to your samples
run it across an entire view to bootstrap annotations. or open the chat panel on a single sample, ask a question, and convert the reply to a label field with one click
check it out here: voxel51.com/blog/minimax-m3-…
#mcap #skills #computervision #ai #artificialintelligence #machinevision #machinelearning #physicalai
robot data isn't video, and treating it like video is why your tooling fights you
a manipulation episode is video plus joint positions, torques, gripper state, and end-effector trajectories, all on one clock. look at any one alone and you're debugging blind
fiftyone's multimodal viewer plays all of it on a shared timeline. scrub the failure, see every signal at that instant
checkout the dataset here: huggingface.co/datasets/Voxe…
#mcap #skills #computervision #ai #artificialintelligence #machinevision #machinelearning #physicalai
radar keeps working when dust and smoke blind a lidar. here is a handheld rig with both, carried through an underground mine
ColoRadar from CU Boulder: 2 FMCW radars (cascaded imaging and single-chip), an Ouster OS1-64 lidar and an IMU, across hallways, a lab, outdoors and a mine
i put 7 sequences in fiftyone, 382 million lidar points, so you can play radar and lidar side by side
start here, read the dataset card: huggingface.co/datasets/Voxe…
a mask drawn on the RGB frame is wrong on the thermal frame
the two cameras don't share optics, so every pixel-perfect annotation has to be done twice. that's why thermal segmentation datasets are tiny
SegFly skips that. label once in 3D, propagate back into every 2D view. 35,000 aerial RGB-thermal image pairs, 97% RGB and 100% thermal masks generated with zero manual 2D refinement, across multiple altitudes and seasons
check it out here, mapped it into fiftyone as grouped RGB/thermal slices, so you can flip between modalities on the same scene, filter by altitude or season, and run the propagation trick on your own drone footage.
huggingface.co/datasets/Voxe…
#mcp #skills #computervision #ai #artificialintelligence #machinevision #machinelearning #physicalai

harpreet retweeted

VOXEL51 IS REBORN TODAY!!!!
Starting today, anyone can try Voxel51's paid features for FREE with just an email.
For anyone who hasn’t tried our product yet, here are three things I’d try first:
→ Voxel51 Search: Hybrid search across embeddings and structured metadata. All data uploaded to Voxel51 is automatically indexed, so you can search by semantic similarity alongside exact conditions, metadata, and multimodal events out of the box.
→ Agentic Labeling: Powered by VLMs, generate labels from natural-language instructions and visual examples, then review and refine the prompts before applying them more broadly.
→ Voxel51 Agent: Everything you can do with Voxel51 can now be initiated with a prompt. Ask and answer questions about your data and models, and turn those actions into repeatable workflows.
Try it on your own data and tell me in the comments what works and what doesn’t: lnkd.in/gx4_kV_C

trying voxel51's paid features, last week:
- fill out a form
- book a call
- wait for a trial environment
- finally load your data
trying them today:
- sign up with your email
- load your data
that's it. voxel51 3.0 just launched a free tier
agentic labeling, hybrid search, the agent, dataset versioning, all of it: link.voxel51.com/harpreet