

daily AI productivity tips that work in real life. the apps, the shortcuts,honest reviews for people who want to use AI without becoming obsessed with it.
FL
Joined December 2017
- Tweets689
- Following1.8K
- Followers712
- Likes508





Sarah B. retweeted

meta just released muse spark open, and the label “open weight” is worth understanding.
it means the trained model files are public, so you can download and run it yourself instead of only using it through a website.
this one has 816 billion parameters, which is the model’s size, but only 42 billion are used for each request. think of a huge team where only the right specialists answer each question.
it can run on two Apple M5 Ultra Mac Studios, so a normal laptop is out.
meta’s license also limits commercial use, so check the terms before building a business on it.
research.meta.ai/blog/muse-s…

Sarah B. retweeted

In February Alphabet sold a £1B bond that matures in 2126, at a 6.125% coupon with £9.5B of orders. It was the first 100-year bond from a tech company since Motorola in 1997
By July it had traded below 90p
Alphabet, Amazon, Meta, Microsoft, Oracle and SpaceX had issued over $180B of USD bonds this year as of early September. 41% of hyperscaler issuance since 2025 runs past 15 years, against 16% for the US corporate index
The servers get depreciated over 5–6 years. The longest bonds funding the buildout run 30 to 100

Sarah B. retweeted

prompt i'd use to write ads for Notion Mail without getting the usual “work smarter” sludge
product - Notion Mail
audience - startup operators who live in gmail + notion all day
pain - action items get buried across inbox threads and notes
proof to use - emails can be organized and acted on inside the same workspace
objective - get people to start a free trial
write 10 hooks under 12 words
Sarah B. retweeted

the problem
kept shipping agent output that looked right and wasn't. no way to tell the difference until a human read every line.
the fix
anthropic's outcomes feature, announced at code with claude sf in may 2026, adds a separate grading agent. you write a rubric describing what "good" means for the task, and a second instance of claude scores each run against it before anything gets delivered.
action
write the rubric before you build the agent, not after. list 3-5 concrete pass/fail criteria for the output, then let the grader enforce them on every run.
tradeoff
pro: turns "does this feel right" into a score you can track and improve against.
con: a vague rubric gives you a confident, meaningless score, the grader is only as good as the criteria you wrote.
takeaway
stopped eyeballing agent output. wrote five criteria, the grader caught what i was skimming past.

Sarah B. retweeted

We're releasing pplx-embed-v2-late, two late-interaction embedding models that retrieve text, images, and pages with a shared embedding space for cross-model querying.
Both models achieve frontier performance and are publicly available on Hugging Face.
perplexity.ai/hub/blog/multi…

Sarah B. retweeted

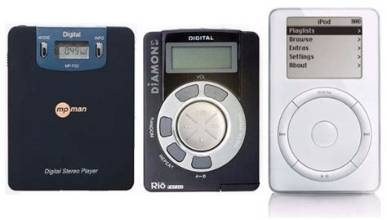
portable digital music needed a way to make audio files much smaller.
compression systems removed or simplified parts of the sound that listeners were less likely to notice.
that tradeoff made it possible to store more songs, download them over slower internet connections and move them between early computers and portable players.
people accepted some lost detail in exchange for access.
once a music library could travel in a pocket, convenience became part of how listeners judged a format.
streaming changed where the file lived and compression had already changed what people expected music to do.
Sarah B. retweeted

sometimes you need to see the progress to feel it.
tracking sleep, activity and other health patterns can show you what’s working, what needs attention and where small changes could make a difference to your physical and mental wellbeing 🫶
Sarah B. retweeted

i tested an ai outfit-search flow with one black top.
it could find visually similar items, which is the easy part. but it never asked the questions that decide whether a recommendation is useful: budget, fit, occasion, country, or whether i wanted an exact match versus a dupe.
that is the gap with most ai shopping features right now.
image recognition finds the item and a good product design has to figure out the intent behind it.

Sarah B. retweeted

Anthropic keeps testing a new "Hub" feature internally, asking users to provide a feedback in case if they switch back to a normal chat.
Claude Hub is ssumingly a task orchestrator component that Anthropic may plan to release broadly.


Sarah B. retweeted

Michael Polansky(Lady Gaga's partner) has been quietly keeping human skin alive outside the body for over a month and training an AI on it to discover new skincare compounds
the AI predicts which chemicals might help, the living tissue tests them, and the results feed back into the model improving the next prediction — generating a new candidate roughly every six weeks
this is the most interesting biotech story of the week and it got buried under the Opus 4.6 jailbreak discourse

Sarah B. retweeted
people keep asking what's actually in my ai stack, so here's the honest breakdown.
claude's about half my usage, writing, editing, thinking things through out loud. chatgpt's maybe a third, mostly for doing rather than thinking, quick research and image stuff. perplexity when i actually need a citation instead of an opinion. gemini only when i'm already stuck inside google docs or gmail, otherwise i forget it exists.
but the split isn't the part i'd actually recommend copying. it's what i don't do: no single tool for everything, no first draft goes out unedited, nothing gets published without reading it out loud first.
the percentages will look different in six months. that last part probably won't.

Sarah B. retweeted
Computer now works in email.
Send, forward, or cc [email protected] on any thread.
Every email task runs as a normal session in Computer, viewable on web and mobile, with the same audit trail as any task in the app.


Sarah B. retweeted

Today, we release LFM2.5-VL-3B, a lightweight vision-language model that reads screens, documents, and the physical world. It handles digital screens across mobile, web, and desktop, grounds objects to coordinates, reads text and charts, and calls tools from either text or image input.
Built on LFM2.5-2.6B base, with a SigLIP2 400M NaFlex vision encoder
> Pre-trained on ~34T tokens
> Vocab size: 128K
Comparable or better scores compared to models up to 2.6x its size:
> ScreenSpot-v2 80.7, ahead of Gemma-4-E4B at 51.2
> RealWorldQA 73.1, ahead of InternVL-3.5-4B at 67.7
> TextVQA 84.3, ahead of Qwen3.5-4B at 81.2
> RefCOCO-avg 87.9, up from 57.1 on LFM2-VL-3B
> ToolSandbox 59.5, up from 26.4 on LFM2-VL-3B
🧵


Sarah B. retweeted
An Anthropic engineer dropped a 2-hour masterclass on graph engineering
“Everyone is now building agentic graphs”
Sarah B. retweeted

Humans only have a few more years until AI takes the lead, according to Elon Musk. yhoo.it/3TAewD6

Sarah B. retweeted
THE RL FRAMEWORK BEHIND GLM-5.2 IS NOW OPEN SOURCE
Slime keeps one RL training loop while handling different tasks through flexible data generation
Repo: github.com/THUDM/slime

Sarah B. retweeted

Que vous souhaitiez incarner un héros, un méchant ou un peu des deux, découvrez les jeux Marvel sur PS5 : store.playstation.com/catego…
Readers added context they thought people might want to know
Sony is pushing an all-digital future without being upfront about its limits. PS5 downloads can't be played from USB drive,and expanding storage requires an expensive NVMe SSD. Digital games are licenses, not true ownership.Physical discs preserve choice and ownership
blog.playstation.com/2026/07/01/phy…