

Professor of Law, Economics, and Business at @ETH Zurich. Associated with @ETH_CLE, Interested in #contractdesign, #lawecon, #lawtech
Zurich, Switzerland
Joined October 2017
- Tweets229
- Following323
- Followers476
- Likes145



Pinned Tweet
1/6 Are robot judges perceived as less fair than human judges? Yes, but minimal human oversight can eliminate this human-AI fairness gap. Check out our new Working Paper “Mitigating the Judicial Human-AI fairness gap.”

Four hundred years before behavioral economists ran lab experiments and HR departments debated “pay-to-quit” bonuses, William Shakespeare already had the answer.
On the eve of battle in Henry V, the king makes a startling offer: 1/


Alexander Stremitzer retweeted

Programs from previous years:
ethz.ch/content/dam/ethz/spe… (@danbjork, @jblumenstock)
ethz.ch/content/dam/ethz/spe… (@m_sendhil)
ethz.ch/content/dam/ethz/spe… (@MelissaLDell)
@eth_cle @econ_uzh @ETH_AI_Center @emollick @erikbryn @DAcemogluMIT @Susan_Athey @akorinek @aadukia @jensottoludwig @StephenEKHansen
Alexander Stremitzer retweeted
Call for Papers:
The 4th Annual Zurich Workshop in AI+Economics
to be held Dec 5-6, 2025, hosted by ETH Zurich and University of Zurich.
illuminating keynote to be given by @testingham (OpenAI)
organized with @sergallet @YanagizawaD @joachim_voth
Info: eash.cc/AI-econ
Submit (by Aug 15th): eash.cc/AI-econ-sub-2025


Alexander Stremitzer retweeted
Introducing an eval dataset of 4,886 law school exam questions. See if your AI can answer them!!

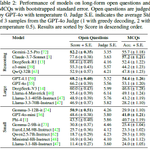
1/5 How good are AI Model’s Reasoning Abilities? We have created LEXam, a legal reasoning benchmark derived from real law exams available in English and German. @eth_cle @ellliottt @YoanHermstruwer @joelniklaus @OpenAI @GoogleAI @deepseek_ai @AnthropicAI @grok @AIatMeta

Alexander Stremitzer retweeted

Check out LEXam, our new Legal Reasoning benchmark! Thanks for the great collaboration @NJingwei, Jakob, Etienne, Yang, Yoan, @YinyaHuang, @akhtarmubashara, Florian, Oliver, Daniel,@LeippoldMarkus, @mrinmayasachan, @Stremitzer_Lab, Christoph Engel, @ellliottt, and @joelniklaus!


1/5 How good are AI Model’s Reasoning Abilities? We have created LEXam, a legal reasoning benchmark derived from real law exams available in English and German. @eth_cle @ellliottt @YoanHermstruwer @joelniklaus @OpenAI @GoogleAI @deepseek_ai @AnthropicAI @grok @AIatMeta
5/5
Link to the paper:
lnkd.in/daCSNXHF
4/5
𝑳𝑬𝑿𝒂𝒎 rigorously evaluates AI models' legal reasoning abilities by emphasizing both outcome correctness and reasoning process.
It was created through expert extraction and curation, 𝑳𝑬𝑿𝒂𝒎 contains 2,841 open-ended and 2,045 multiple choice questions (MCQs).

3/5 Discover our findings and benchmark your models with 𝑳𝑬𝑿𝒂𝒎!
- Project link: lexam-benchmark.github.io/
- Find more details in our paper: arxiv.org/abs/2505.12864
- Explore our datasets: huggingface.co/datasets/LEXa…