

Doctoral Researcher @ ETH Zurich, Research Interests: NLP for Social Good, Claim Detection and Verification, Causal NLP
Zurich, Switzerland
Joined December 2020
- Tweets48
- Following87
- Followers99
- Likes21




Ni Jingwei retweeted

🚨 Call for Papers: AI for Law Workshop @icmlconf (July 10, Seoul 🇰🇷), welcomes submissions across three themes:
⚖️ AI for Legal Reasoning
📊 AI Evaluation for Law
🌍 AI for Access to Justice
⏰ Deadline: May 22 (AoE)
📄Full paper submission via: openreview.net/group?id=ICML…

🚨 Using reasoning LLMs as annotators? You might be erasing critical human disagreements.
Our EACL'25 paper shows RLVR-style reasoning actually HARMS disagreement modeling—even when carefully prompted to consider it! 🙀
📄 Paper: arxiv.org/abs/2506.19467🧵👇

🧵[7/7]
Before deploying reasoning LLMs for annotation tasks:
⚠️ Test on high-disagreement cases, not just accuracy ⚠️ Consider RLHF + CoT over pure RLVR
⚠️ Keep humans in the loop where values conflict
📂 Code & data: github.com/EdisonNi-hku/Disa…

Big thanks to my co-authors and supervisors! @yu_fan_768 @zouharvi @donyarooein @miserlis_ @mrinmayasachan @LeippoldMarkus @dirk_hovy @ellliottt
Ni Jingwei retweeted

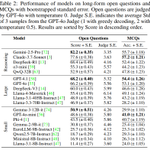
LEXam Update: GPT-5 Takes the Top Spot
We're excited to share our latest LEXam evaluation results:
- GPT-5 claims the #1 position, outperforming Gemini 2.5 Pro and setting a new state-of-the-art for legal reasoning on LEXam!
- We've moved from a single GPT-4o judge to a minimum-score ensemble of GPT-4o, Qwen3-32B, and DeepSeek-V3. This ensemble was developed through iterative refinement by PhD-trained legal experts and validated via the Alt-test (Calderon et al., 2025), achieving a perfect winning rate (ω=1.00) against all three human experts. Crucially, we found that minimum-score ensembles of even open-source LLMs can match human expert judgment, making rigorous legal evaluation more accessible.
- Sonnet 4.5 underperforms its predecessor Sonnet 3.7, and similarly, Qwen3-next trails behind QwQ-32B. This could suggest that the industry's current focus on coding optimization may not transfer effectively to legal reasoning tasks.
- The GPT-OSS models offer exceptional accuracy-to-price ratios on LEXam.
cc Yu Fan, @NJingwei, Jakob Merane, Yang Tian, @YoanHermstruwer, @YinyaHuang, @akhtarmubashara, Etienne Salimbeni, Florian Geering, Oliver Dreyer, Daniel Brunner, @LeippoldMarkus, @mrinmayasachan, @Stremitzer_Lab, Christoph Engel, @ellliottt

Ni Jingwei retweeted

🤖⚛️Can AI truly see Physics? Test your model with the newly released SeePhys Benchmark! 🚀
🖼️Covering 2,000 vision-text multimodal physics problems spanning from middle school to doctoral qualification exams, the SeePhys benchmark systematically evaluates LLMs/MLLMs on tasks integrating complex scientific diagrams with theoretical derivations.
📊Experiments reveal that even SOTA models like Gemini-2.5-Pro and o4-mini achieve accuracy rates below 55%, with over 30% error rates on simple middle-school-level problems, highlighting significant challenges in multimodal reasoning.
Key Features Highlighted:
🔎Vision-Text Integration: Explicitly emphasizes multimodal reasoning failures in interpreting diagrams (e.g., circuit schematics, coordinate systems).
🔎Cross-Domain Complexity: Tests models across 7 physics domains and 8 educational tiers, exposing weaknesses in both visual grounding and logical derivation.
🔎Open-Source Design: Fully reproducible framework for diagnosing AI's "visual illiteracy" in scientific contexts.
🎖️Project led by: @kaleb962, @HengLee29423, Terry Jingchen Zhang, @YinyaHuang
💼Joint work with an exceptional team: Zirong Liu, Peixin Qu, Jixi He, Jiaqi Chen, Yu-Jie Yuan, Jianhua Han, Hang Xu, Hanhui Li, @mrinmayasachan, Xiaodan Liang
🏁The benchmark is now open for evaluation at the ICML 2025 AI for MATH Workshop. Academic and industrial teams are invited to test their models and advance multimodal physics!
⚛️Project Page: seephys.github.io
🤗Data: huggingface.co/datasets/SeeP…
📜Paper: arxiv.org/abs/2505.19099
🏆Challenge Submission: codabench.org/competitions/7…
➡️Competition Guidelines: sites.google.com/view/ai4mat…


🚀 Huge thanks to the community!
📈 LEXam is now the #1 trending evaluation dataset on Hugging Face! Check it out: huggingface.co/datasets?othe…
🧠 Built for deep legal reasoning across 340 law exams
👩⚖️ Expert LLM judge evaluations, long-form + MCQs
#LegalNLP #Benchmark #LLM


👏 Big applause to my co-authors! @yu_fan_768, Jakob, Etienne, Yang, Yoan, @YinyaHuang, @akhtarmubashara, Florian, Oliver, Daniel, @LeippoldMarkus, @mrinmayasachan, @Stremitzer_Lab, Christoph Engel, @ellliottt, and @joelniklaus!
🚨Time to push LLMs further!
📚LEXam: The legal reasoning benchmark you’ve been waiting for:
• 340 exams, 116 courses (EN/DE)
• Long-form, process-focused questions
• Expert-level LLM Judges
• Rich meta for targeted diagnostics
• Contamination-proof, extendable MCQs
[1/6]🧵

4⃣ Dig Into Weaknesses with Rich Metadata
Every question includes detailed metadata (course, topic, reasoning steps), so you can pinpoint where your model struggles—be it contract law, criminal law, or multi-hop reasoning. 🔎📊
[5/6]🧵
6⃣ Future-proof: Contamination & Extendability
MCQs are permutable and extensible, making data contamination easy to check and new challenges easy to add. Benchmark stays tough as models evolve!🔒🔁
🔗Check out the paper! arxiv.org/abs/2505.12864
[6/6]🧵

🥳Newly Accepted by NAACL 2025!
[1/4] 🧵
In current information retrieval evaluation in RAGs. Three VITAL points are often missing!
1. How to define relevance? Relevance definition may vary across tasks and domains.

[3/4] 🧵
3. How to dynamically determine the Top-K to maximize information coverage?
Different queries require varying amounts of retrieved information. Determining Top-K dynamically to comprehensively supply information to LLMs remains a challenging task.
[4/4] 🧵
These challenges looks hard to solve?
Try DIRAS! A method leveraging open-source LLMs to efficiently generate high-quality annotated datasets for evaluating information retrieval performance in various RAG application domains.
Link: arxiv.org/pdf/2406.14162