





Pinned Tweet
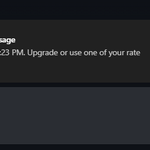
I have found out that the Sol 6.1 usage limit has been nerfed.
I have been using GPT-6.1 Sol ultra fast mode since its launch, and I was never able to use that limit. It was nearly impossible to finish limit, even having 5-hr usage limit as well.
Today, I just dropped one prompt, and in 10 minutes it used up the whole 5-hour limit. This was not the case before. Yes, I am not trying to sensationalize things here. I'm just dropping the screenshot below!
I think we are back to the good old days of Astra!
@thsottiaux


Sometimes back when Tibo said, due to Astra ability they had to prepone their plan 6 month early, I was curious that what they have in store for us, and we will be seeing too many New launches from them.
But after DevDay, seems like team have lost the focus completely and now, there is nothing we hear from them. It been 2-3 week we got really good model in 6.1 Sol, then it's just nothing.
Tibo, if you are hearing, what's going on man? OAI seems to be fighting on too many front and is this reset to avoid those attention?
I really want you guys to release new model which better than Astra.
Someone was already trying to exploit a critical PHP vulnerability 4 days before the public even knew it existed.
AI helped uncover the bugs in the first place.
This PHP2Shell situation is pretty concerning.
• PHP powers ~70% of websites.
• Two critical flaws, both rated 9.2/10.
• Some government websites went offline.
• Amazon spotted an exploit attempt on Oct 17, before disclosure on Oct 21.
• Censys found ~1.15M internet-facing hosts reporting PHP branches no longer supported upstream.
These bugs had been hiding in the code for years.
AI is making it easier to find problems like these, but millions of servers still depend on old software that isn't simple to update.
I keep thinking about that gap.

Two critical PHP vulnerabilities. Both can lead to remote code execution without authentication.
And the patches are already out.
CVE-2026-109618 and CVE-2026-109619 affect PHP’s core memory and error handling.
Fixed versions:
• PHP 8.5.12
• PHP 8.4.27
• PHP 8.3.36
• PHP 8.2.35
Don’t just check your server’s PHP version.
Check the runtime inside your Docker images and production containers too. Restart PHP workers after patching and verify the fix is loaded.
PHP 8.1 and older are no longer supported upstream, so upgrading needs extra attention.
Official details and fixes:
thephp.foundation/blog/2026/…
Have you checked which PHP version your production apps are actually running?

Wait what?
So now Dots are on the Pro plan and they don't use weekly usage, so what's underlying usage it uses?
But glad finally dots are getting available to some other plans than higher end only.
The smell of fear is in OpenAI except everywhere.

Fully included in the Pro plan, doesn't draw on your weekly usage.
Readers added context they thought people might want to know
As of 22 October 2026, OpenAI’s dots are unavailable to ChatGPT Pro users in the EU. OpenAI excludes the European Economic Area (which includes all EU countries), the UK and Switzerland from Pro access.
[Source: OpenAI documentation](learn.chatgpt.com/docs/dots)


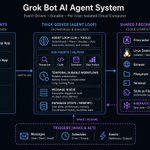
So finally Anthropic has stepped into personal assistant race. Now Duet will be backed by most capable model Opus 5.5 or something more better.
Anthropic played really well here! They did not get the first movers advantage but seems they will gain lots from Grok Bot and other personal assistants market share.
OpenAI should have let Dots allowed to lower end plans, that was mistake and still time to correct it. @thsottiaux still a time to correct on that, if the decision in your hand!

Its been around month Opus 5.5 has been released but kinda wonder we didn't have any new model that can beat Opus 5.5 in terms of pricing and quality.
Anthropic providing the best model of this AI race with cheaper rate and best quality is nearly becoming impossible to beat.
Did we find a perfect balance in pricing and quality with Opus 5.5?

Grok Bot: Getting supported by Opus 5.5
Claude: In its own world, cooking everyday
OpenAI: Buying time with reset, desperately needs new model on par with Opus
Google: what they are doing, no one knows.

AI/SI users are incredibly fickle, especially here on 𝕏. Sentiment can shift dramatically in a matter of days, and yesterday's favorite can quickly become today's disappointment.
I follow this space very closely, and I've noticed some interesting trends in how users currently feel about the major AI players:
🟢 Grok Bot: Overwhelmingly positive sentiment. Users are raving about it, and the user base is growing at an astonishing rate.
🟢 Anthropic / Claude: Very positive. Opus 5.5 has earned a reputation as the best coding model, and developers seem genuinely impressed.
🔴 OpenAI: Sentiment is turning increasingly negative. Users are frustrated with usage limits, disappointing coding performance, and persistent Codex bugs and usability issues.
🔴 Google / Gemini: Surprisingly negative sentiment, even after the release of Gemini 4 Argon. The new model hasn't really turned the mood around.
These are my observations of the current mood on 𝕏, not an objective ranking of model capabilities.
And if there's one thing I've learned from watching this space, it's how quickly everything can change. One breakthrough release, one disappointing update, and the entire narrative flips.
I'm curious whether your own experience matches what I'm seeing.


From the whole saga it seems Anthropic has achieved AGI, and now they are behaving like they have seen it all.
Sure they deserved to set the rules but they can not push back others, and that's where I think OpenAI is important.
We need competition in this field to avoid major polarization and power centers.

After going through this whole thread and some of Anthropic's own docs, Dario's thinking is actually simple to follow:
Whoever is in front gets to shape the rules. Step back, and the companies that care least set the pace. So Anthropic stays in front, and wants the government holding the brakes for everyone instead of pulling its own.
Meanwhile: Haiku, Sonnet, Opus, Fable 5.5... Full speed.
And honestly? Good. I want the best model, as fast as possible, with the highest limits possible. Shipping is the only argument that actually moves this field.
My issue is the framing. "If we don't build it, someone worse will!!! ☠️" can justify any release, forever (on whatever terms Anthropic decides). Just say it: you're racing because you want to win, and because users want what's next.
Anyone thinking about what Vaibhav meant here: It's a joke from the local LLM / open-source AI crowd.
The joke
He's saying work treated them like a model that got compressed: reduced capacity, fewer resources, simpler tasks, or just dumbed down for the day.
Same person, just running in a lower-bit version.


OpenAI is coming for the software nobody wants to mess with: 30-year-old COBOL systems that banks and governments still depend on.
The best part:
It's their latest internal model, rumored to be Terra or Astra, on which they have tested this. We are gearing up for a new model from OpenAI finally after a long break!

Our latest model advances bring stronger capabilities for building and migrating software in low-resource programming languages such as COBOL, Fortran, and Visual Basic.
These languages power software that banks, governments, and businesses depend on. Progress here means understanding decades of business logic and helping developers modernize those systems while preserving what works.
We’re building these capabilities around the challenges developers and enterprise customers bring us. If your team is working on these systems, tell us which languages and workflows we should tackle next.
openai.com/index/low-resourc…
The best thing would be to let users know in advance what amount of token/usage they are getting in respective plans, and then per each prompt to list it out how much token and usage it took to get done that task.
This way it would be both OAI, and users can track better way what is going on. This is not criticism but an actual need of the hour. Currently, no one knows what amount they get and how it gets calculated.
If a longer thread is one of them, then let the user know that this has grown; start a new one, so it saves them actual usage, and you don't hear this thing again.